Li Lin

Li Lin 林立

Senior AI Engineer

CATL Hong Kong Research Institute (HKRI)

PhD, The University of Hong Kong

AI for Healthcare · AI for Science · Computer Vision · Agentic AI · Recursive Self-Improvement (RSI)

Biography

At CATL HKRI, my research spans Agentic AI and AI for Science. I study how agents improve through experience and how AI can advance materials discovery and battery characterization.

  • Recursive self-improvement (RSI) and automated agent harness optimization. I study how agents can turn recurring failures into lasting improvements. My work combines trace-guided harness optimization with multi-round evaluations of cross-task transfer and capability retention.
  • Multi-agent AutoResearch frameworks. I study how agents can carry out iterative scientific inquiry, coordinating hypothesis development, experiment design, and independent verification so that results can refine subsequent hypotheses (machine-learned force fields, materials property prediction and screening, etc.).
  • Multimodal, generalizable AI for battery characterization. I combine advanced signal processing and multimodal AI to characterize battery state and microstructure from complementary measurements, including ultrasound and scanning electron microscopy (SEM), across cells and acquisition conditions.

My interest in AI for Healthcare grew out of undergraduate research in biomedical engineering. I began working on medical imaging during my master’s studies and made it the focus of my PhD at the University of Hong Kong (doctoral thesis). I continue to develop learning methods that address challenges shared across medical image analysis tasks.

  • Data- and annotation-efficient learning. I study how to learn when expert labels are scarce and supervision is incomplete or imperfect, drawing on a range of approaches (self-supervised, weakly supervised, semi-supervised, active, and noise-robust learning, etc.).
  • Generalizable AI and foundation models. I develop multimodal representations that can transfer across imaging protocols, institutions, and tasks, and study how domain generalization and efficient adaptation can support deployment in new settings.
  • Personalized federated learning. I develop federated optimization and model personalization methods that learn across institutional data silos while accounting for differences in data distributions and supervision across sites.

For collaborations in Agentic AI, recursive self-improvement (RSI), AI for Science, AI for Healthcare, computer vision, multimodal AI, or related areas, feel free to email me or connect on WeChat. In your WeChat request, please briefly introduce yourself and mention what you’d like to discuss.

Earlier updates (2020–2026)

2026

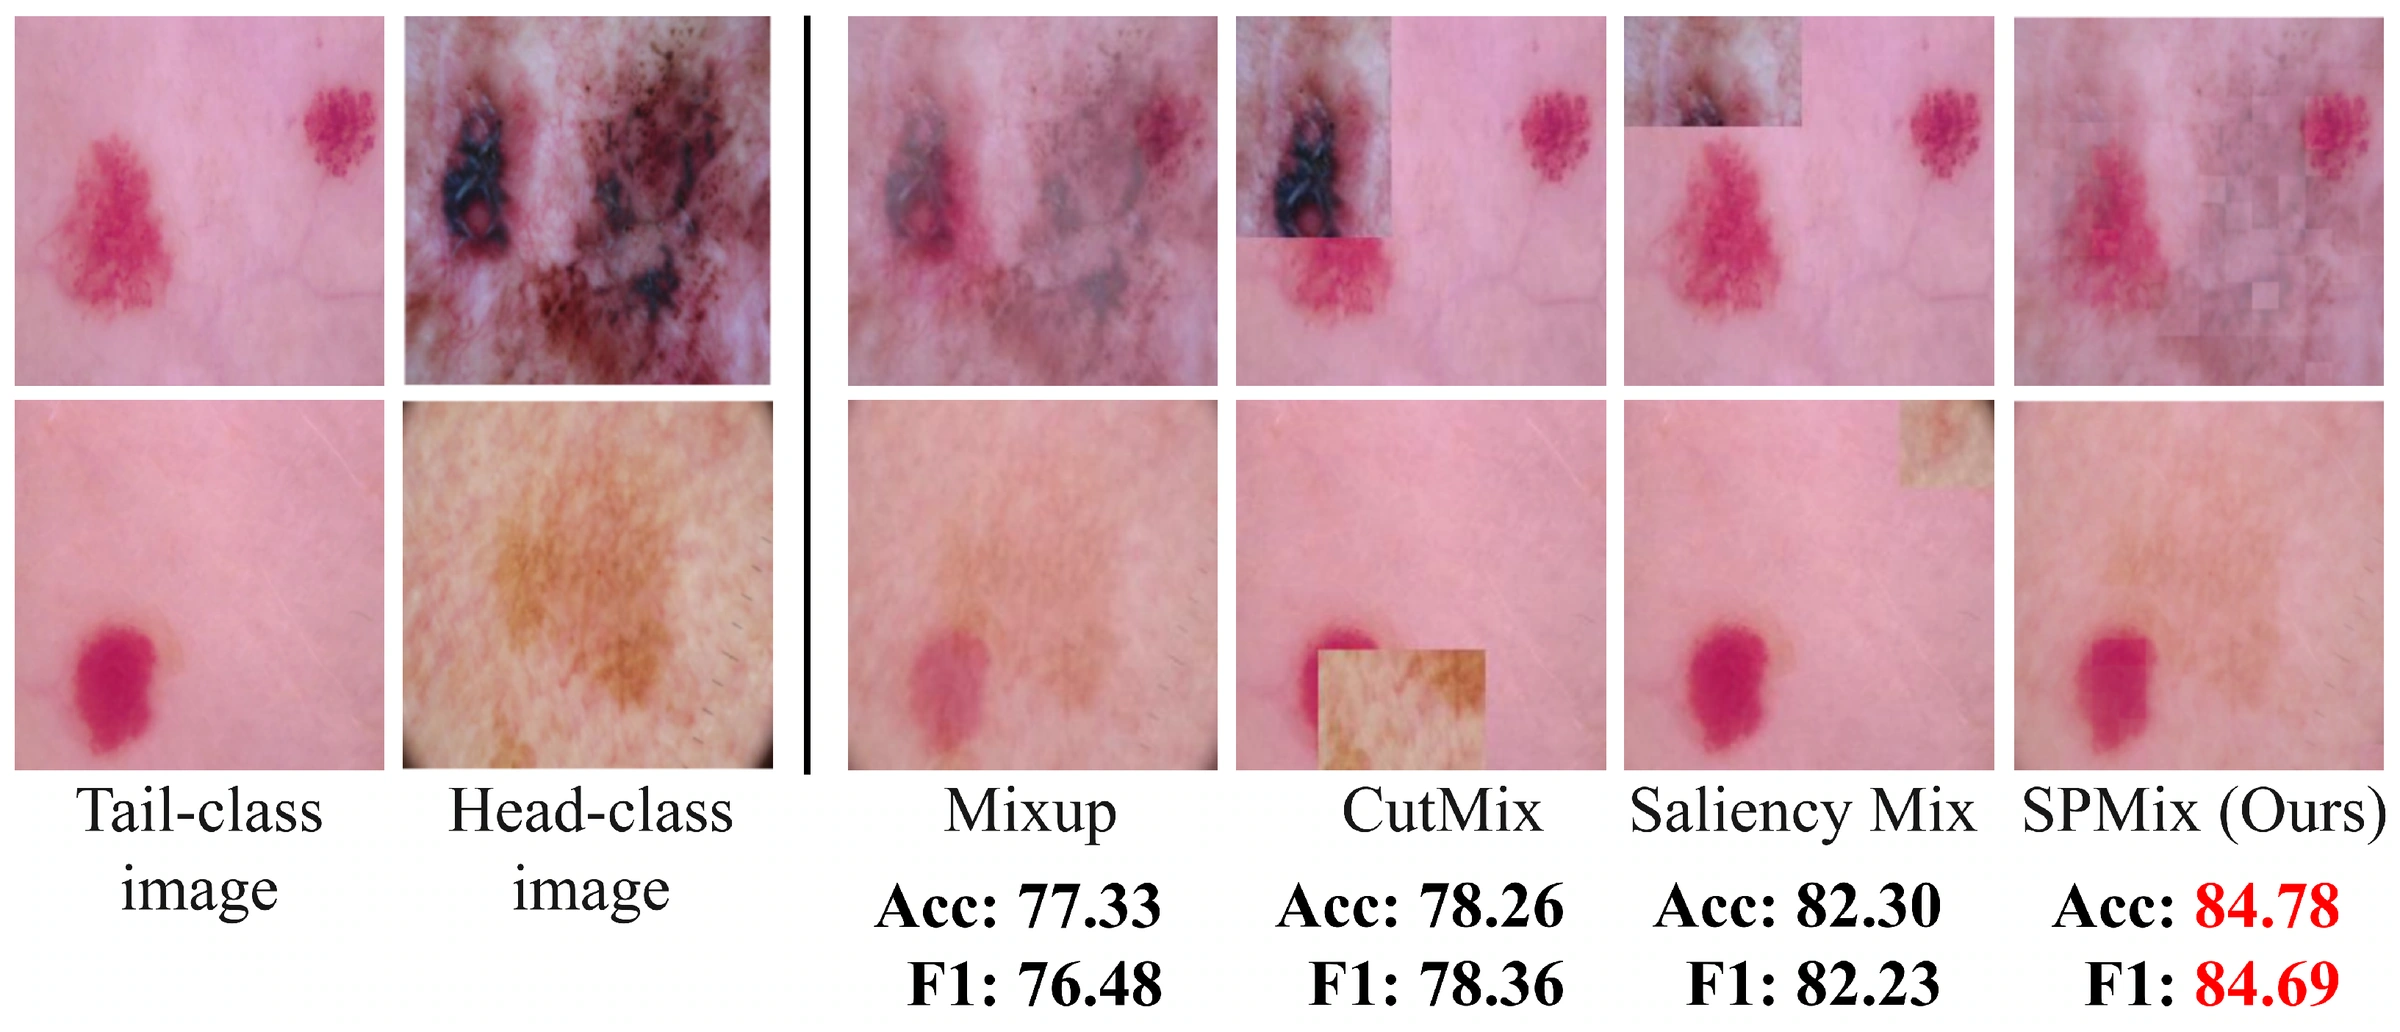
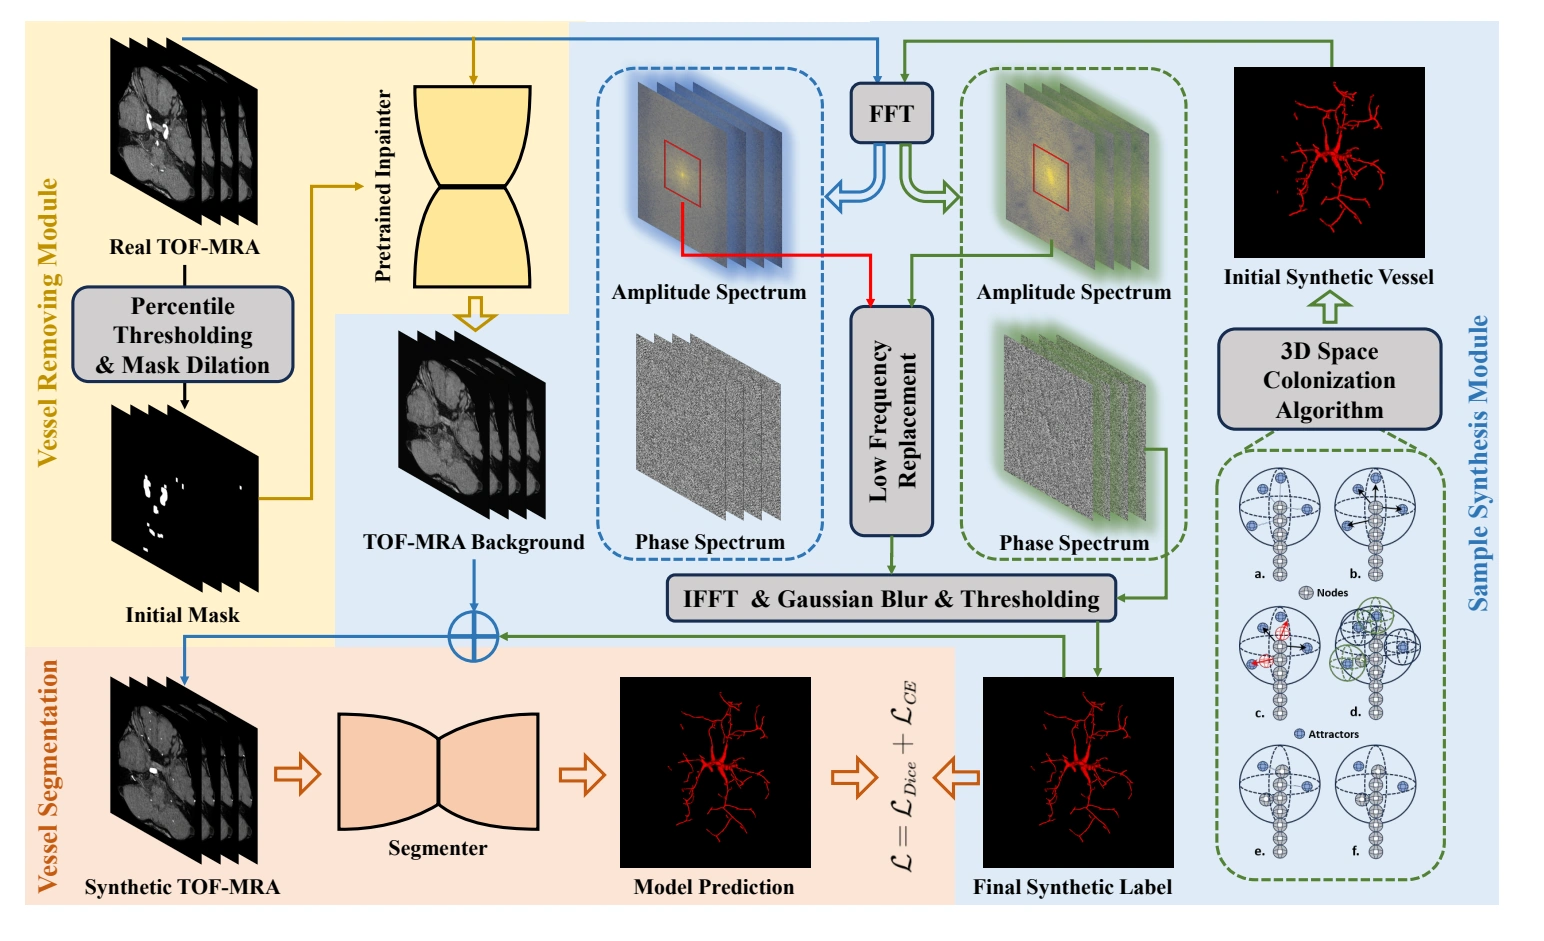
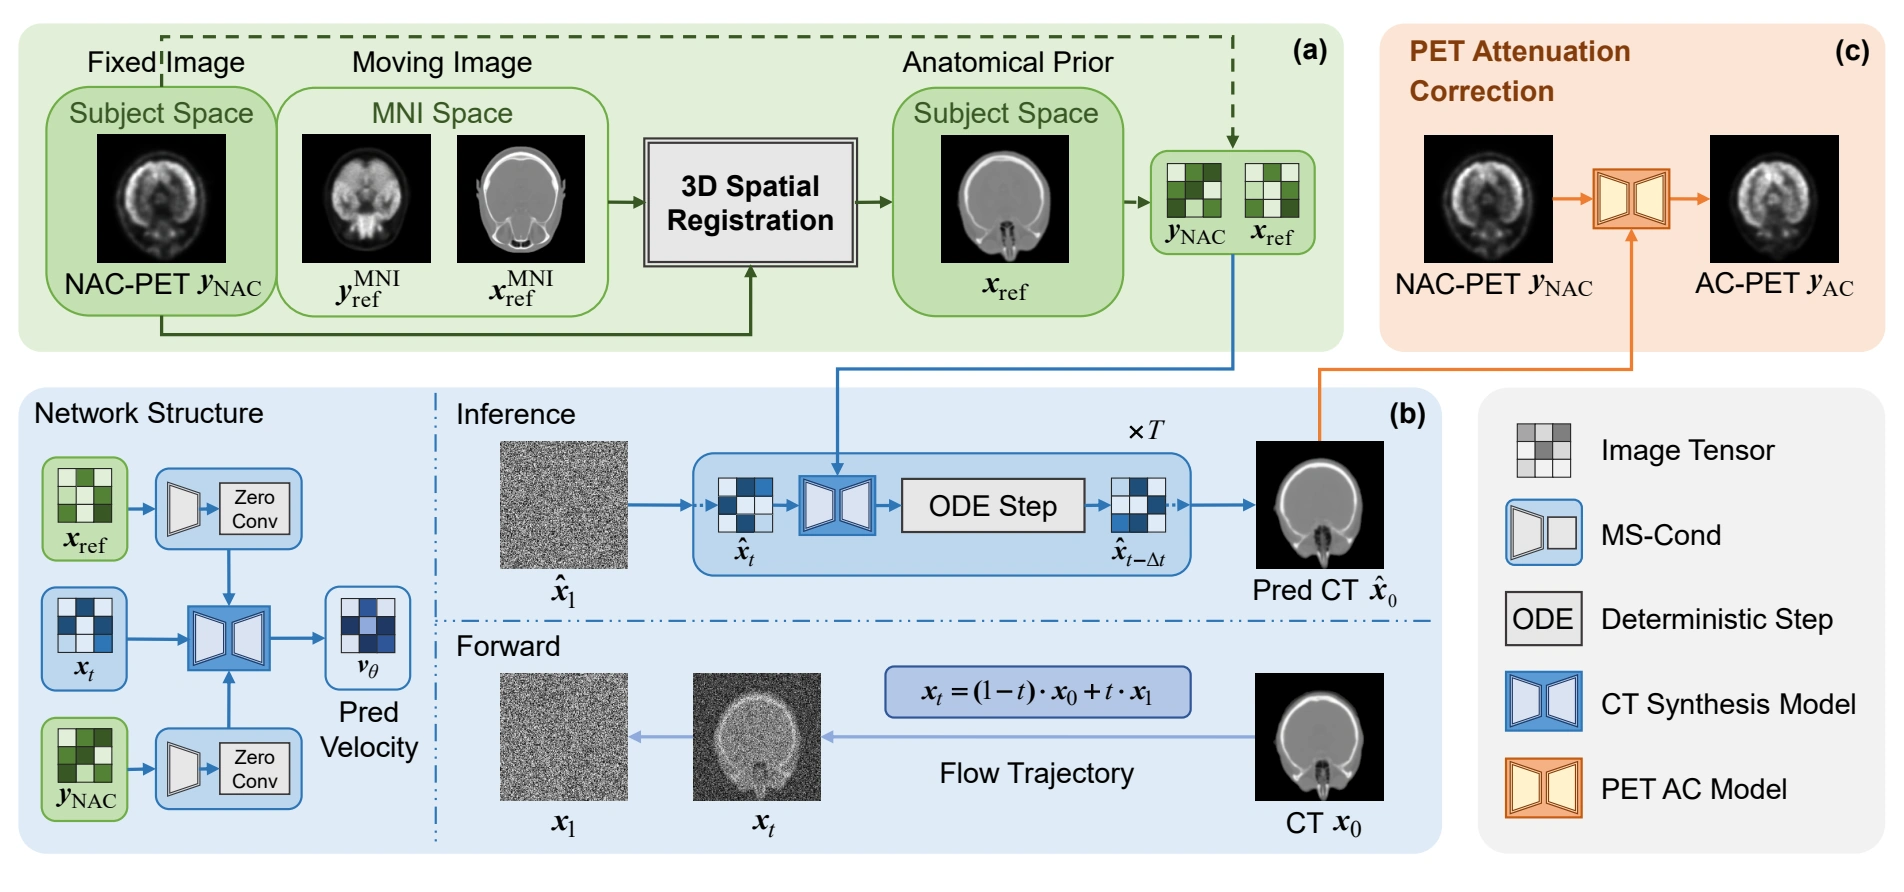
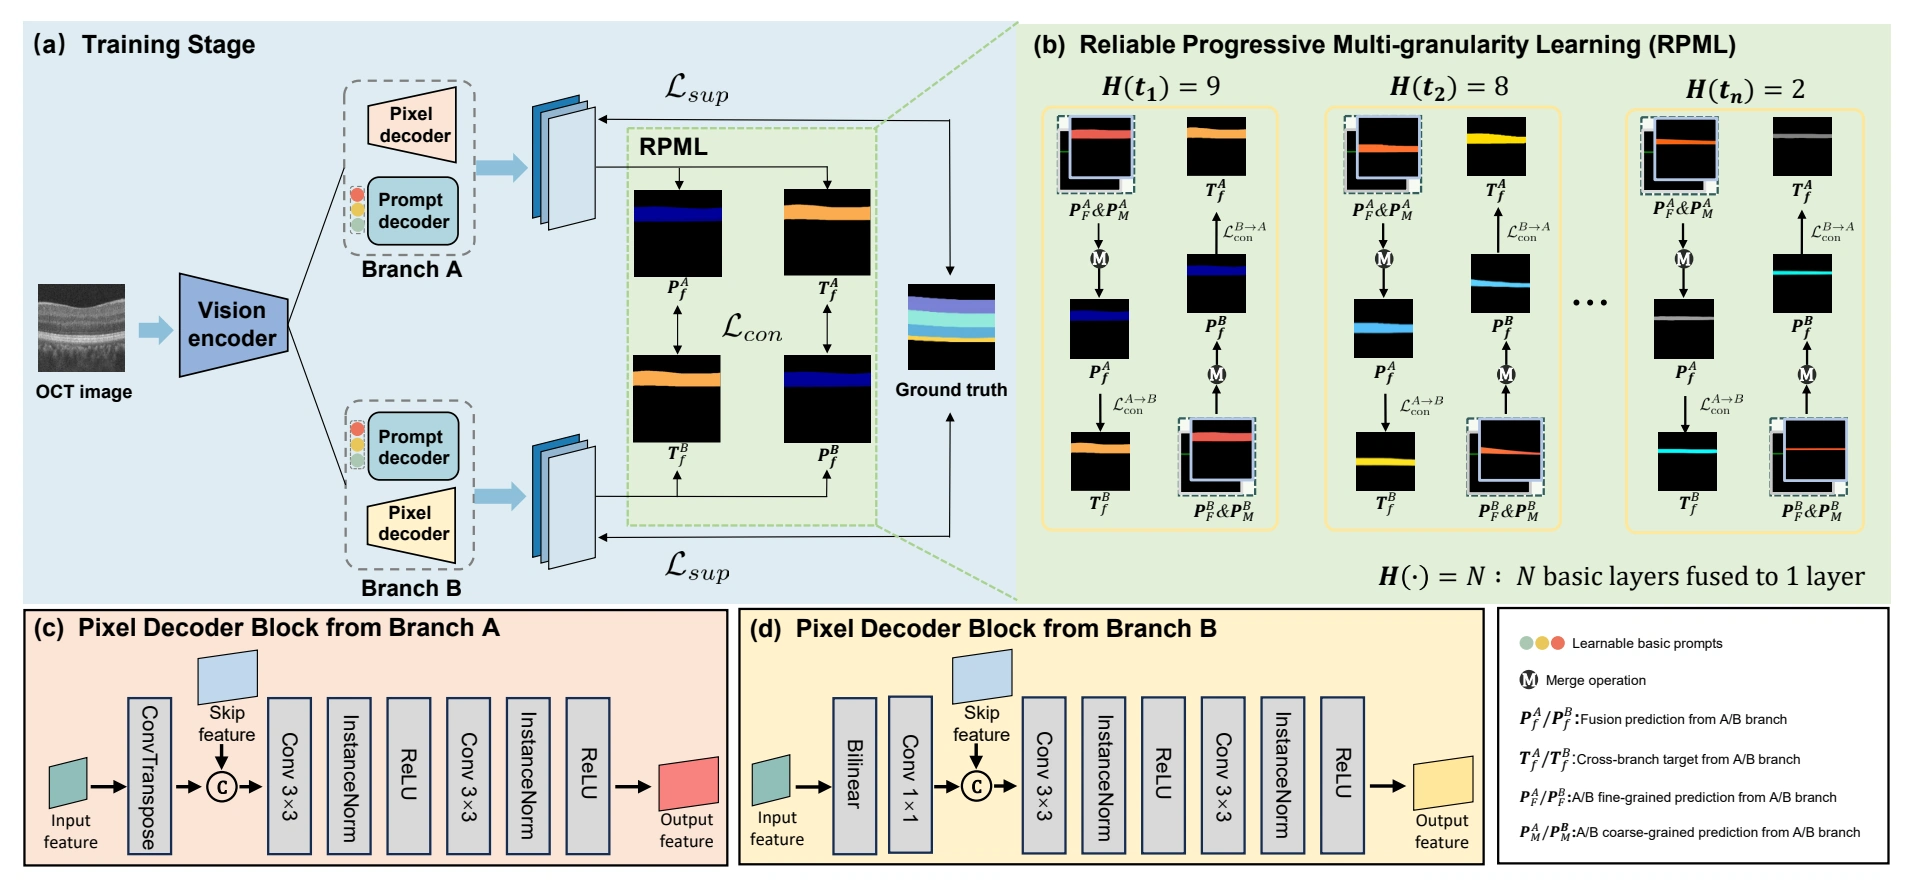
  • LUMOS uses reliability-weighted pseudo-labels to share supervision across OCT annotation levels. Two other papers at IEEE ISBI study synthetic training data for TOF-MRA vessel segmentation and anatomy-guided PET attenuation correction. TOF-MRA study DAPS

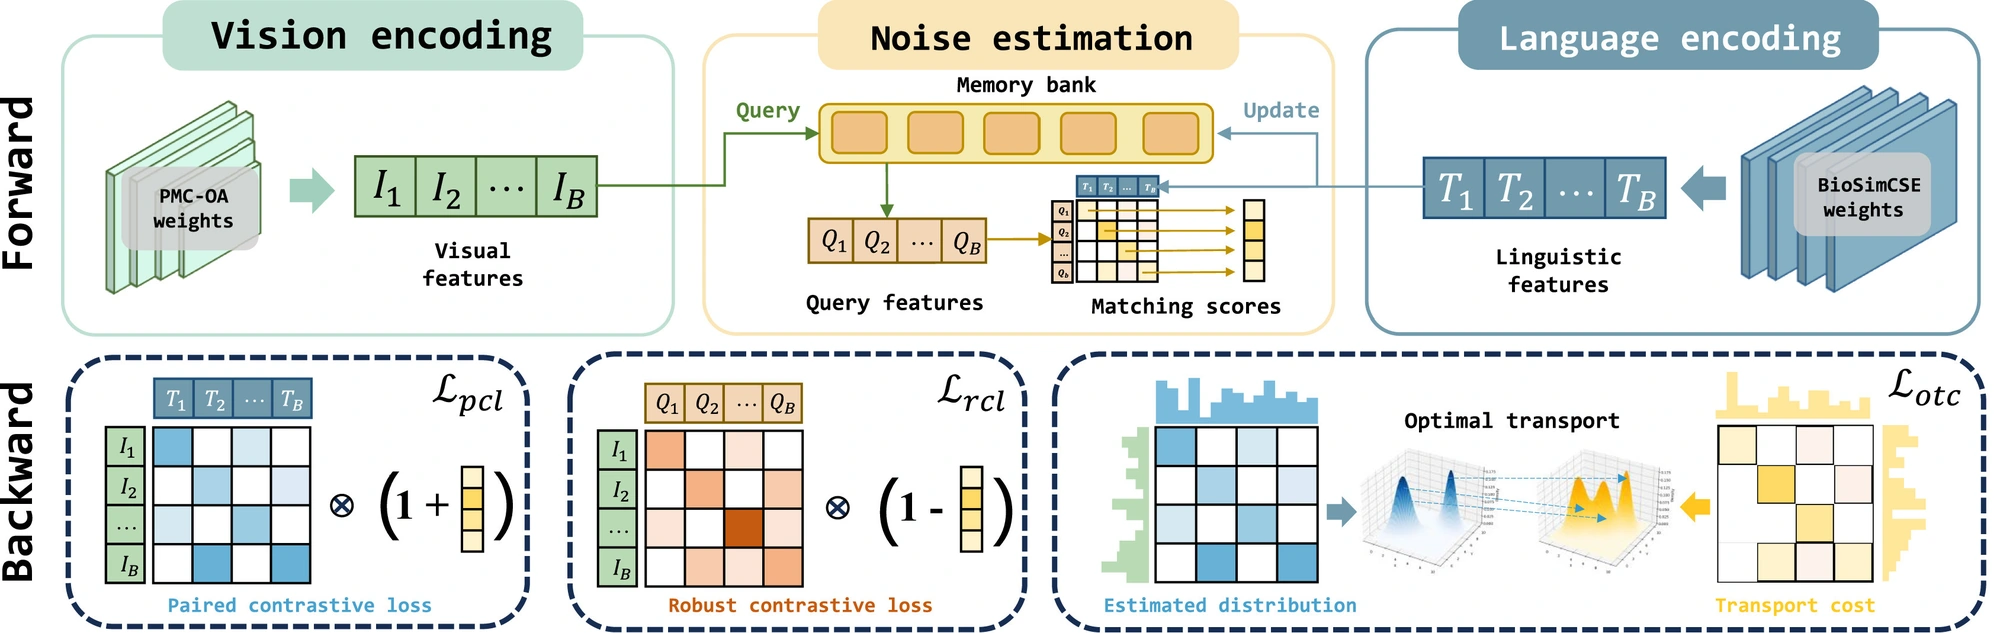
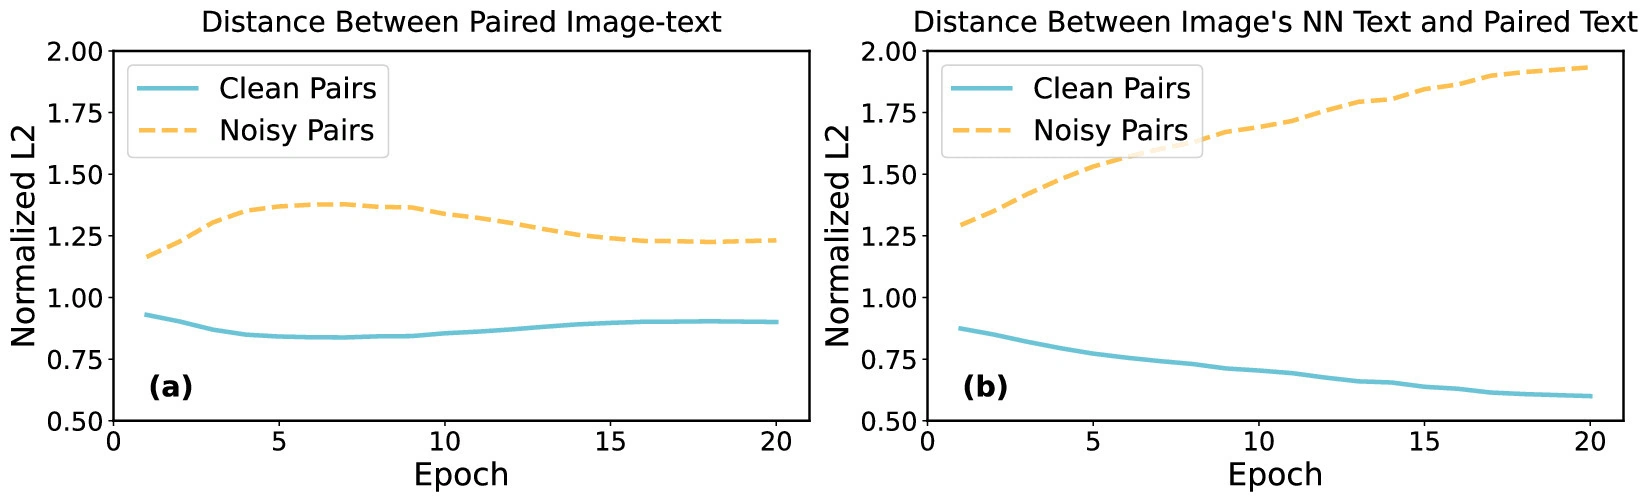
  • MIRAGE uses optimal transport and adaptive gradient balancing to reduce the effects of mismatched reports and false negatives in medical image–text pretraining. The study evaluates transfer on six tasks and appeared in Medical Image Analysis. Training code

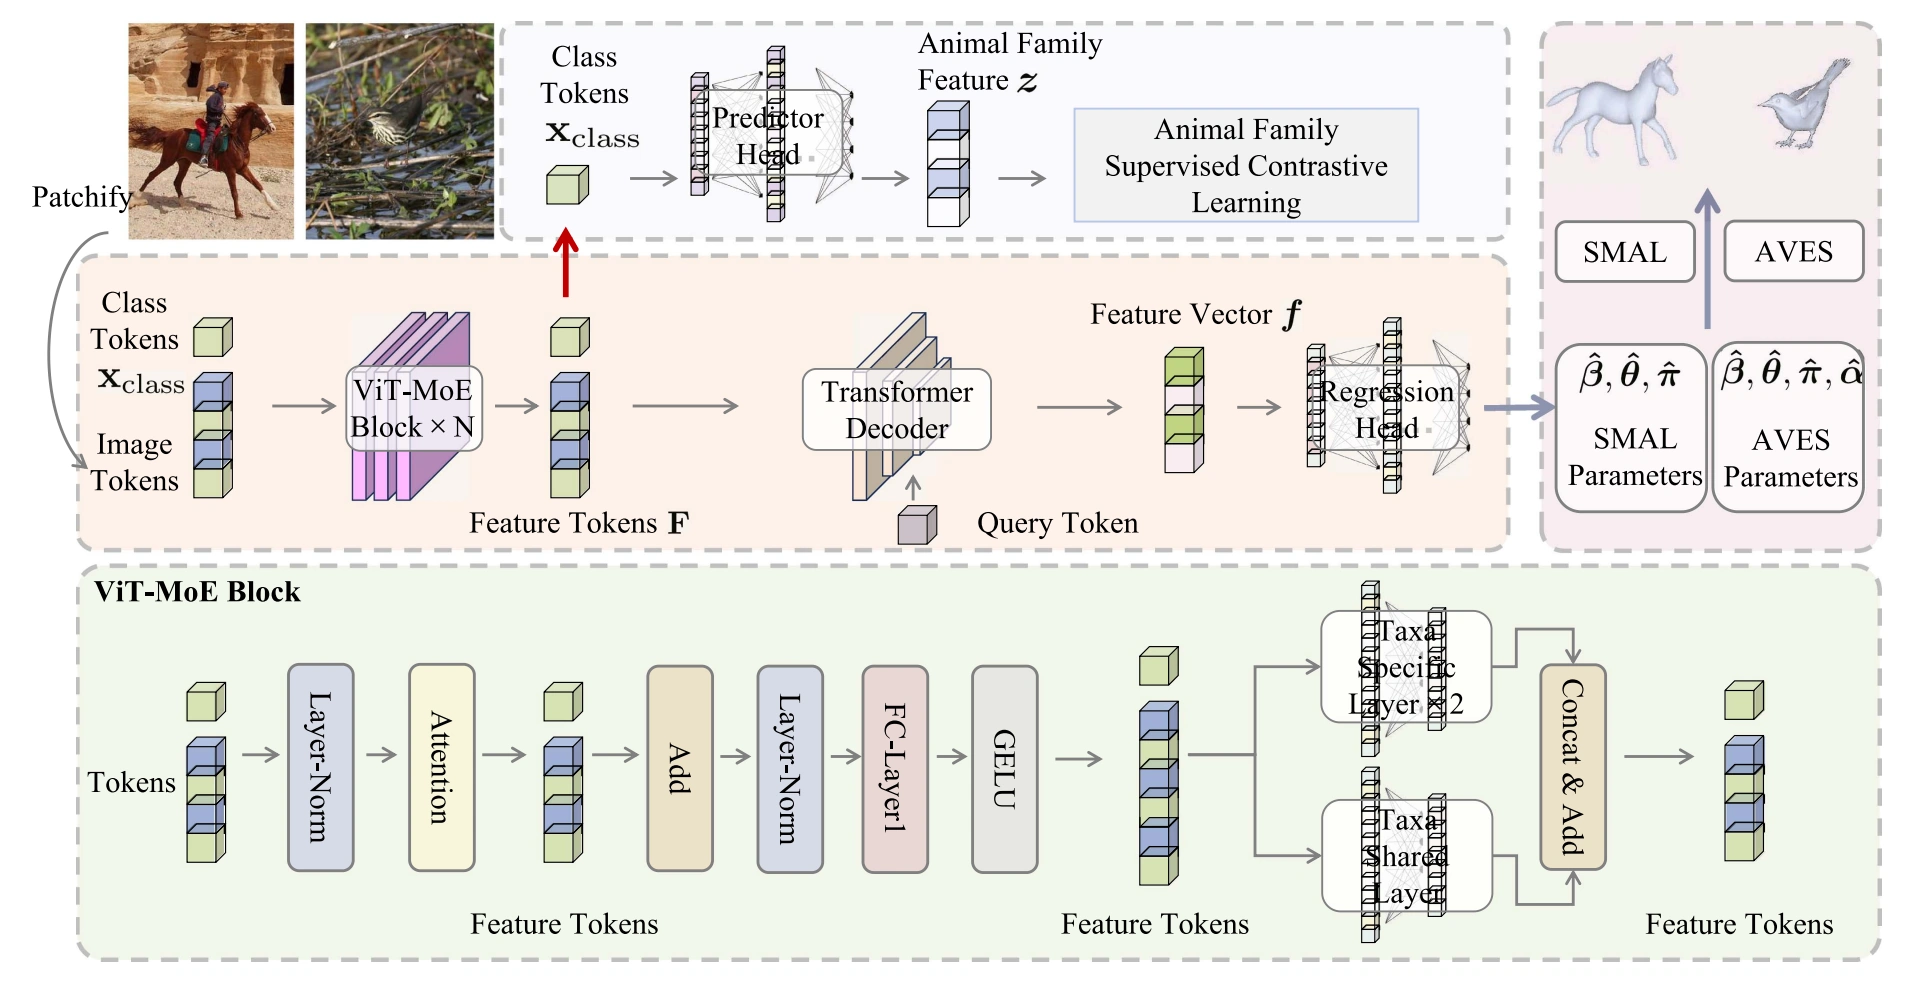
  • AniMer+ extends single-image 3D reconstruction to quadrupedal mammals and birds with shared Transformer layers and taxon-specific experts. Evaluation includes out-of-domain animals. Published in IEEE TPAMI. Project page

2025

  • CATL HKRI · Joined as a Senior AI Engineer. My work spans agent evaluation and self-improvement, autonomous research frameworks for materials, and multimodal battery characterization.

  • PhD at the University of Hong Kong · Completed my PhD in Electrical and Electronic Engineering with joint training at SUSTech. My thesis studies efficient learning from sparse annotations and personalized federated learning across medical imaging sites.

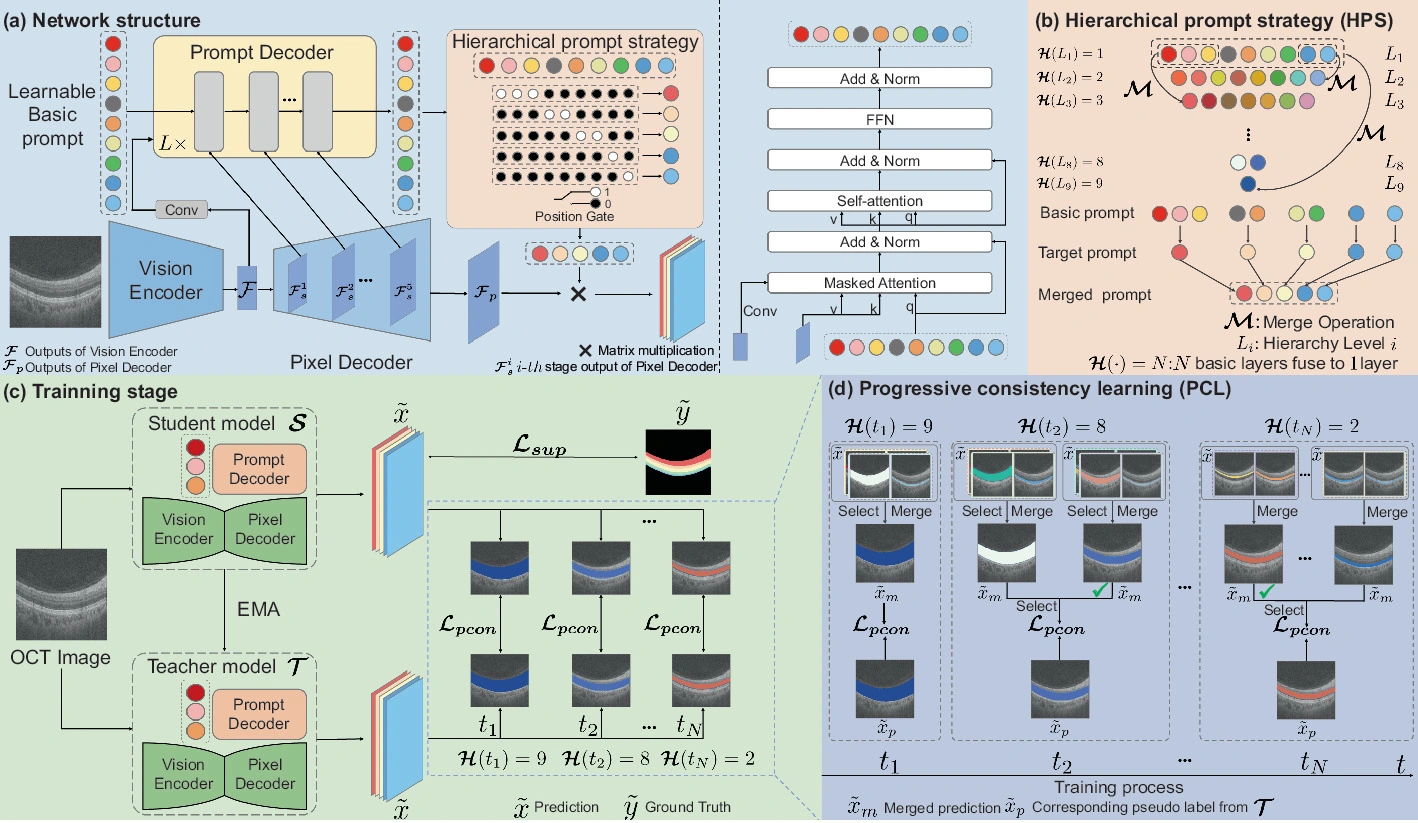
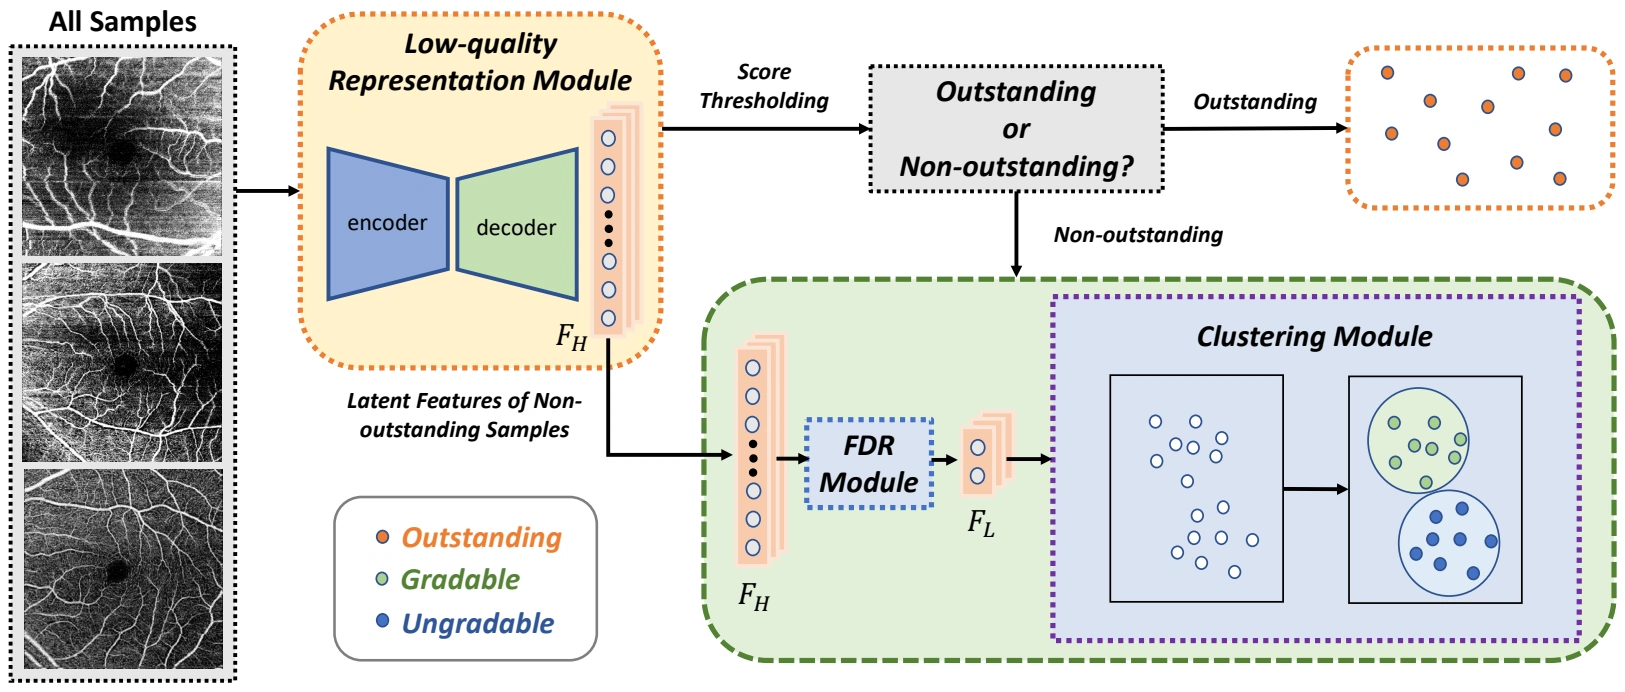
  • UniOCTSeg combines hierarchical prompts with progressive consistency training to integrate six retinal-layer labeling schemes in one model. Evaluated on eight OCT datasets and published at MICCAI. Code

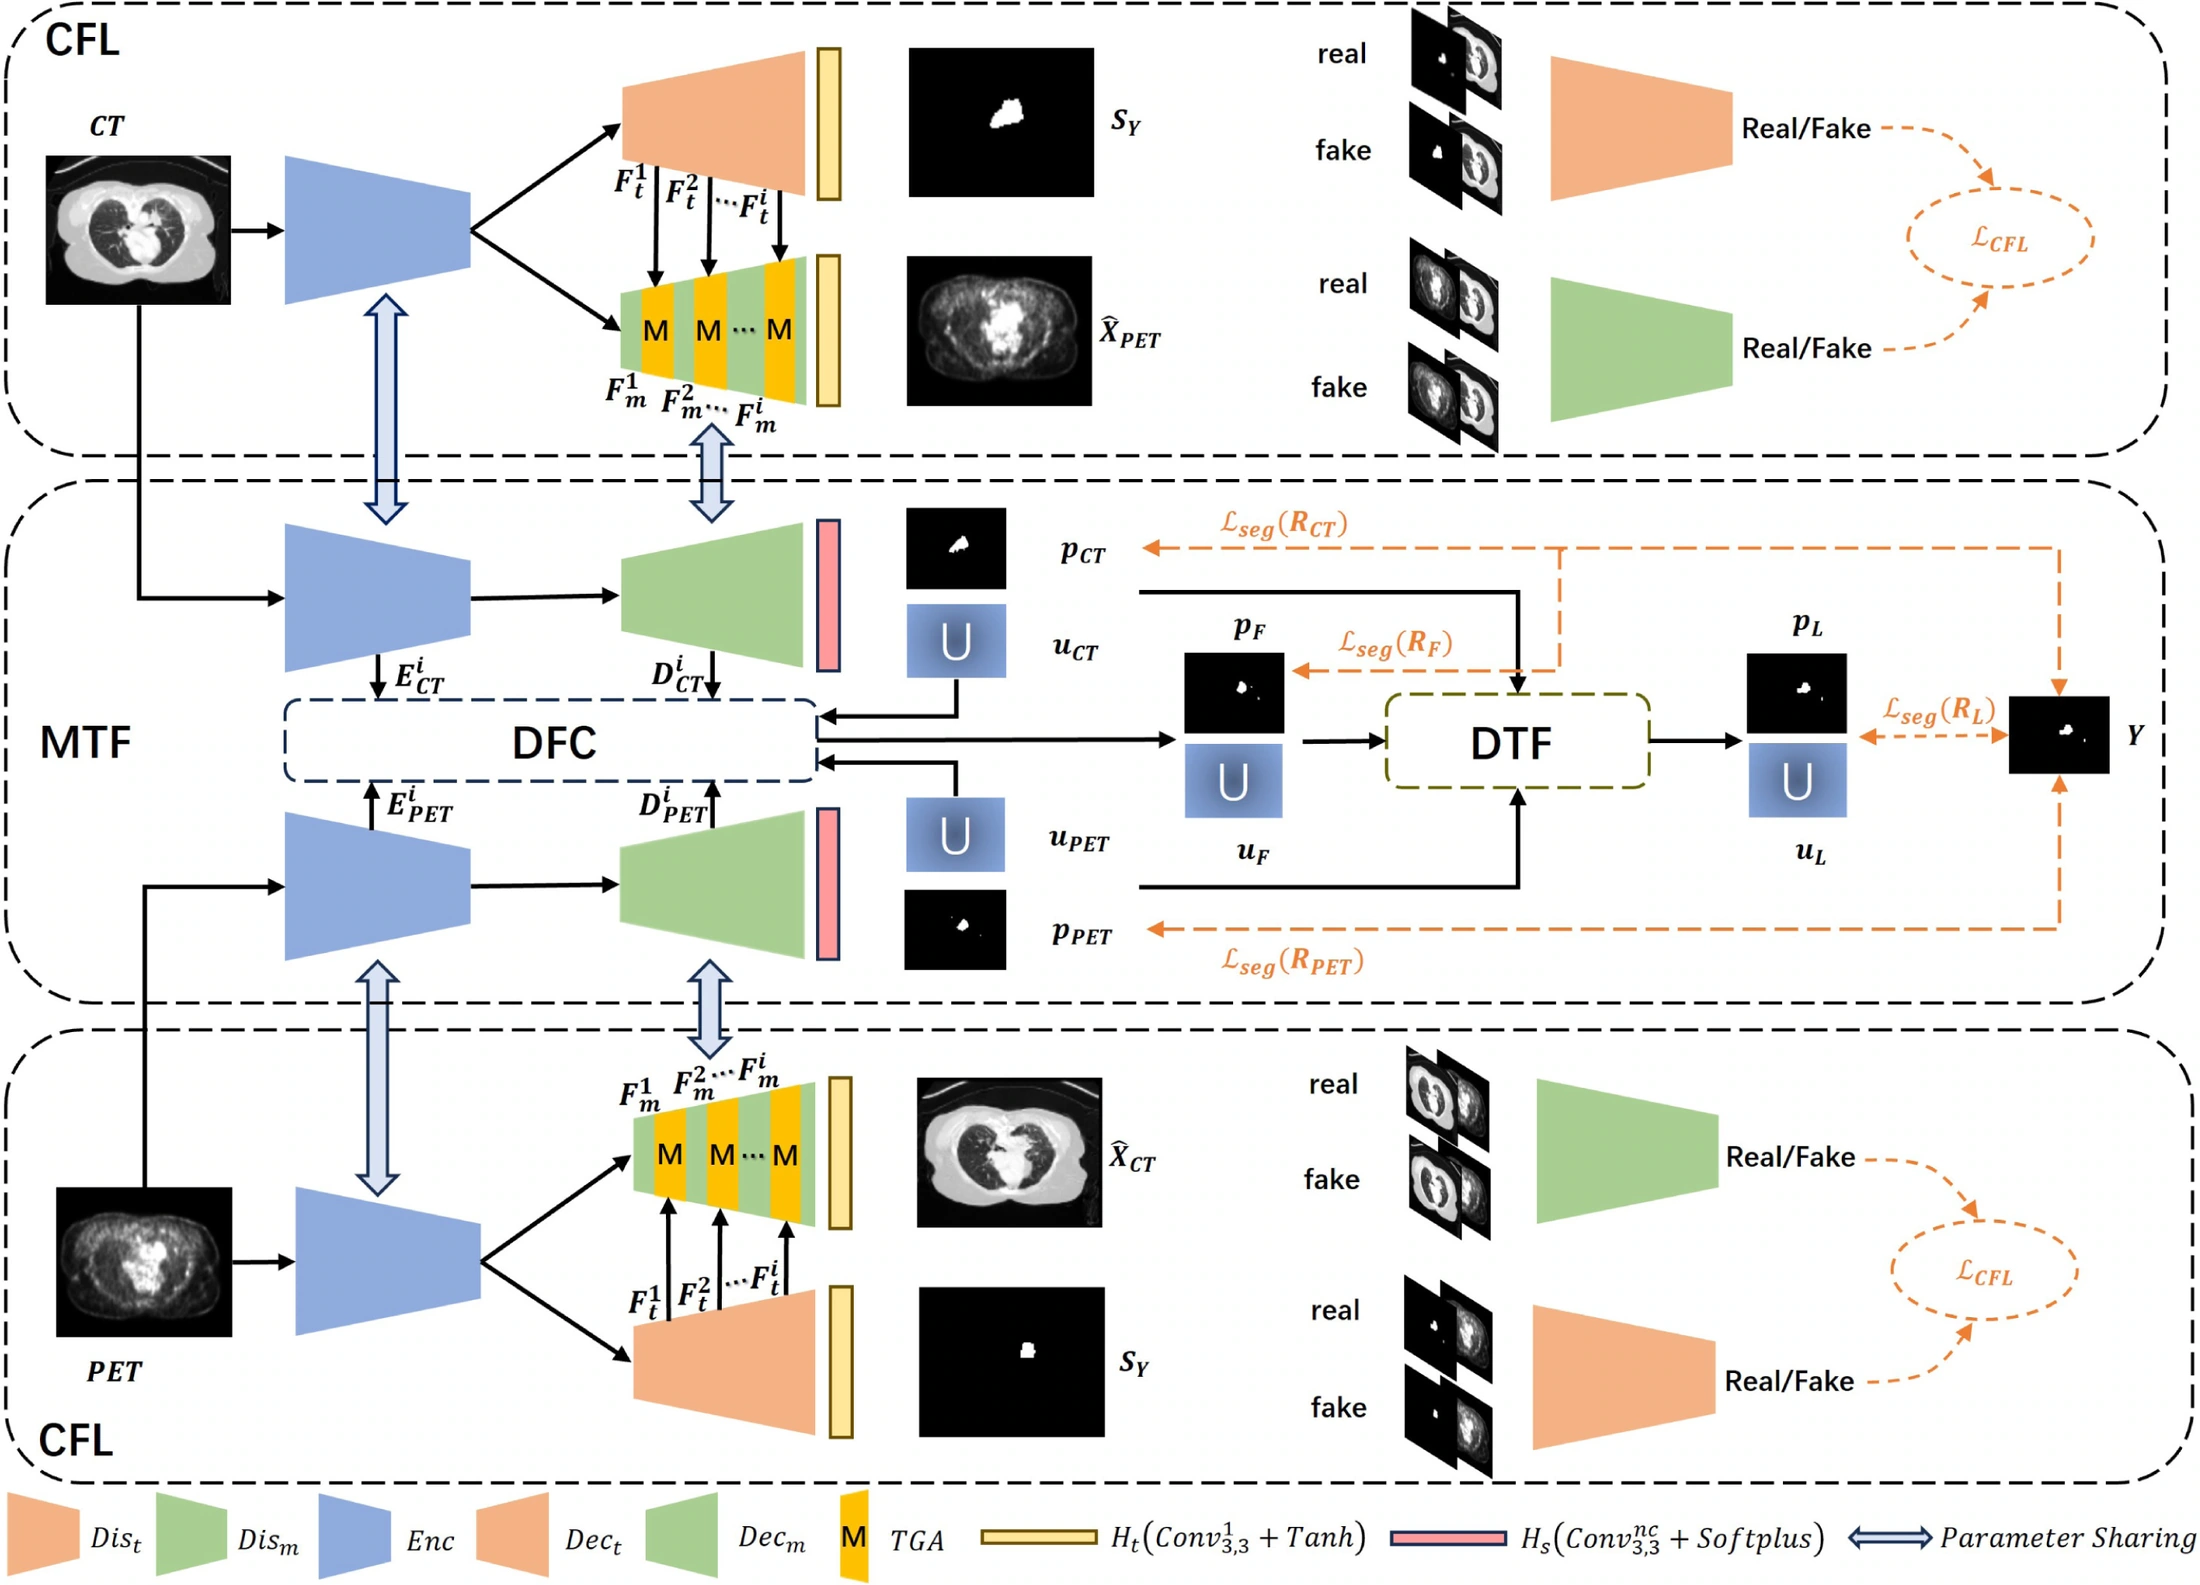
  • MEFN calibrates uncertainty in PET and CT separately before fusing voxel-level evidence. Evaluated for both tumor delineation and uncertainty on AutoPET and HECKTOR. Published in Knowledge-Based Systems. Code

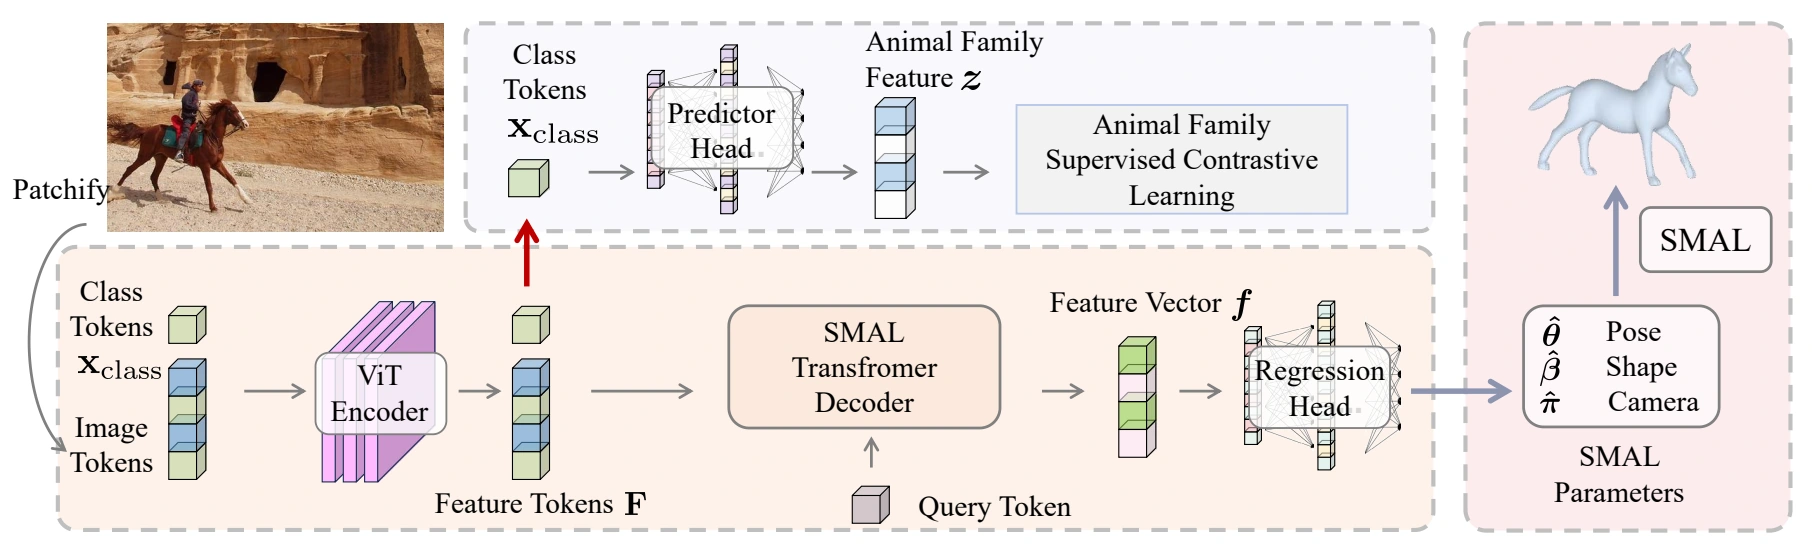
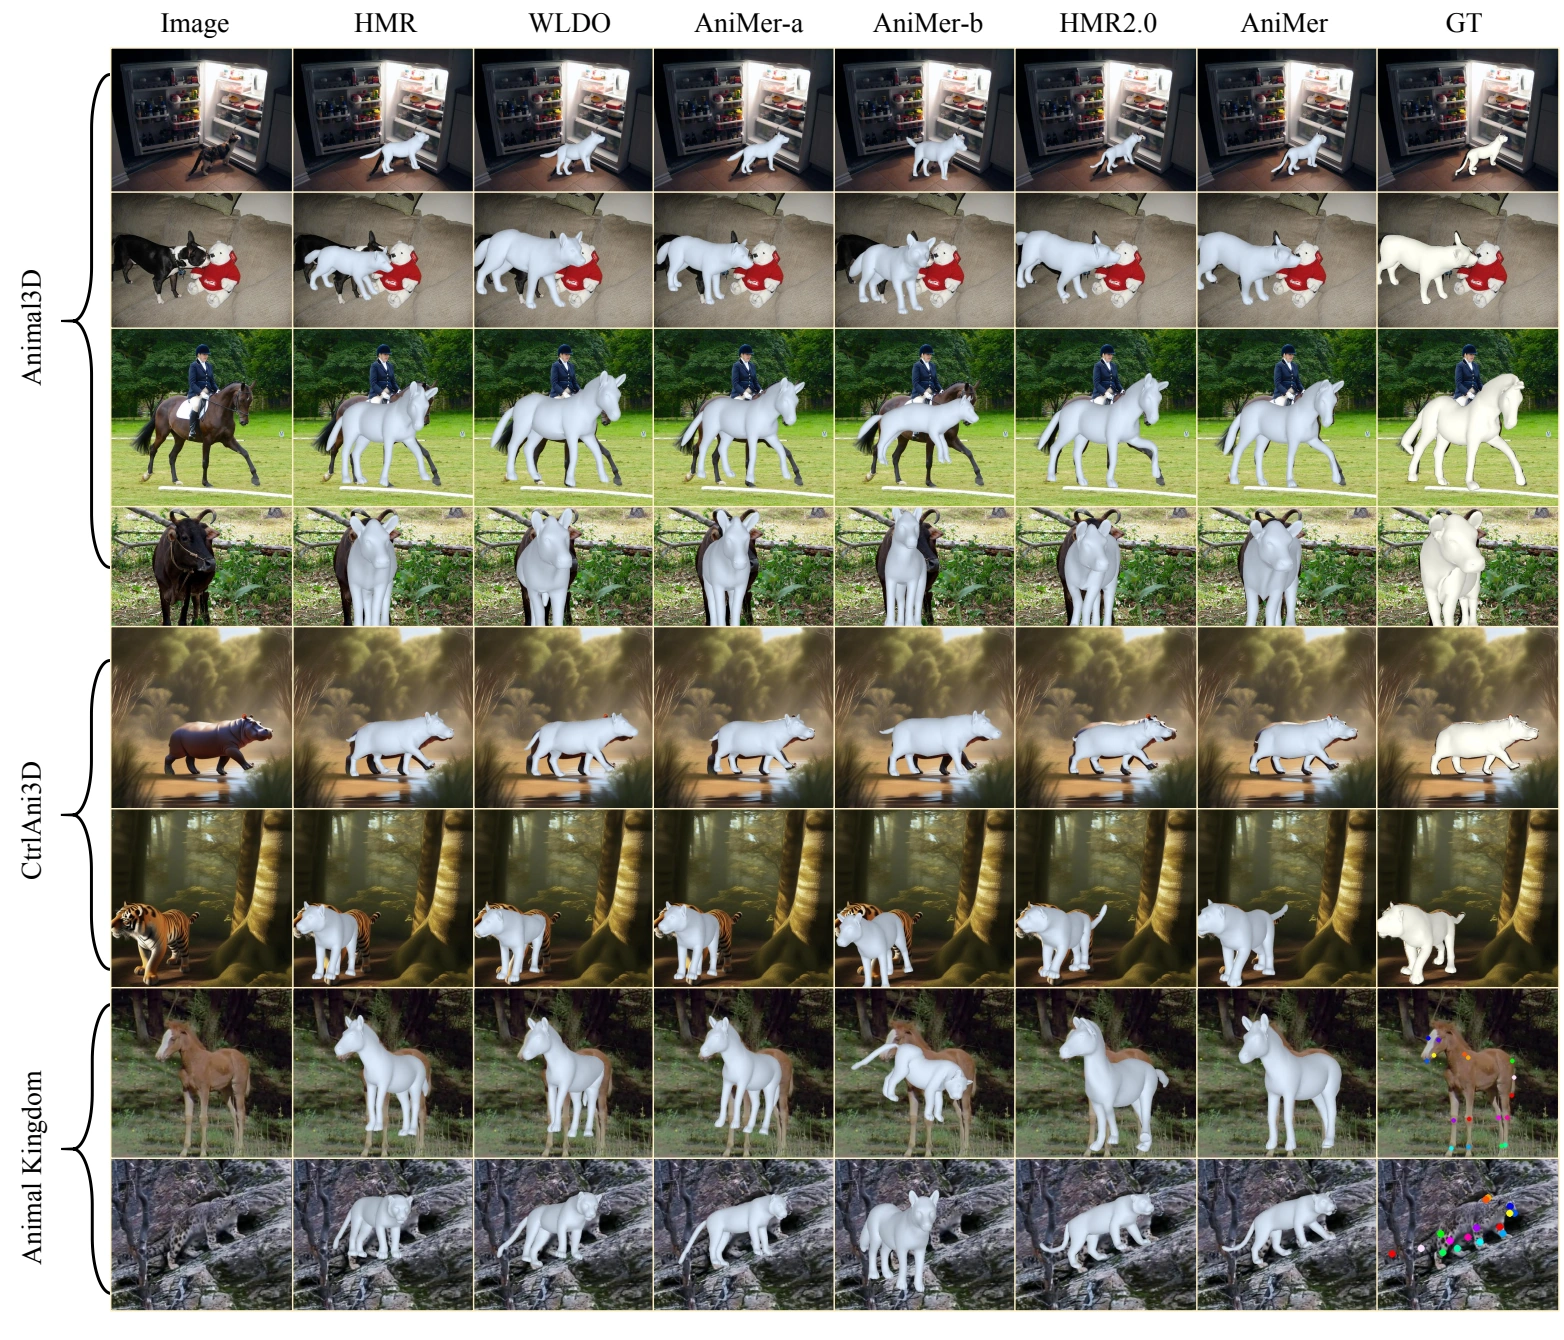
  • AniMer uses family-level supervision to learn 3D pose and shape across quadrupeds. Its CtrlAni3D training data pair synthetic images with aligned mesh annotations. Published at CVPR. Code

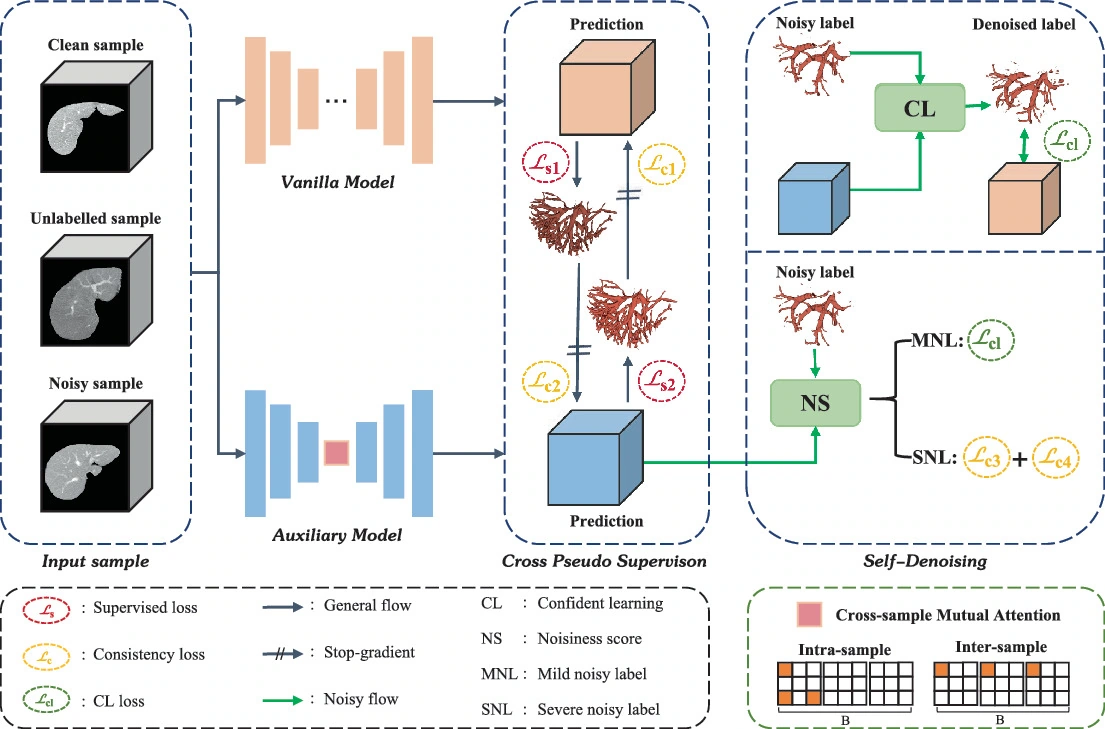
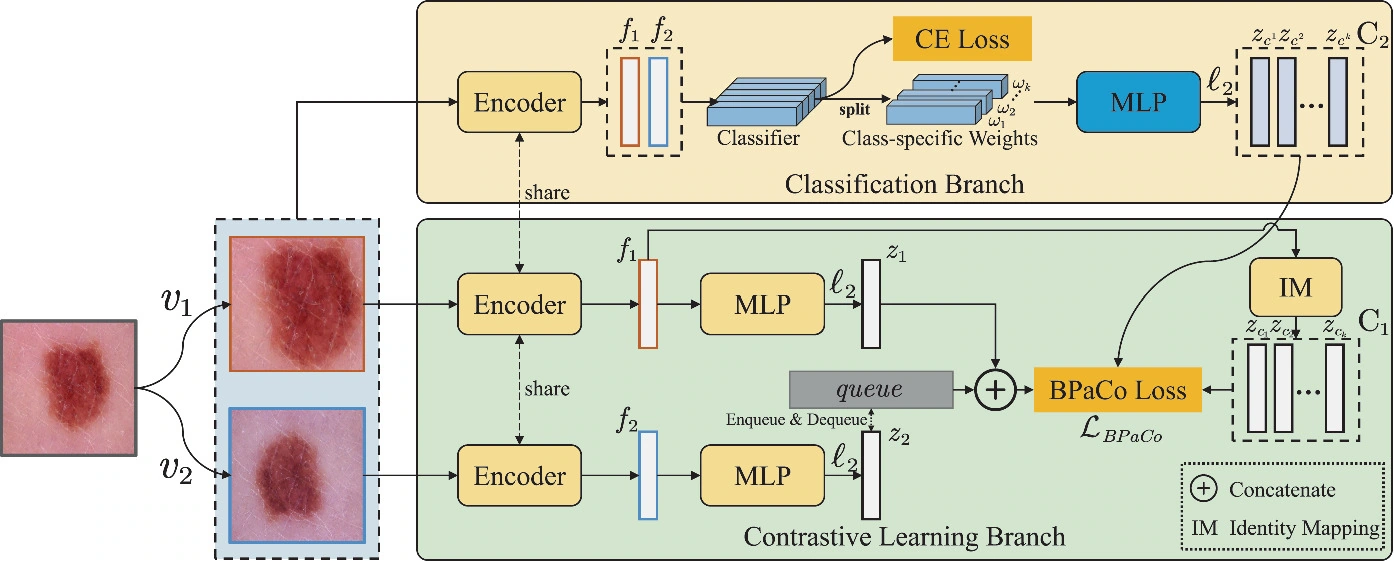
  • ProCNS calibrates feature prototypes as training progresses and suppresses unreliable pseudo-labels to limit error accumulation under sparse supervision. Published in IEEE JBHI. Code

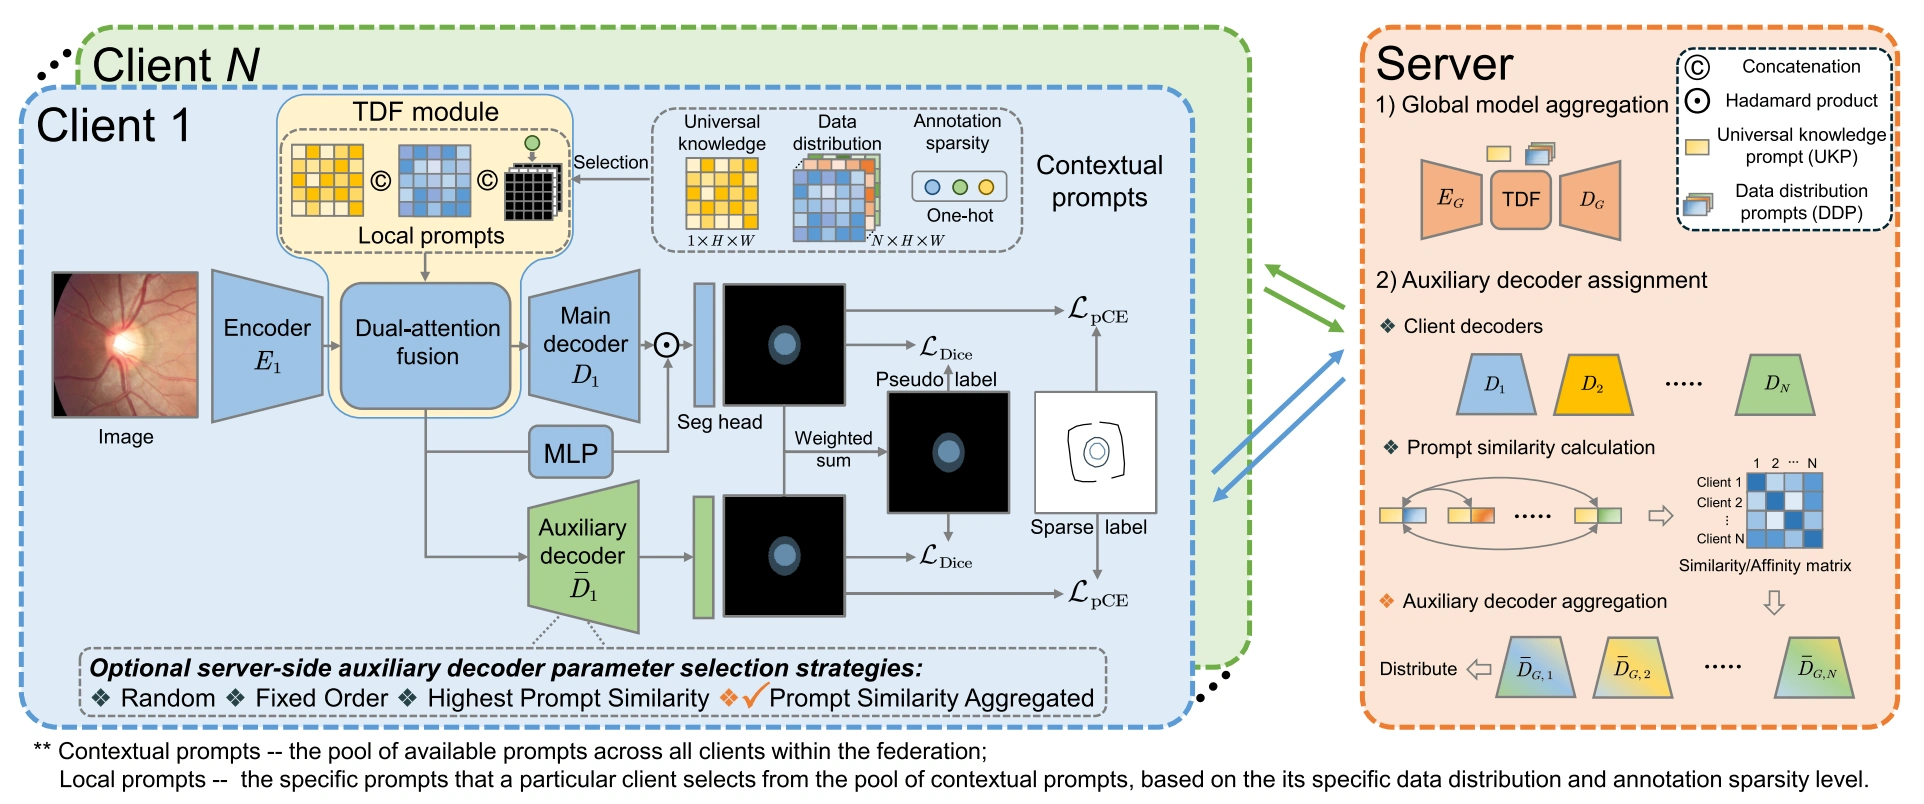
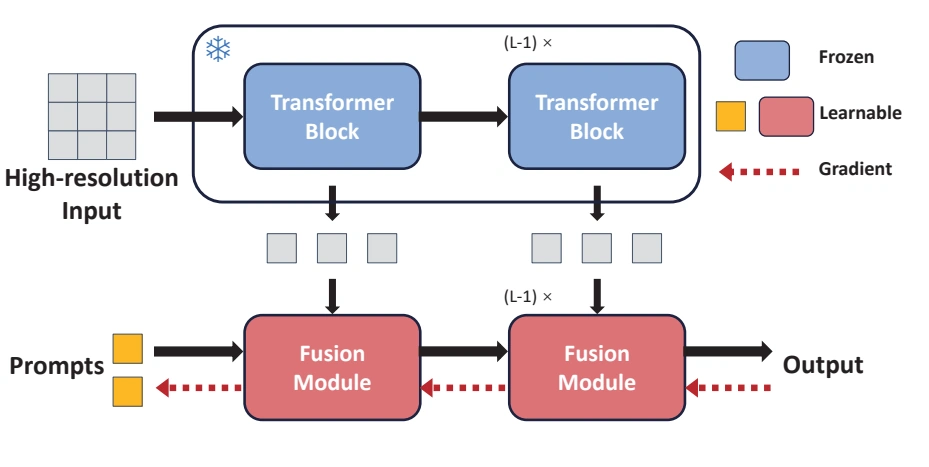
  • FedLPPA uses personalized prompts and parameter-wise aggregation to account for differences in institutional data distributions and weak annotation protocols. Evaluated across four segmentation tasks and published in IEEE TMI. Code

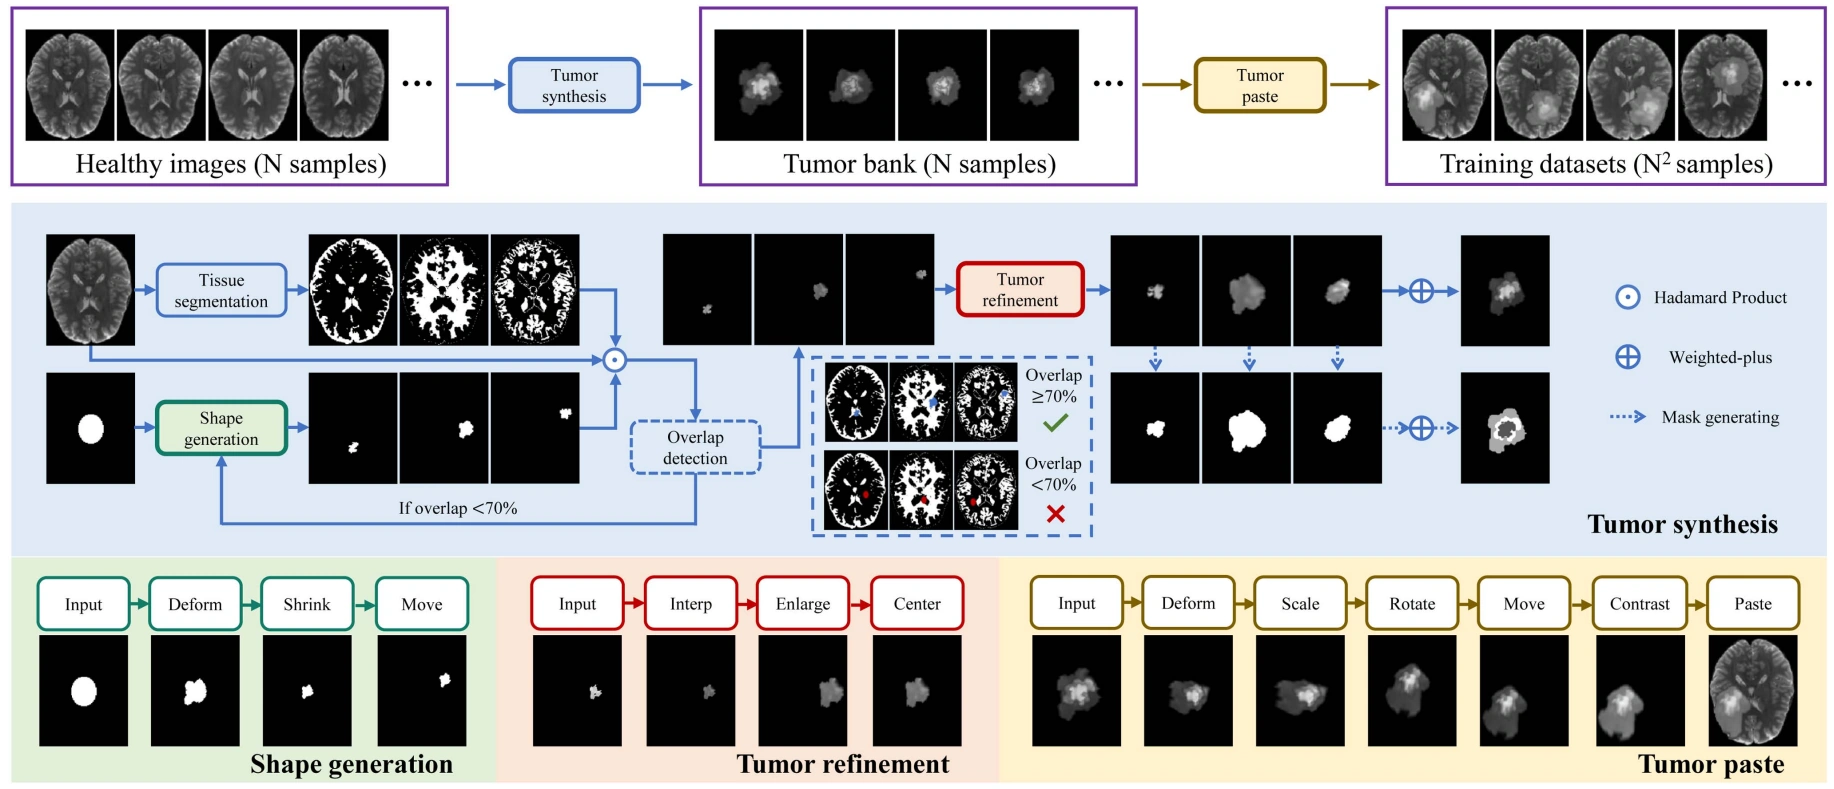
  • LF-SynthSeg uses healthy tissue anatomy and intensity to synthesize tumor training pairs, enabling brain tumor segmentation without manually drawn tumor masks. Published in IEEE JBHI. Code

2024

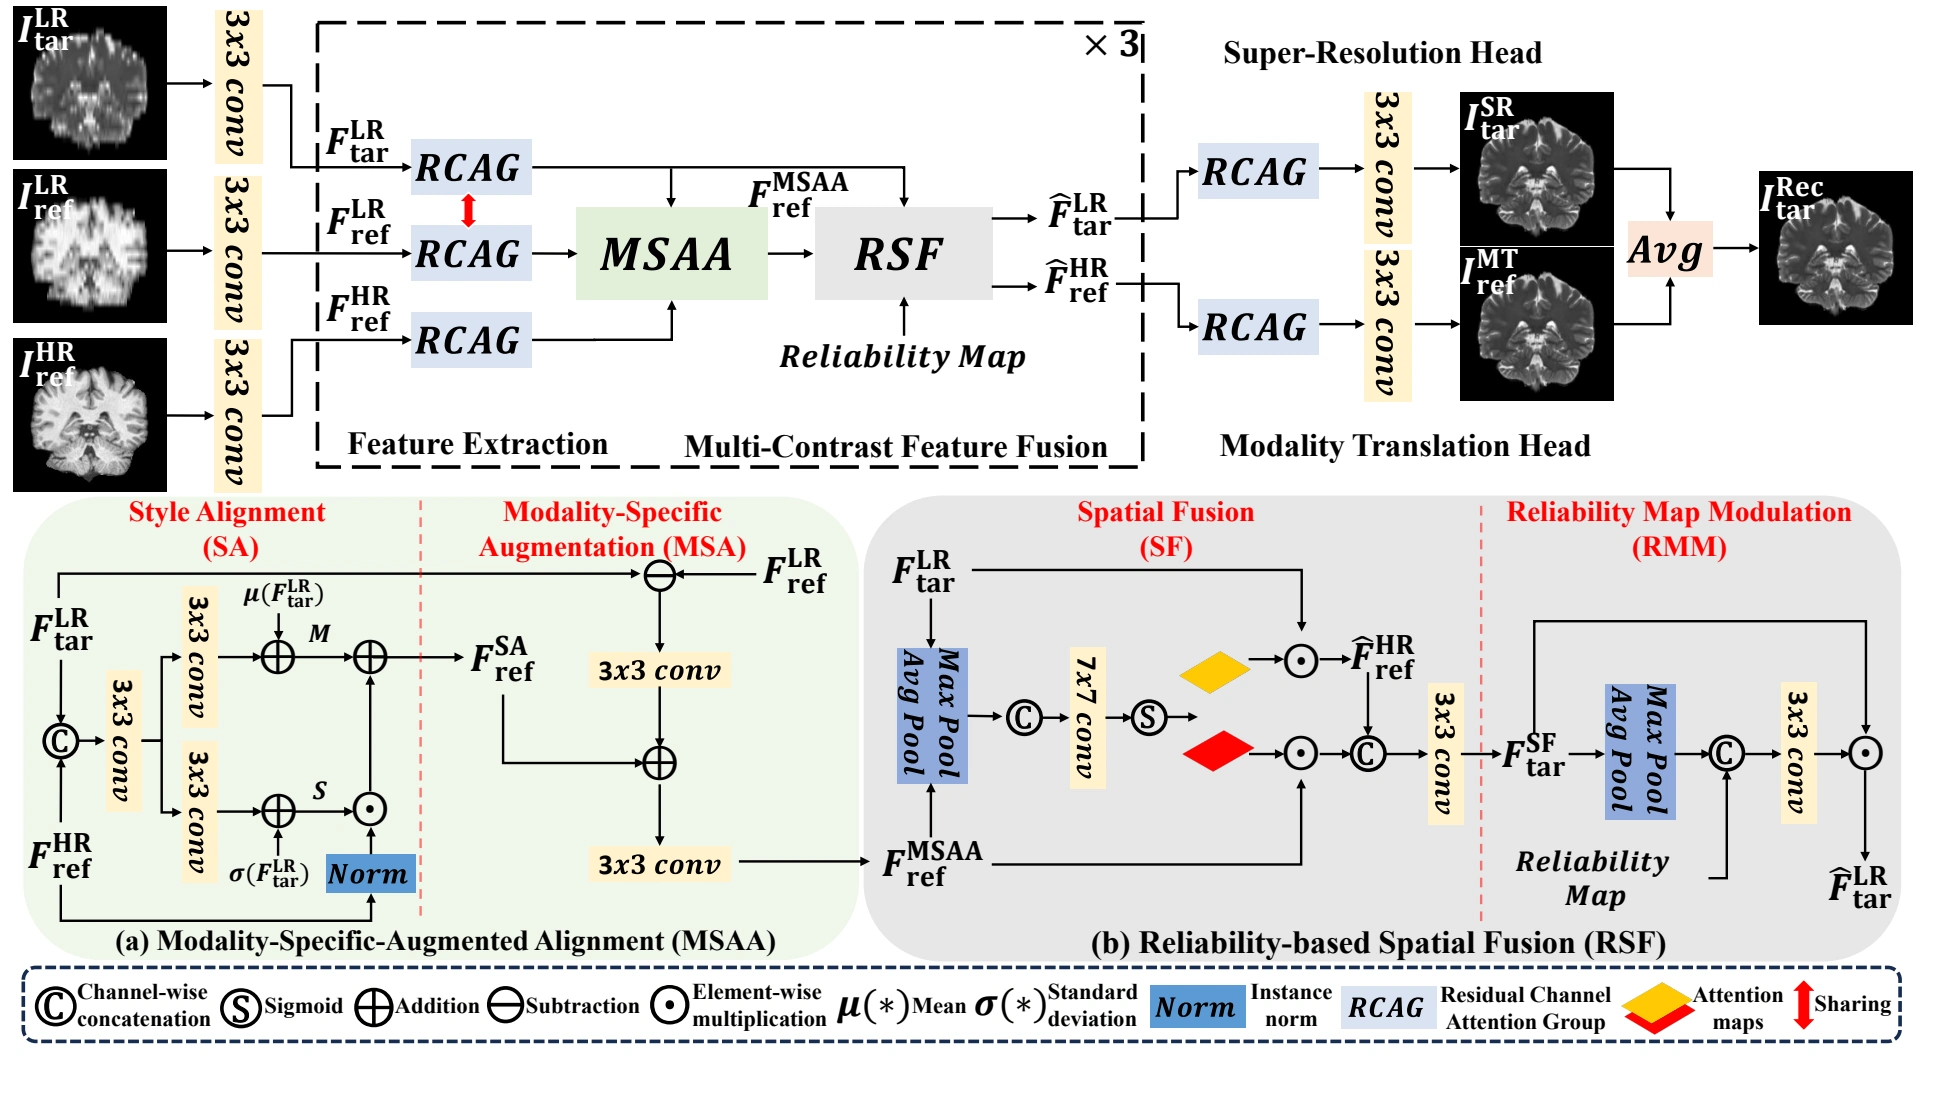
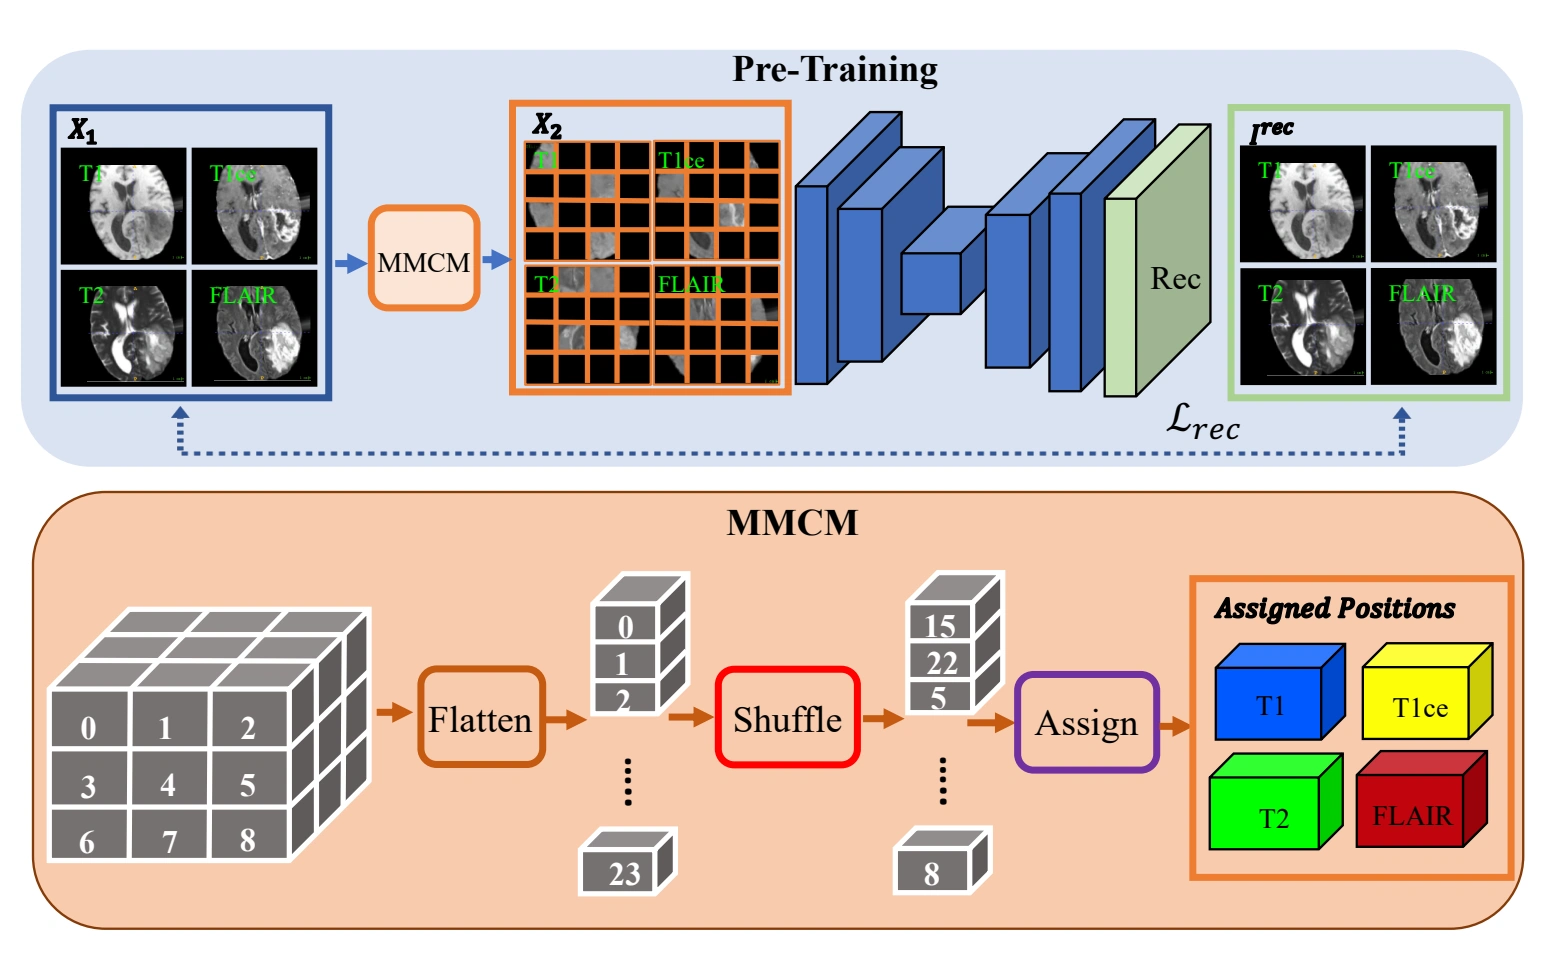
  • MMCM learns cross-sequence MRI representations through complementary masks. A second study, SMNet, combines cross-contrast alignment with arbitrary-scale isotropic reconstruction. Both appeared at IEEE BIBM. SMNet

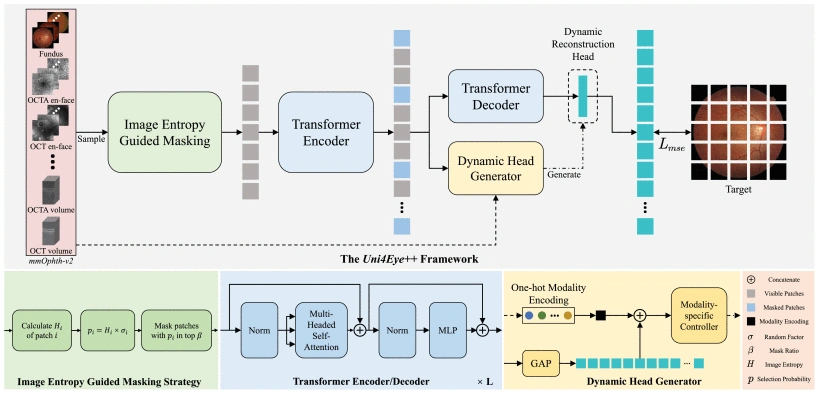
  • Uni4Eye++ extends masked pretraining across 2D ophthalmic images and 3D volumes, with reconstruction heads tailored to each modality. Published online in IEEE TMI. Code

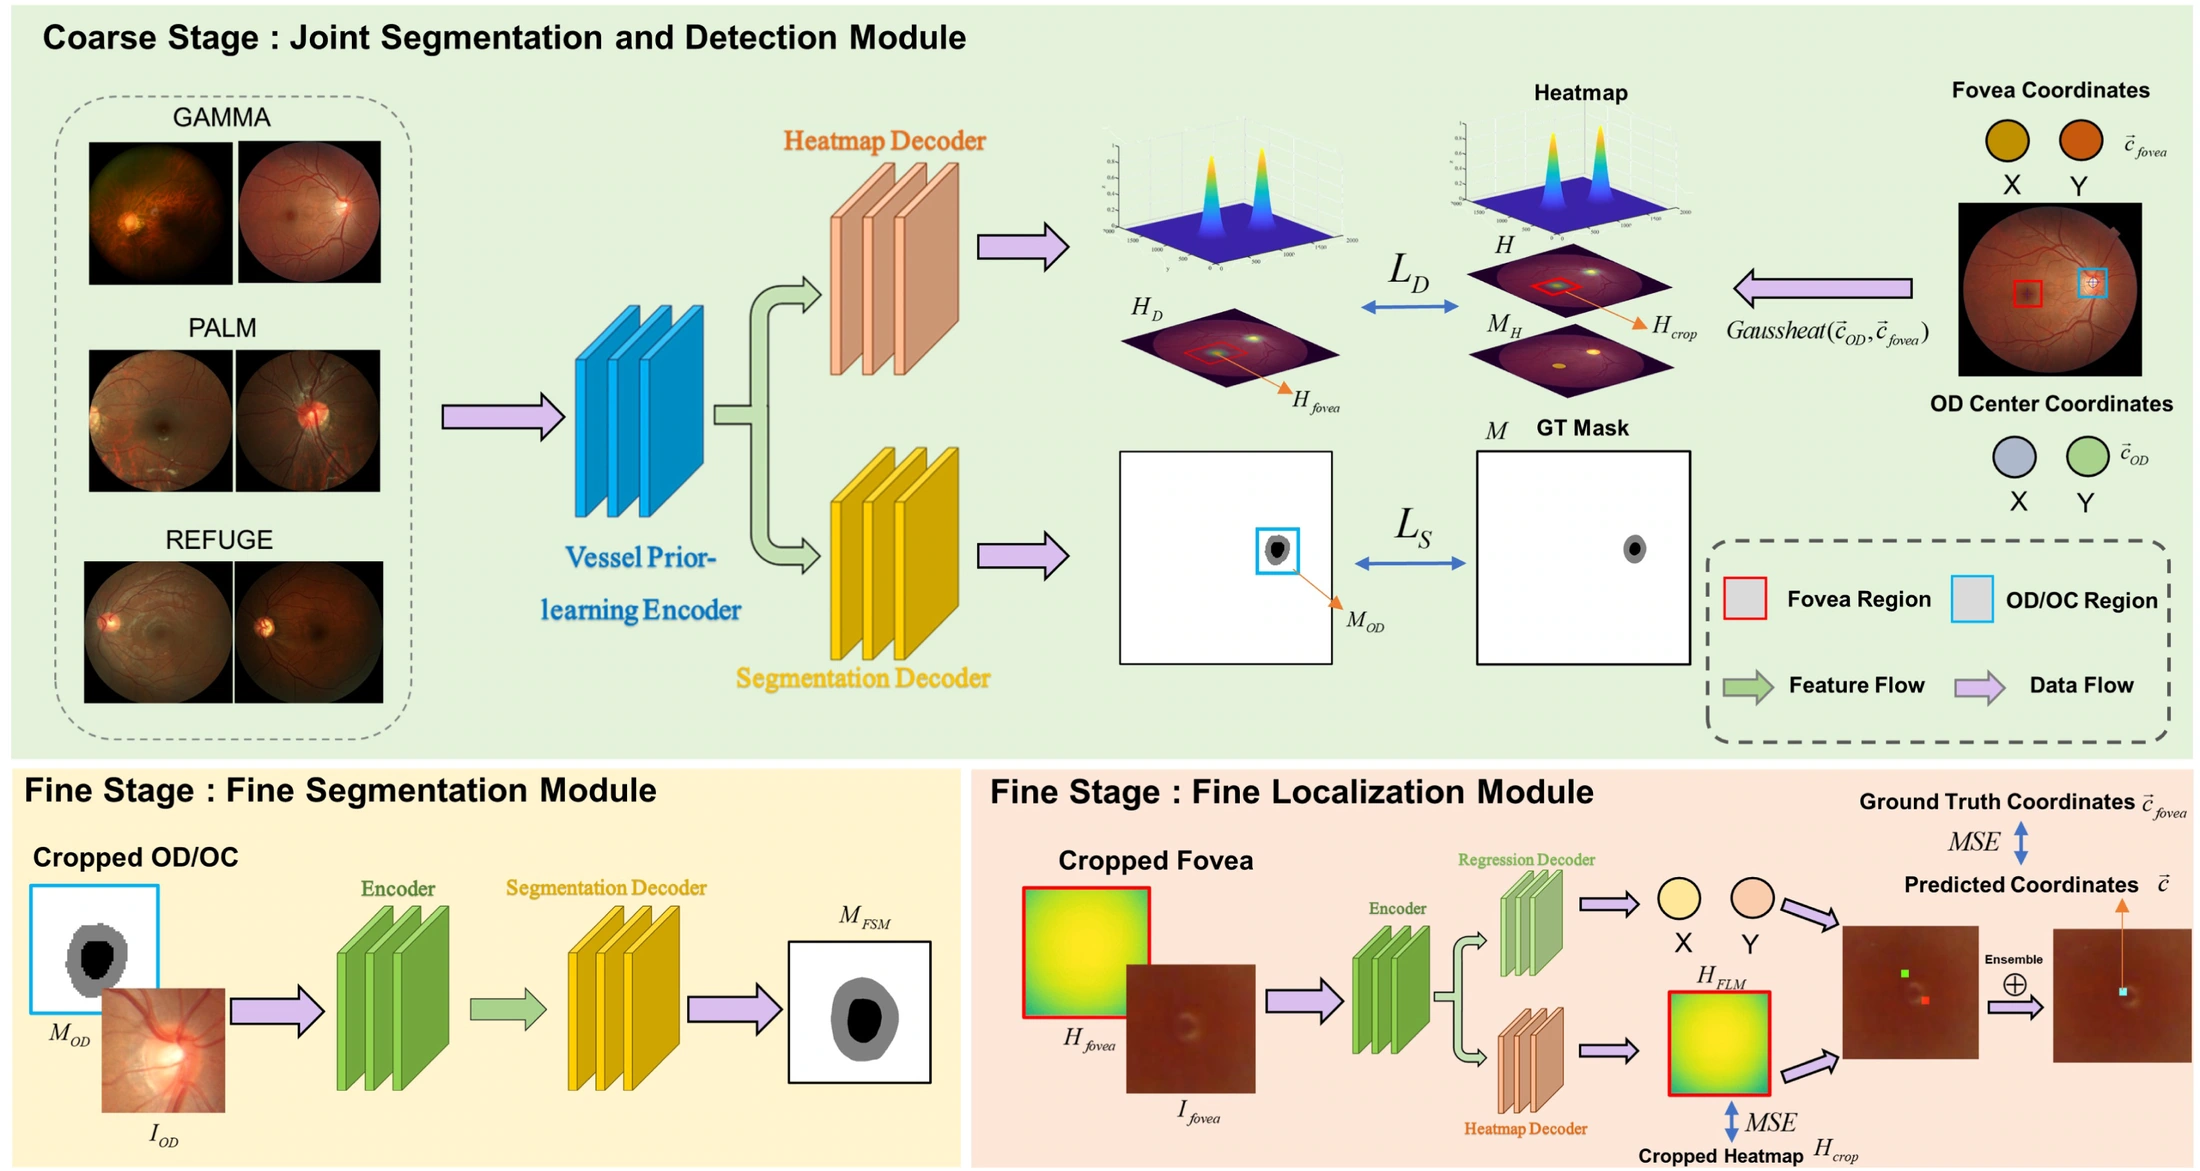
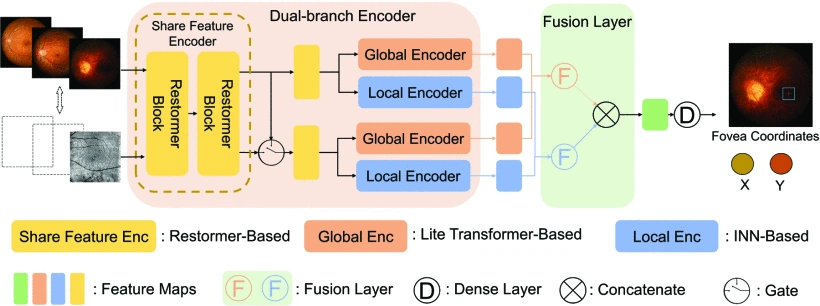
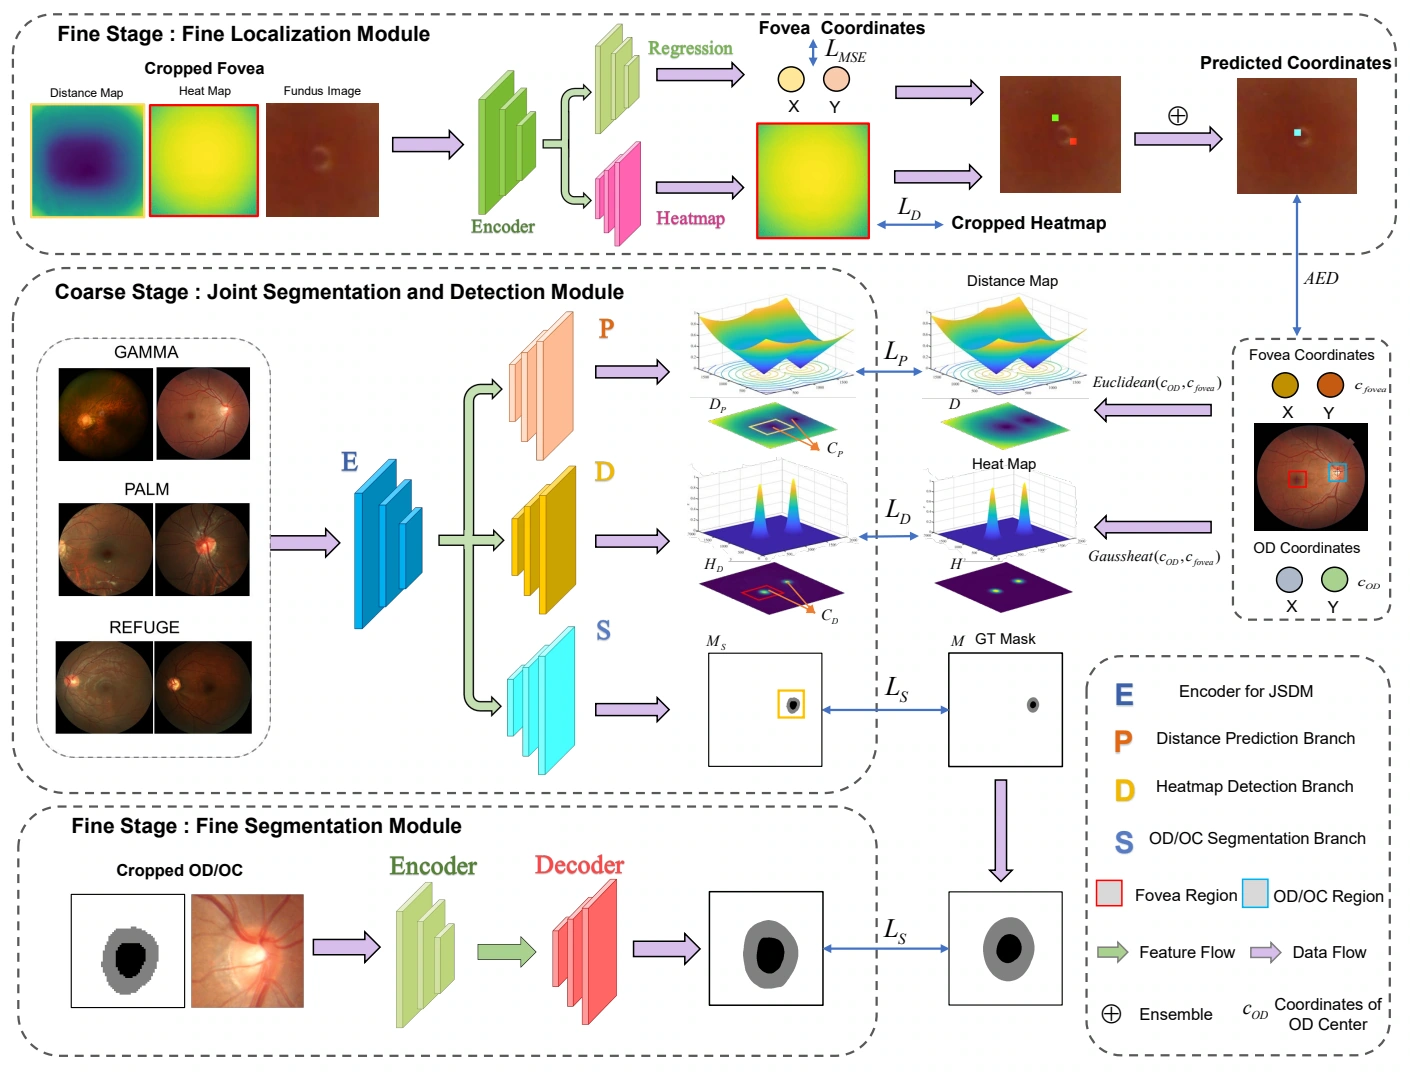
  • JOINEDTrans transfers a vascular spatial prior to joint optic disc and cup segmentation and foveal localization. The coarse-to-fine design was evaluated on three public datasets and published in Computers in Biology and Medicine.

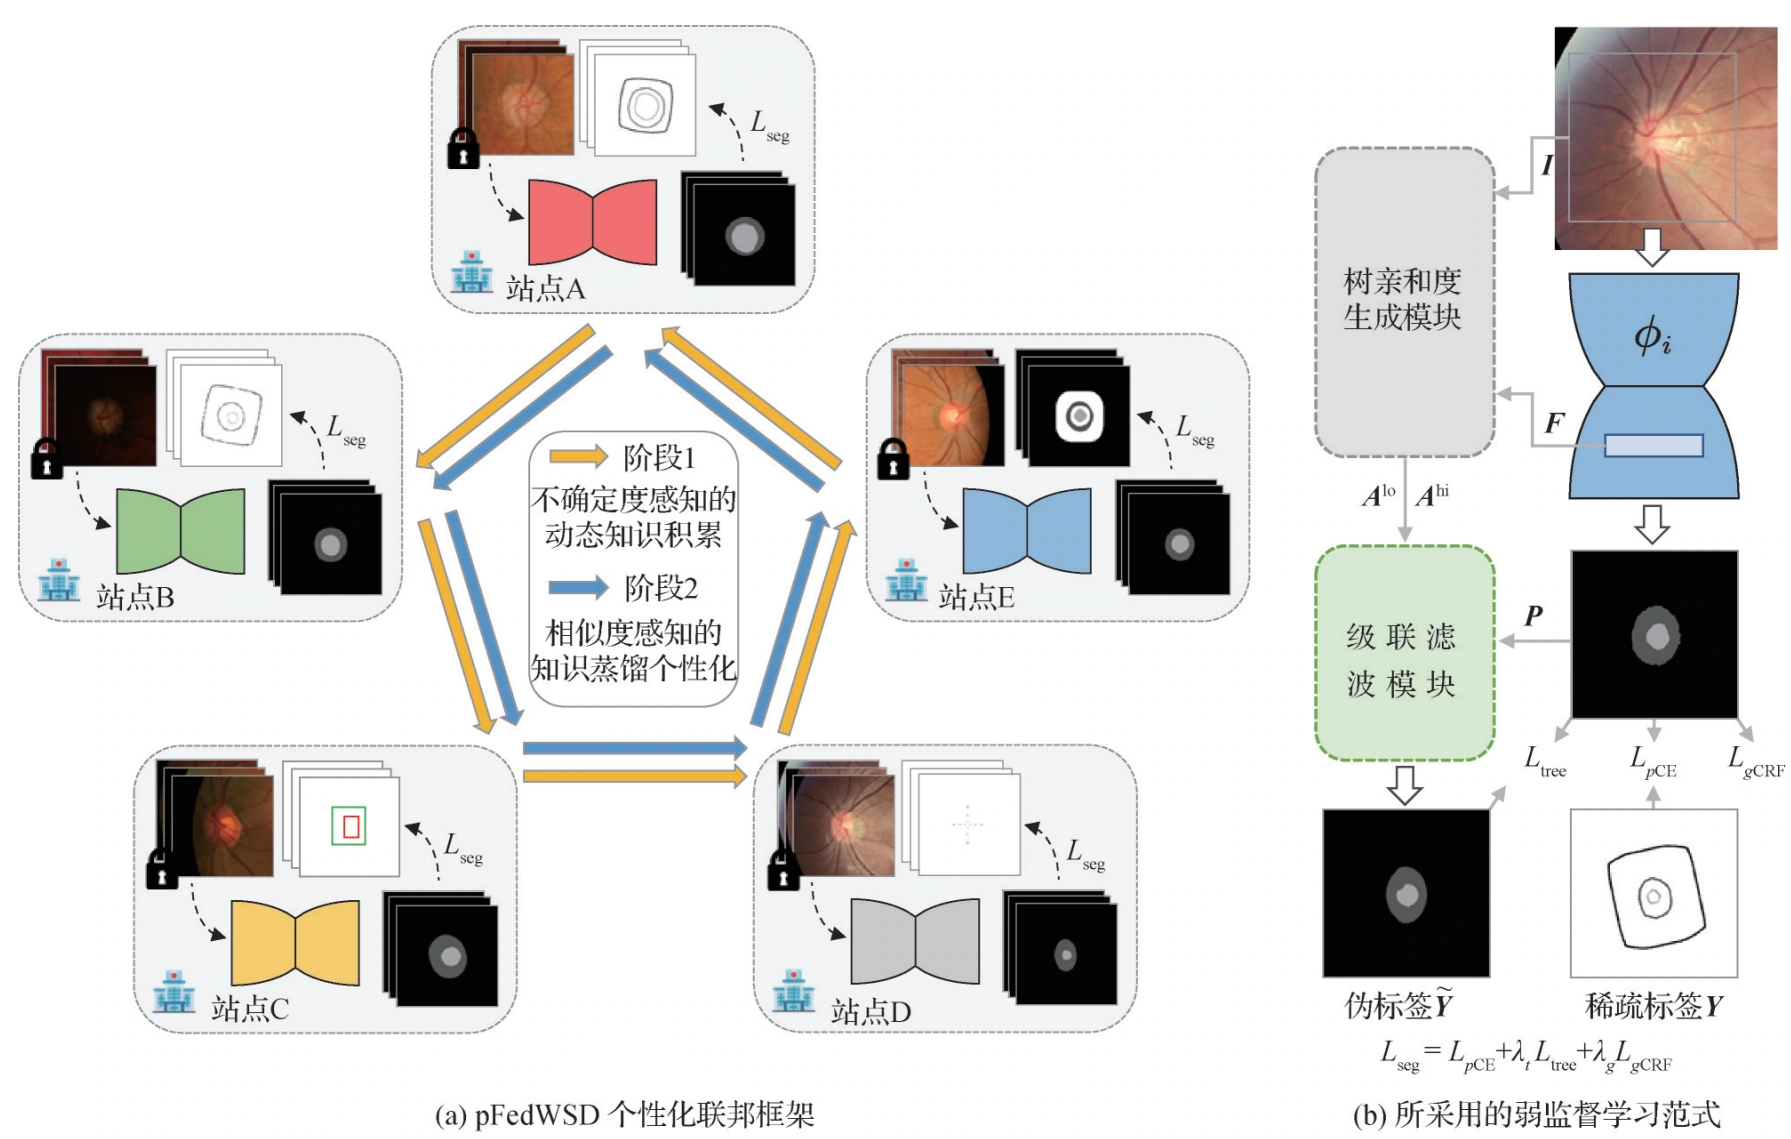
  • pFedWSD distills shared segmentation knowledge into personalized teachers using estimates of site similarity. The framework handles differences in both imaging distributions and sparse labels. Published in Journal of Image and Graphics.

2023

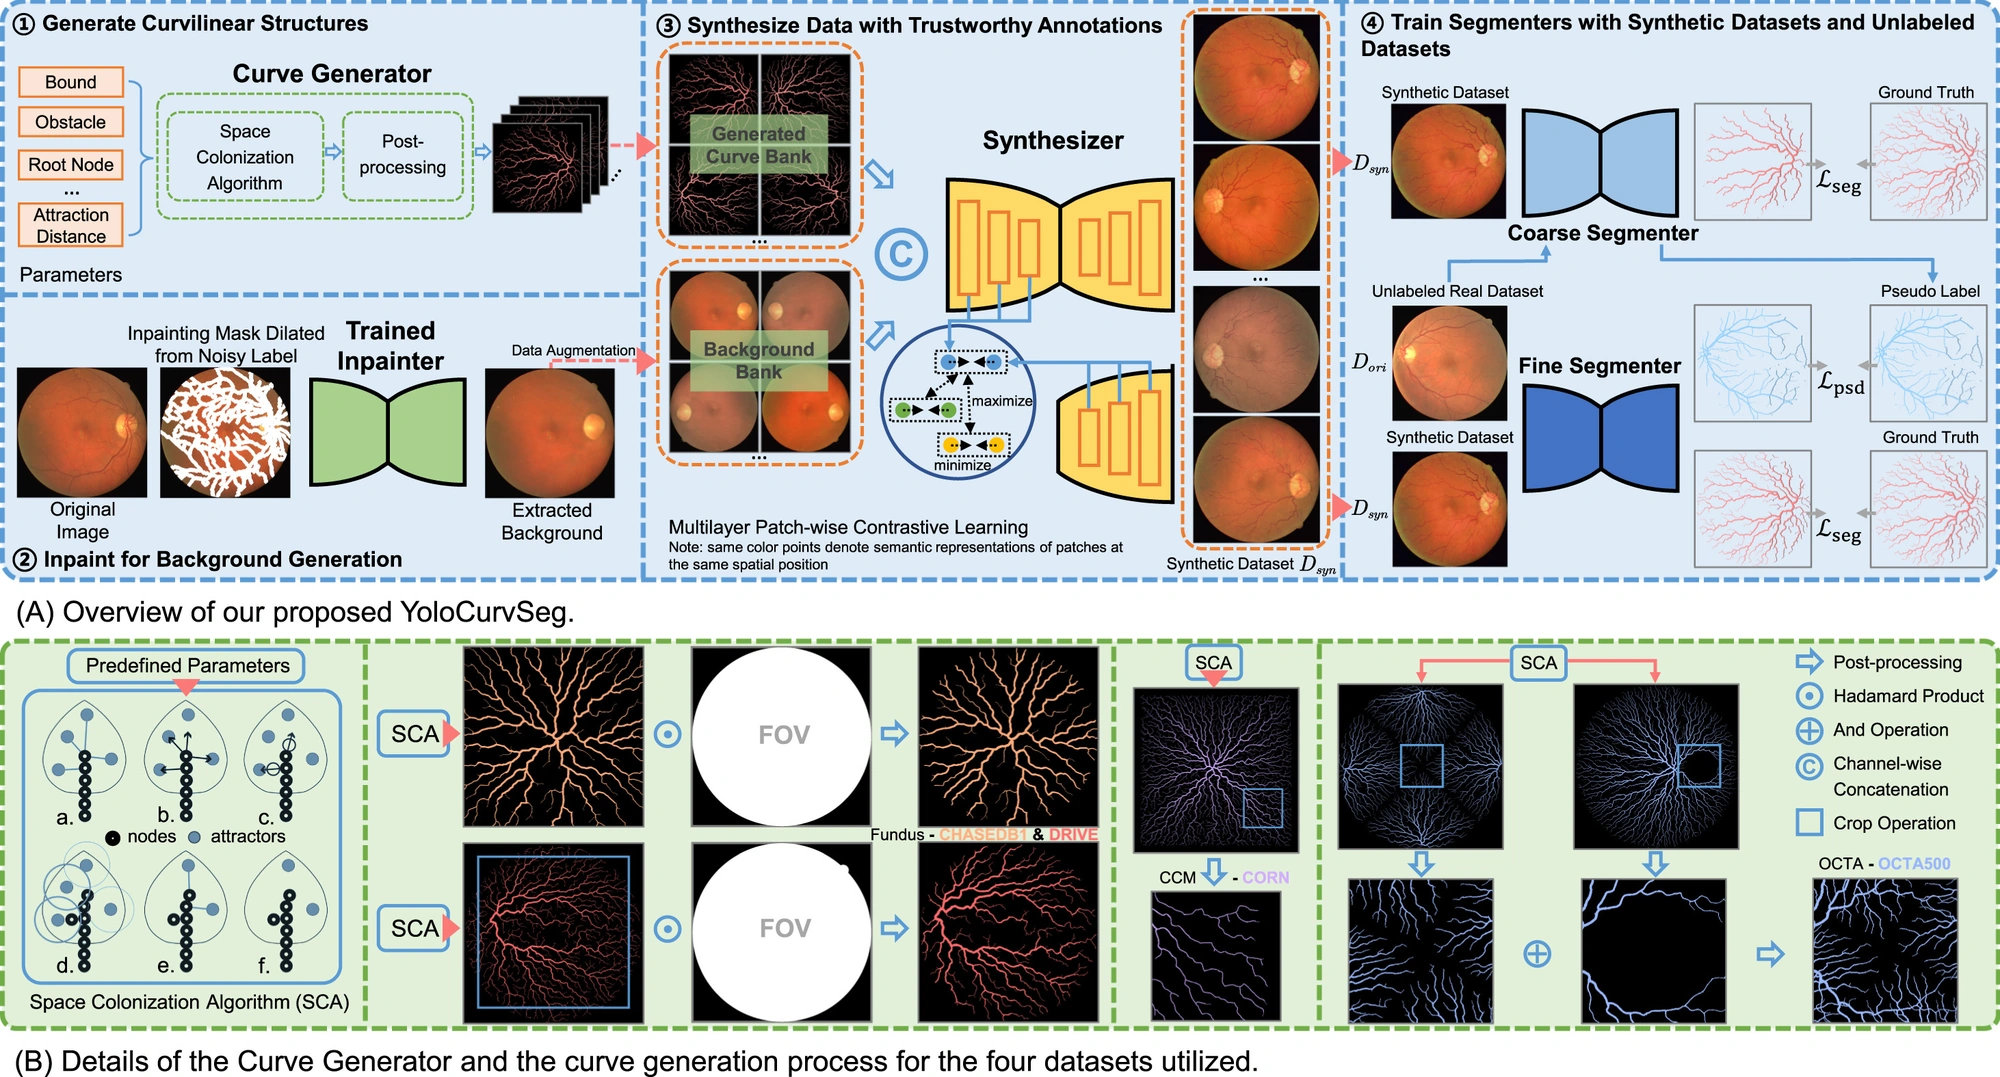
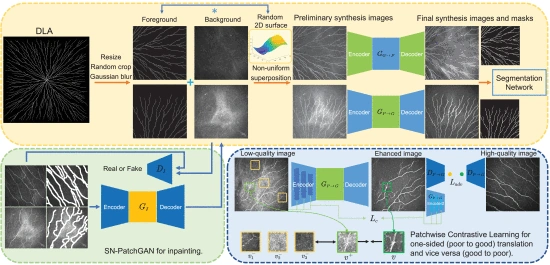
  • YoloCurvSeg constructs dense segmentation supervision from one noisy skeleton by combining synthesized anatomy with backgrounds from unlabeled images. Published in Medical Image Analysis and named a representative algorithm at the China Medical AI Conference. Code and data Recognition

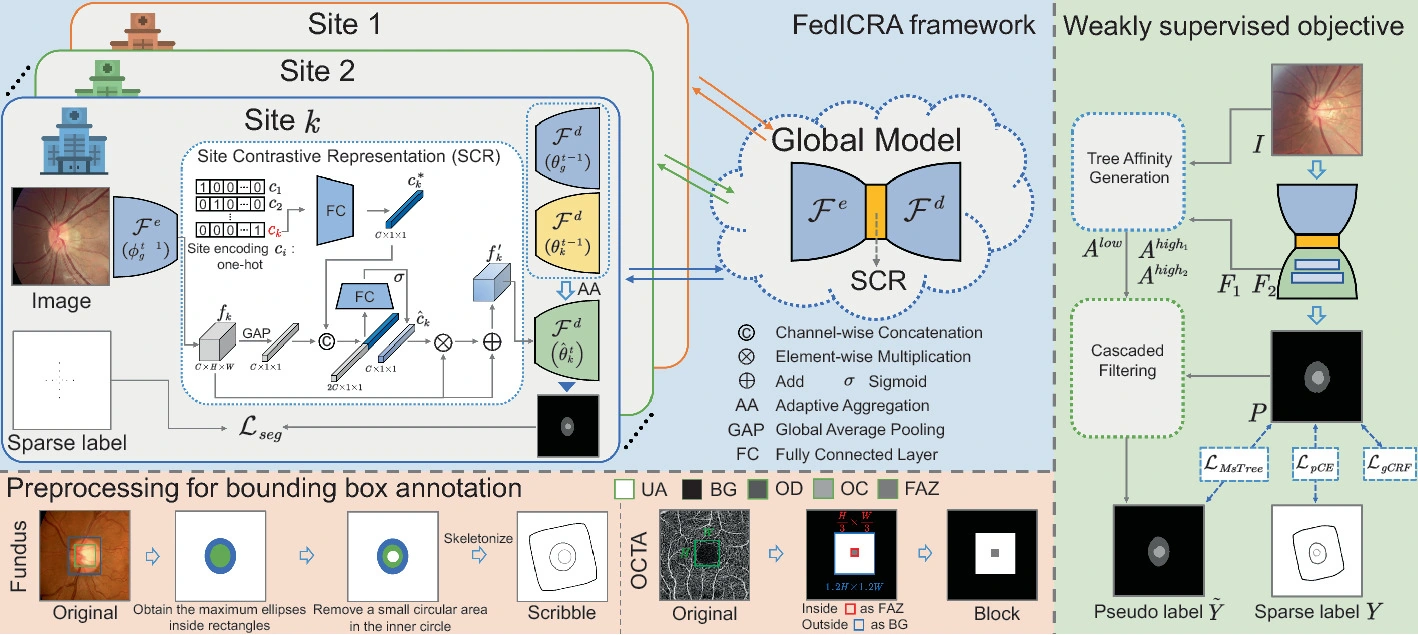
  • FedICRA learns site-aware representations and personalizes parameter aggregation across institutions with different imaging distributions and weak labels. Published in the MLMI workshop proceedings at MICCAI. Code

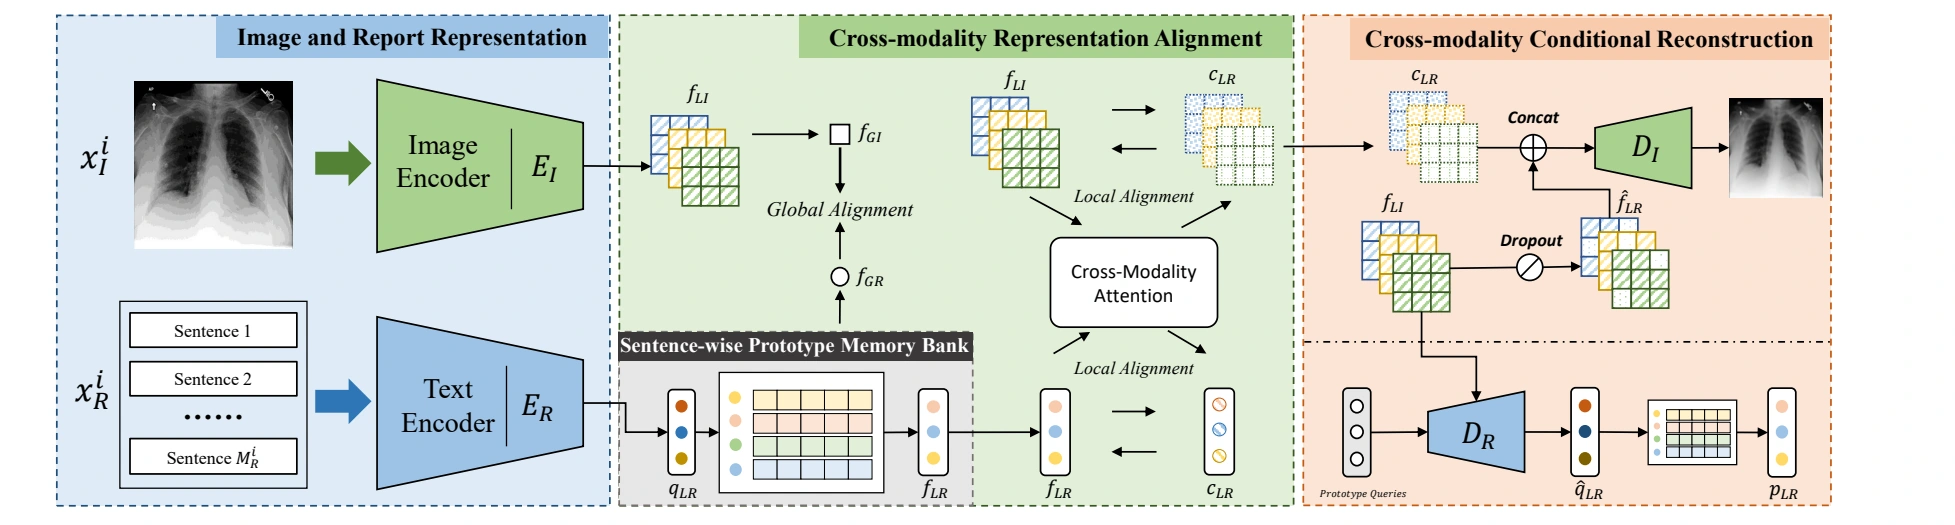
  • PRIOR aligns medical images and reports at global and local scales, using sentence prototypes to preserve clinically relevant language. Transfer was evaluated on five downstream tasks. Published at ICCV. Code

2022

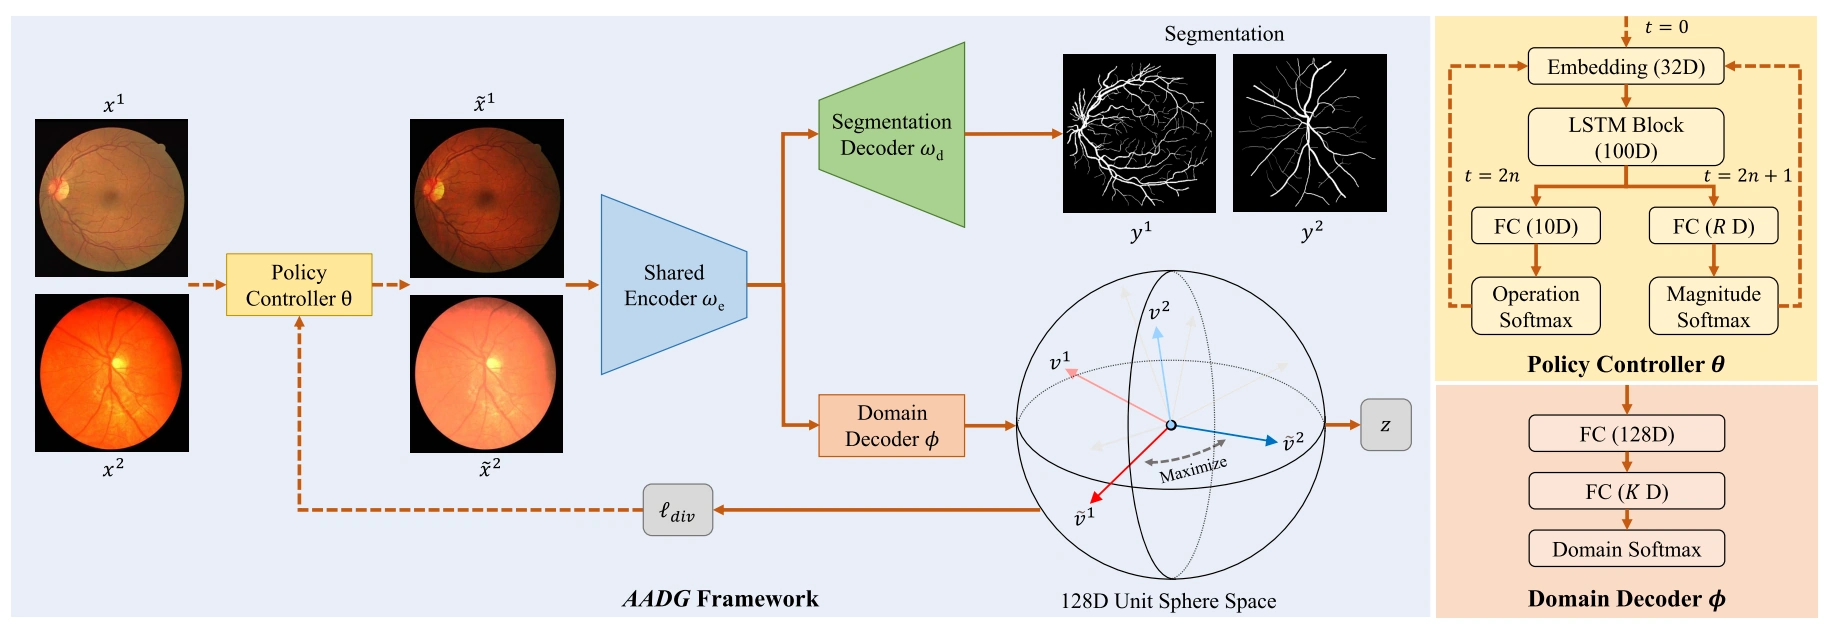
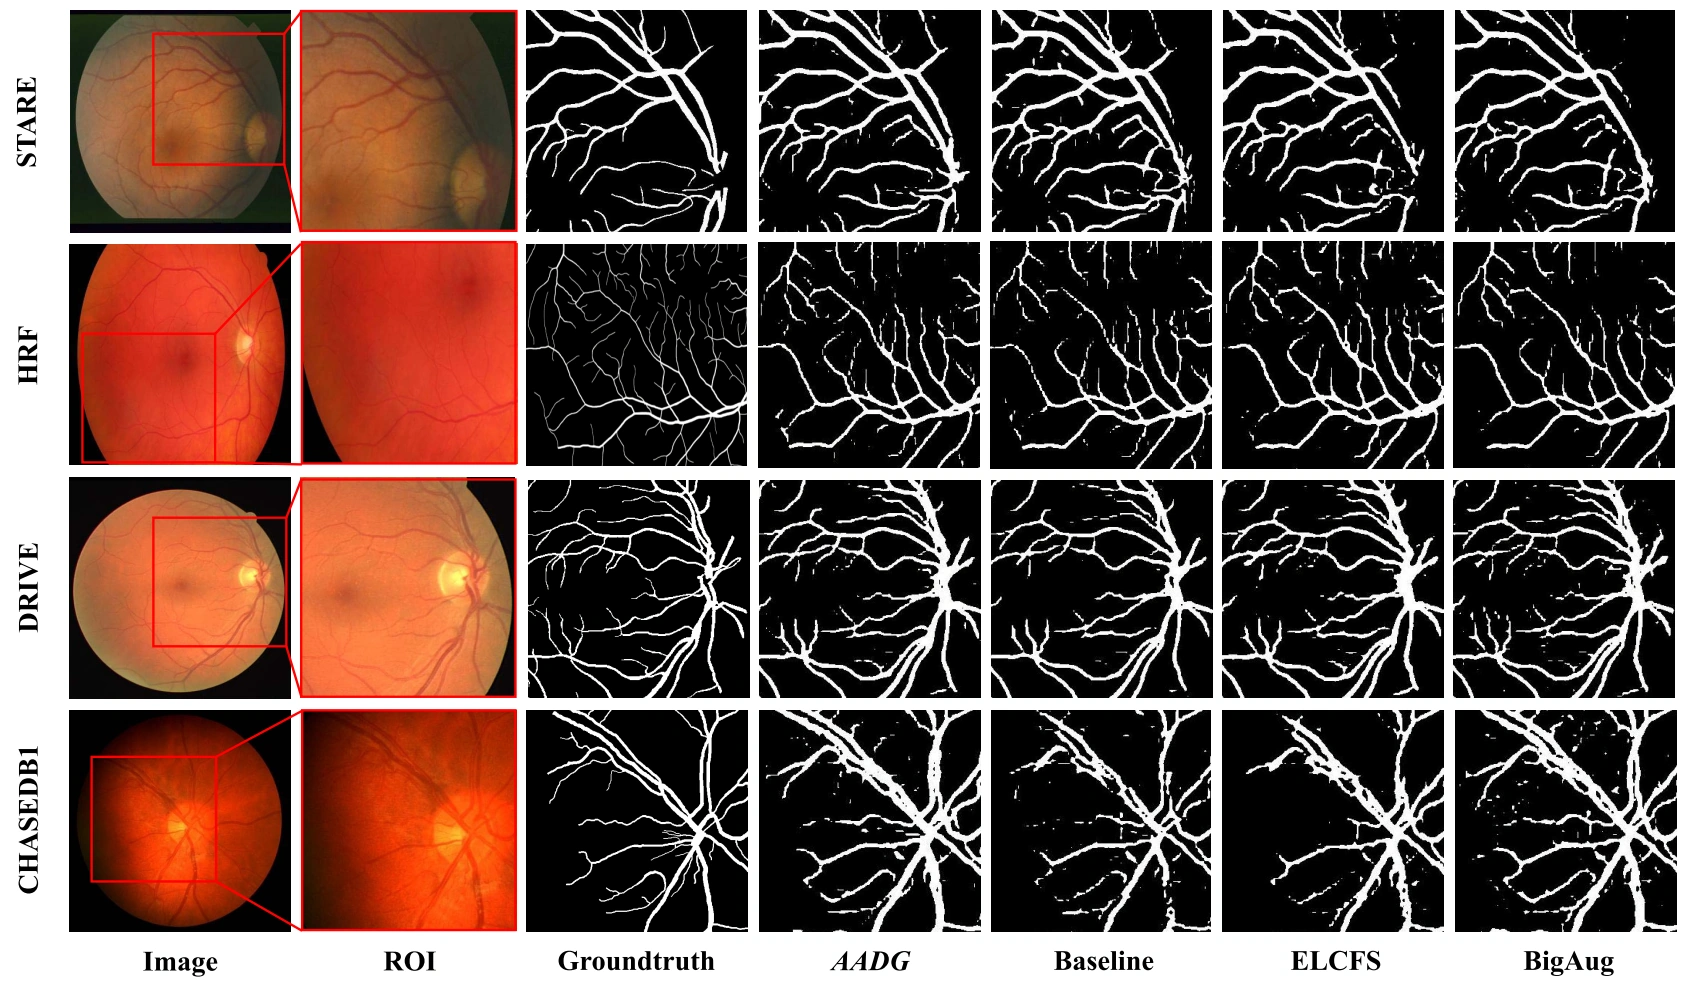
  • AADG searches for augmentation policies that expand the diversity of training domains in feature space. Evaluation tests transfer across unseen retinal datasets and imaging modalities. Published in IEEE TMI. Code

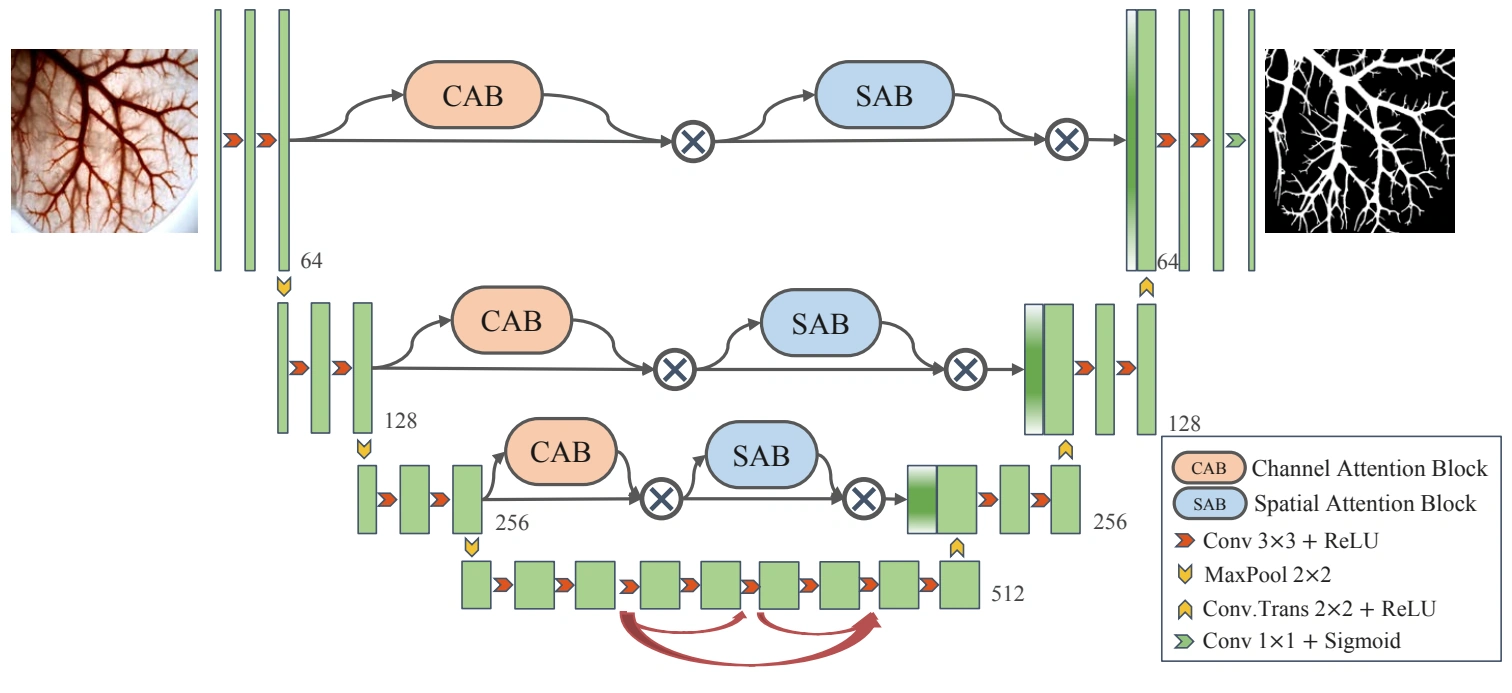
  • JOINED uses pixel-to-landmark distances as auxiliary supervision, jointly locating the fovea and delineating the optic disc and cup. Published in the MIDL proceedings.

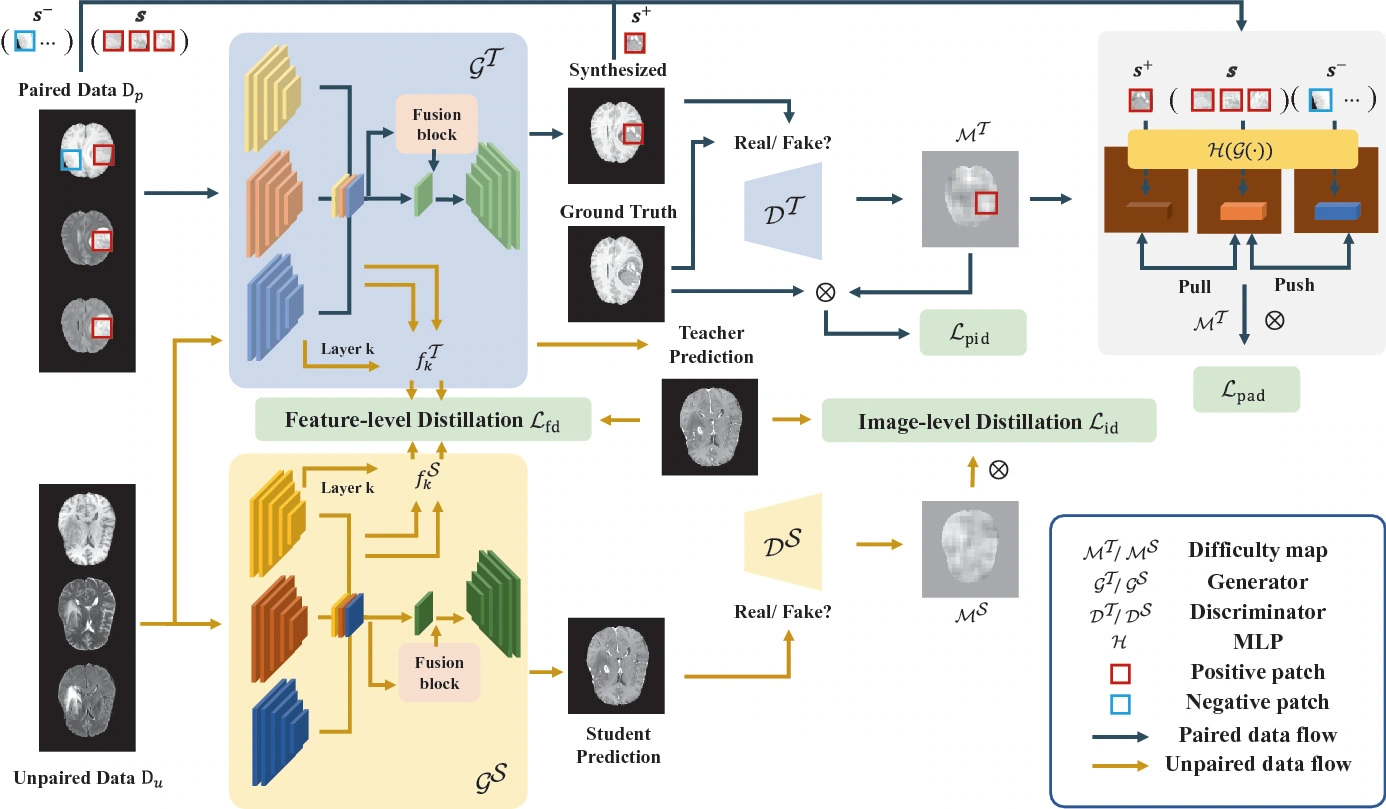
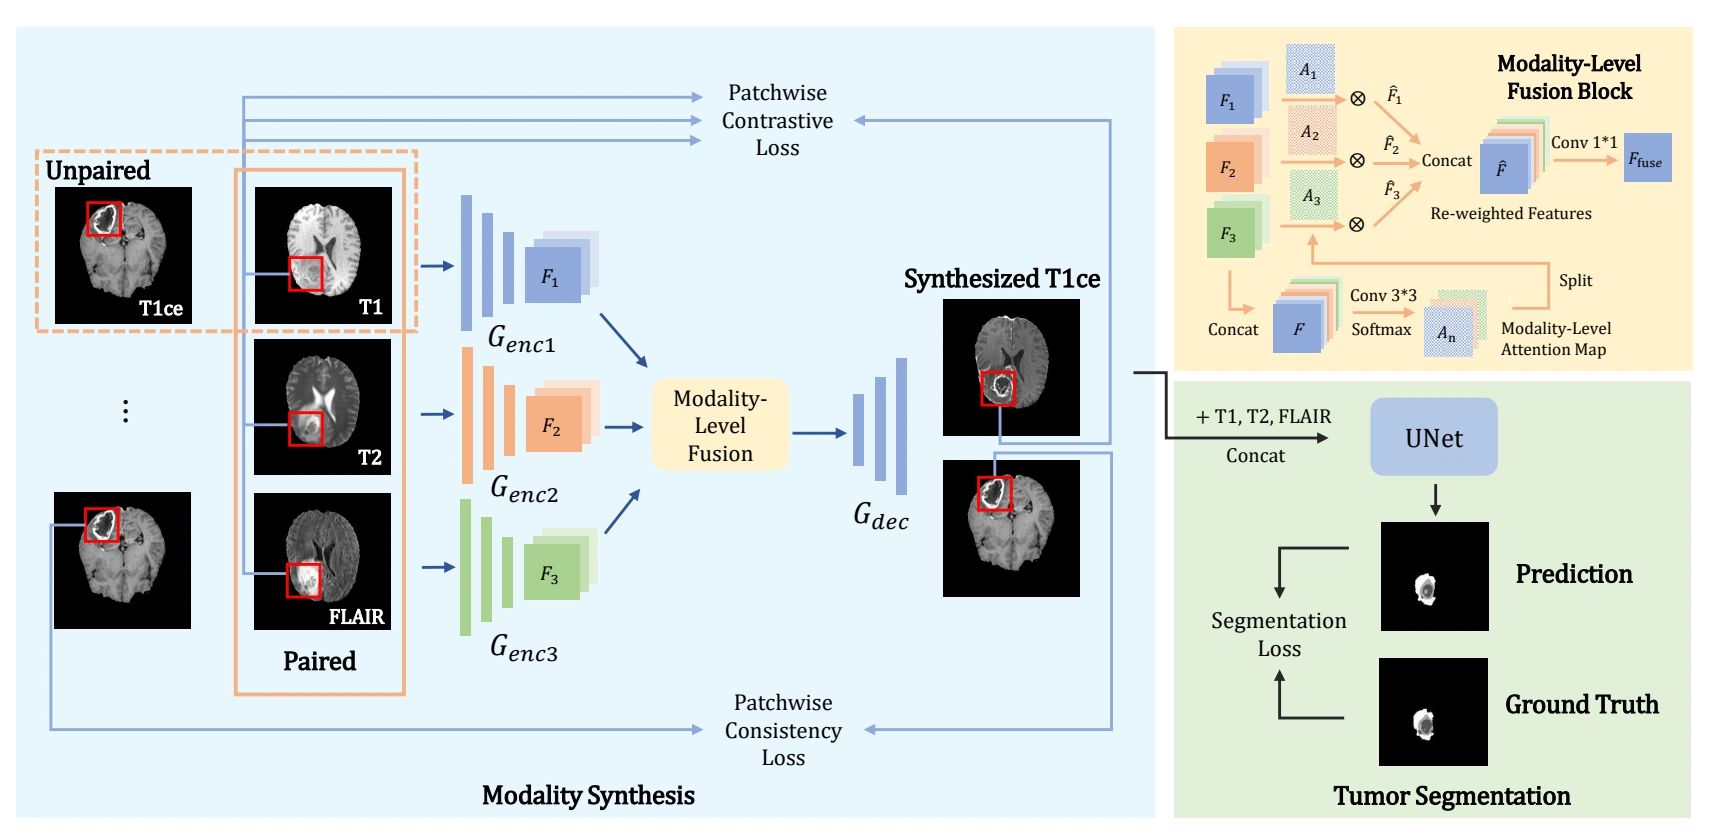
  • DS³-Net learns to synthesize contrast-enhanced T1 MRI from paired and unpaired scans. A difficulty map emphasizes regions that are harder to reconstruct. Published at MICCAI.

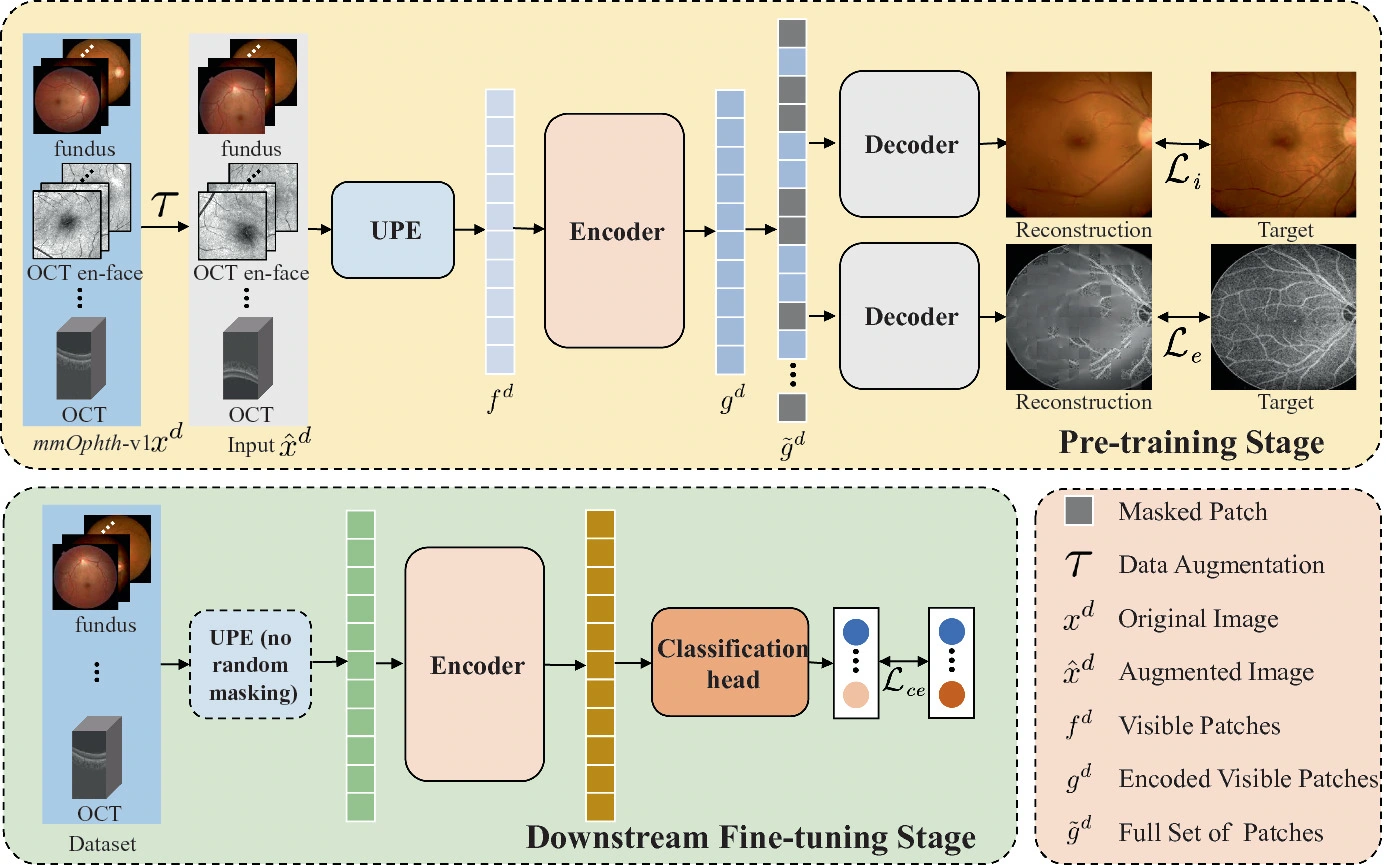
  • Uni4Eye pretrains a shared Transformer on 2D ophthalmic images and 3D volumes by reconstructing masked intensities and gradients. Transfer was evaluated on six classification tasks. Published at MICCAI.

2021

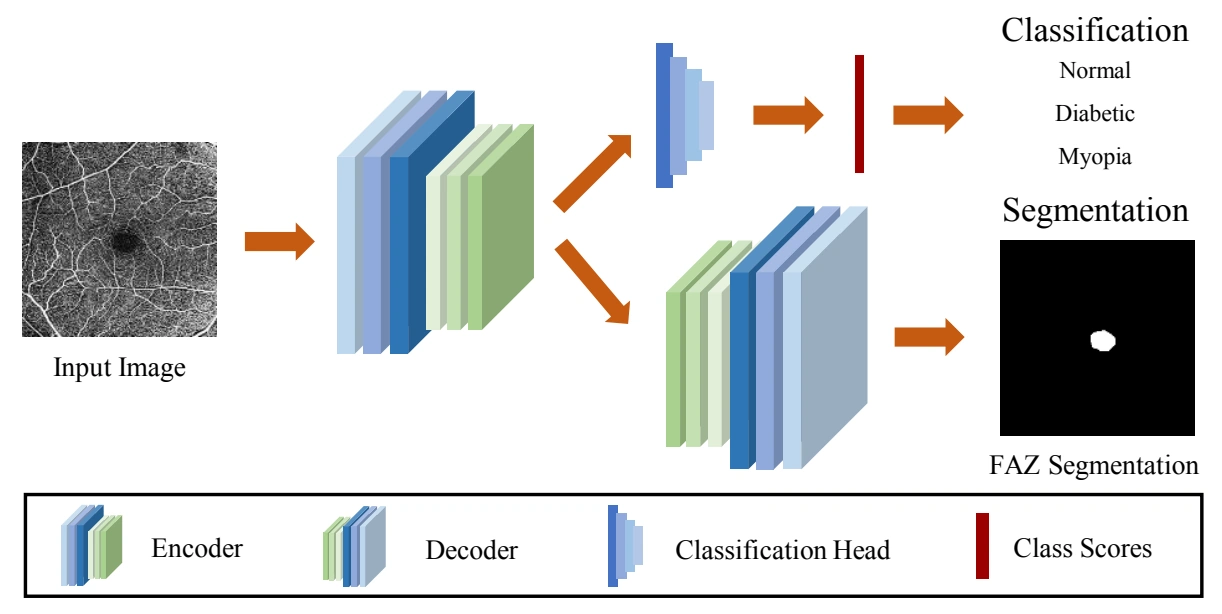
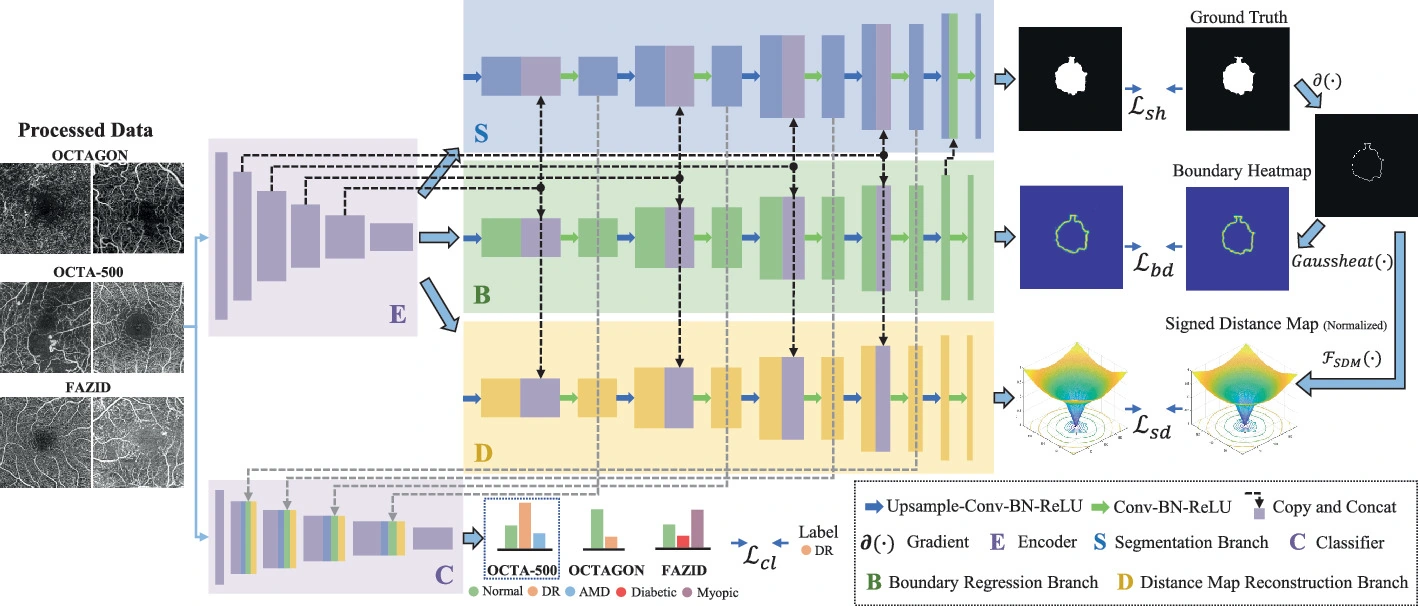
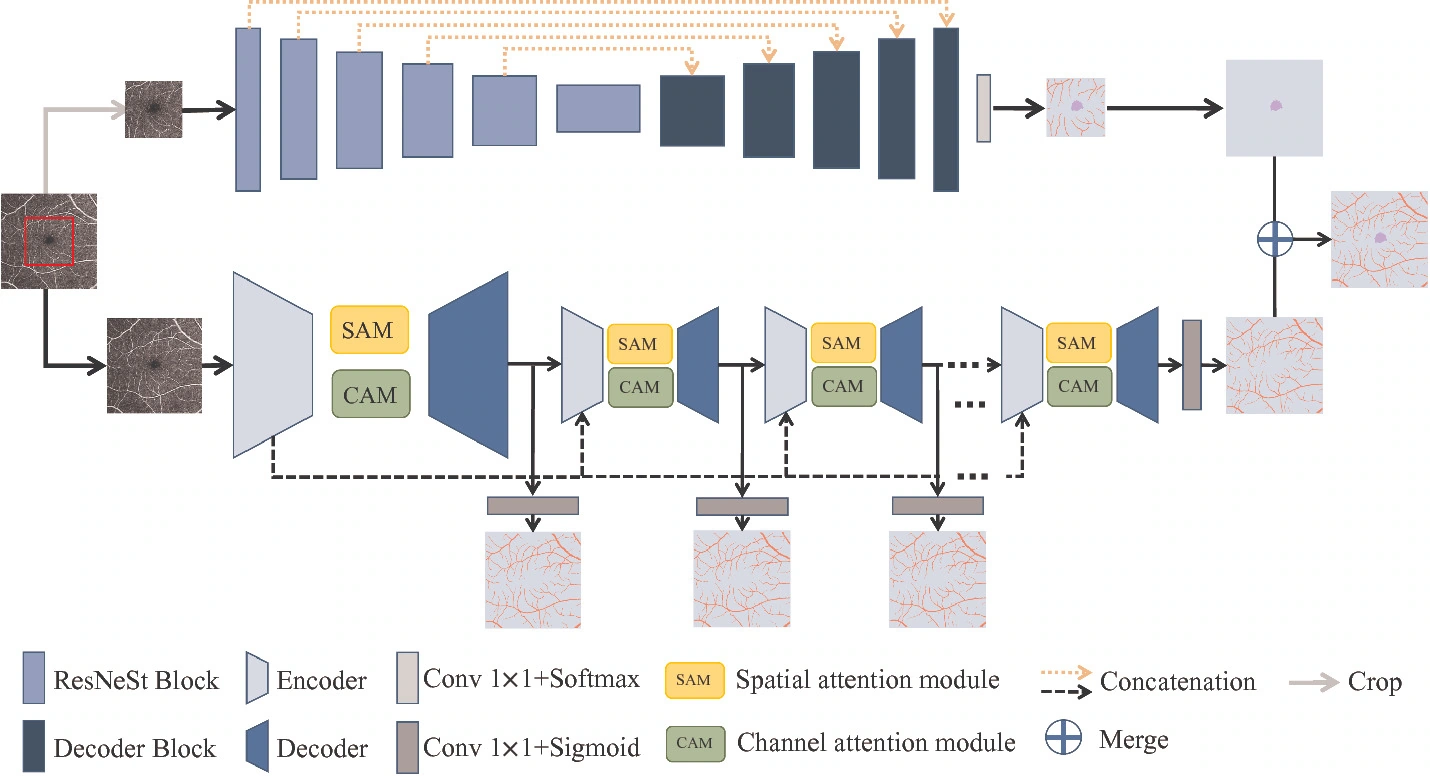
  • BSDA-Net uses boundary heatmaps and signed distance maps to represent the foveal avascular zone, sharing its geometry between delineation and classification. Published at MICCAI. Code

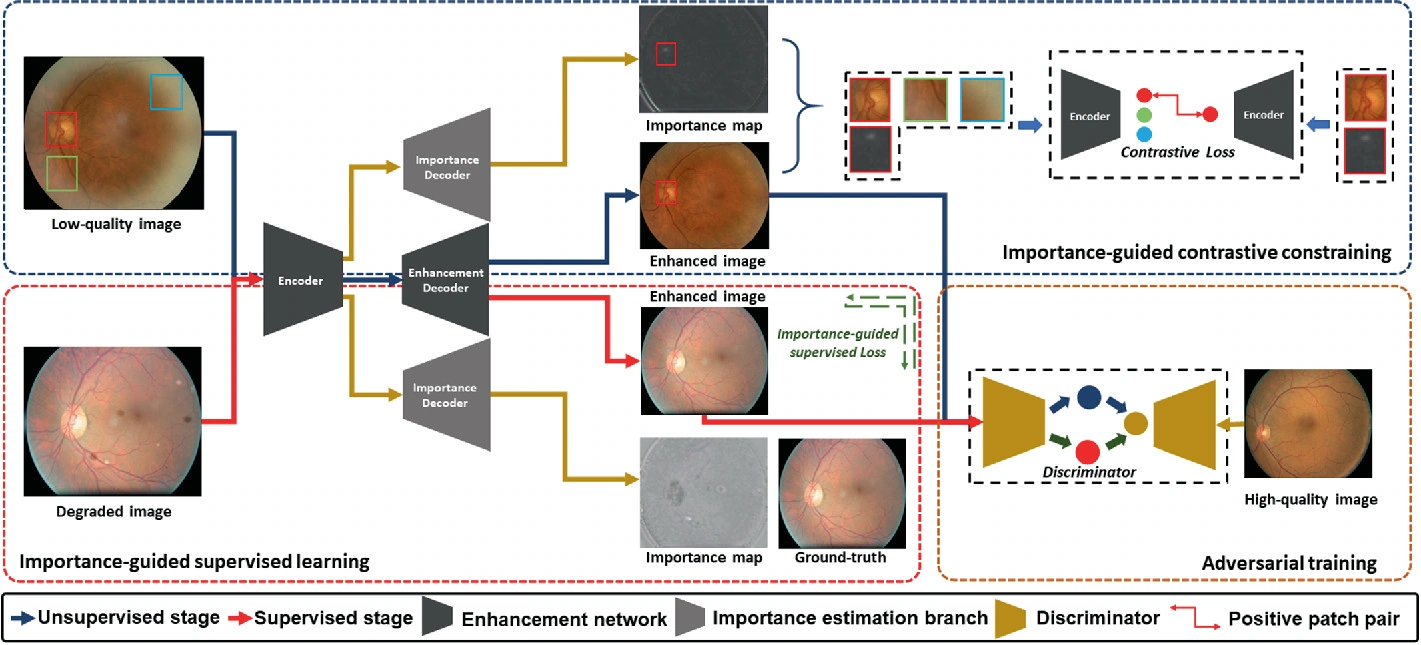
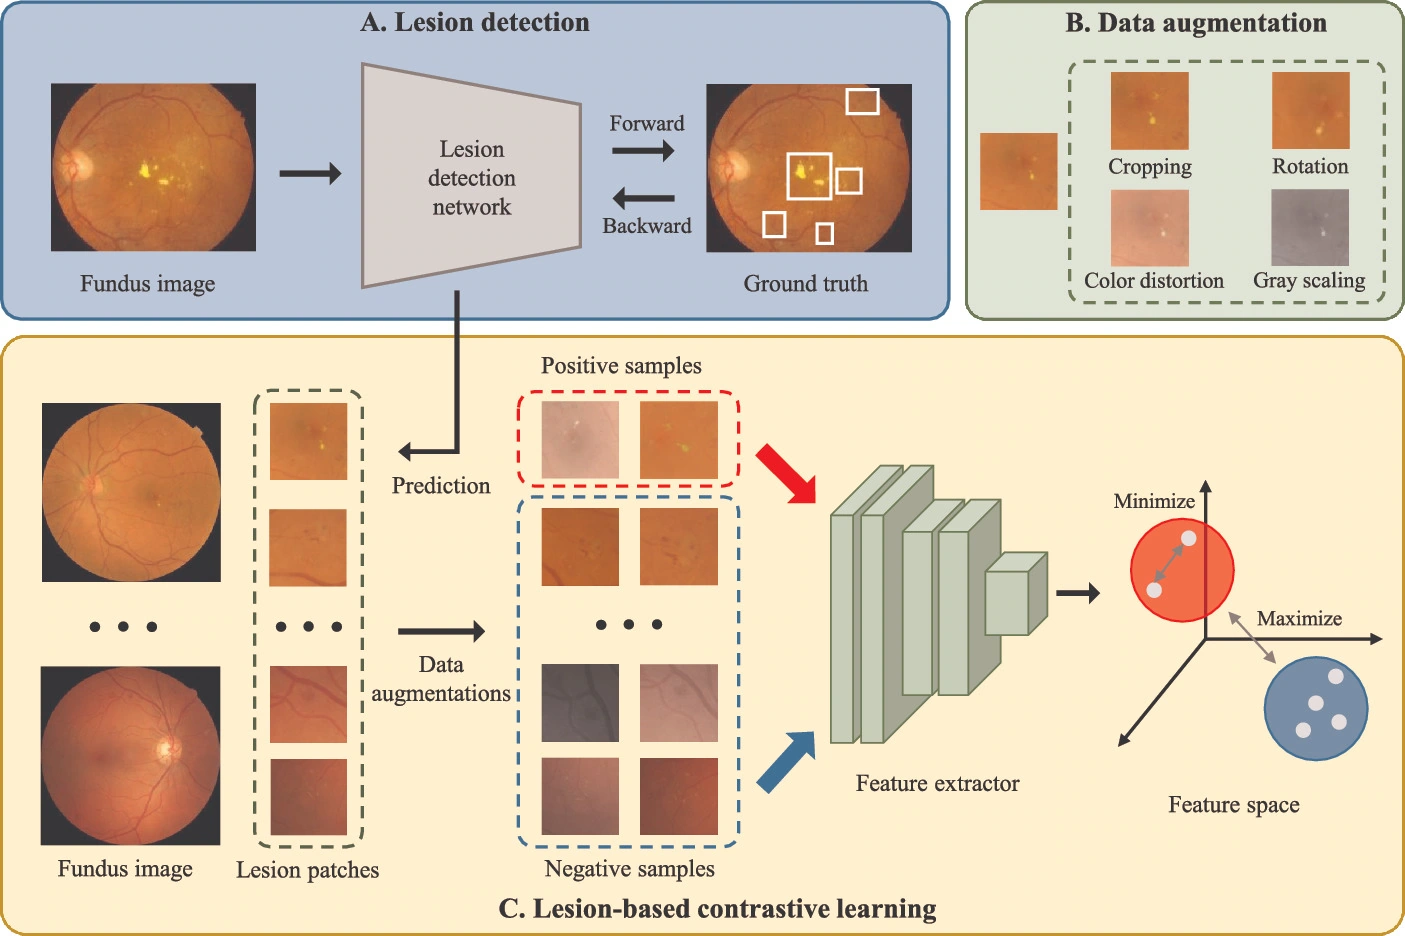
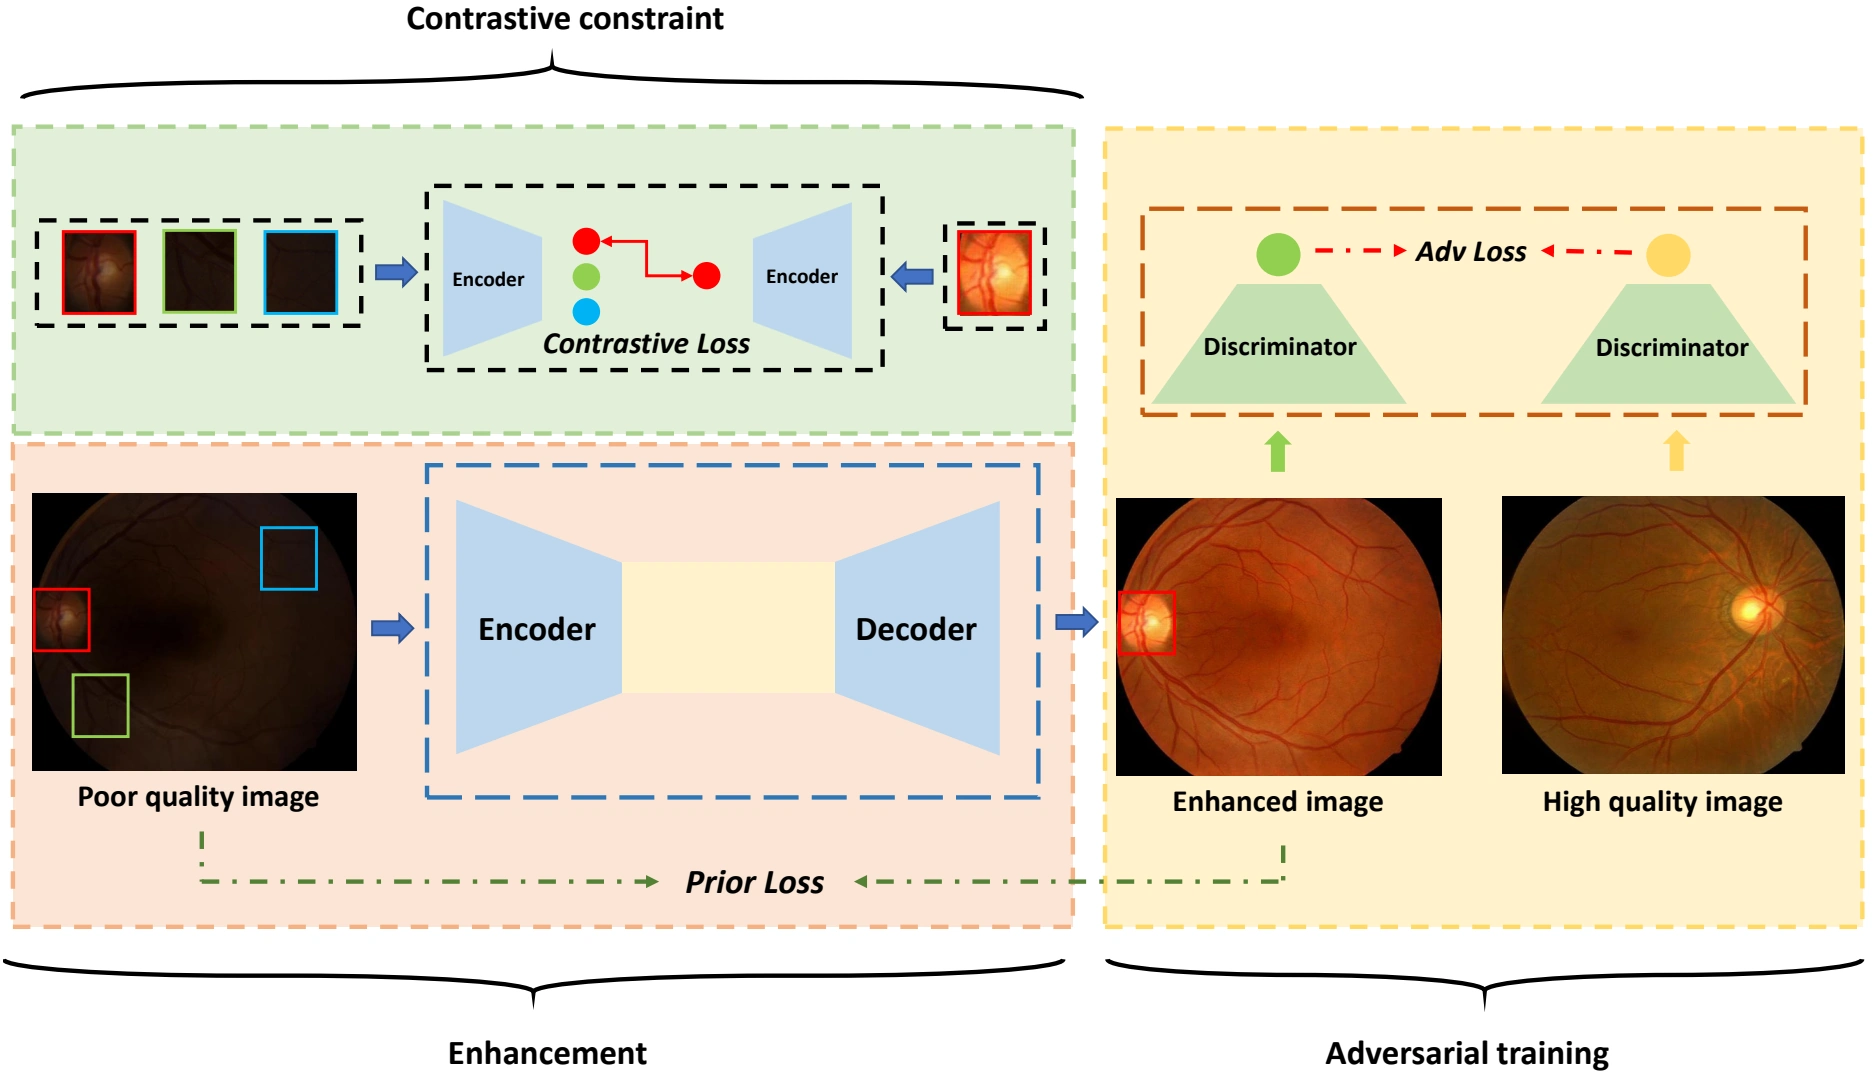
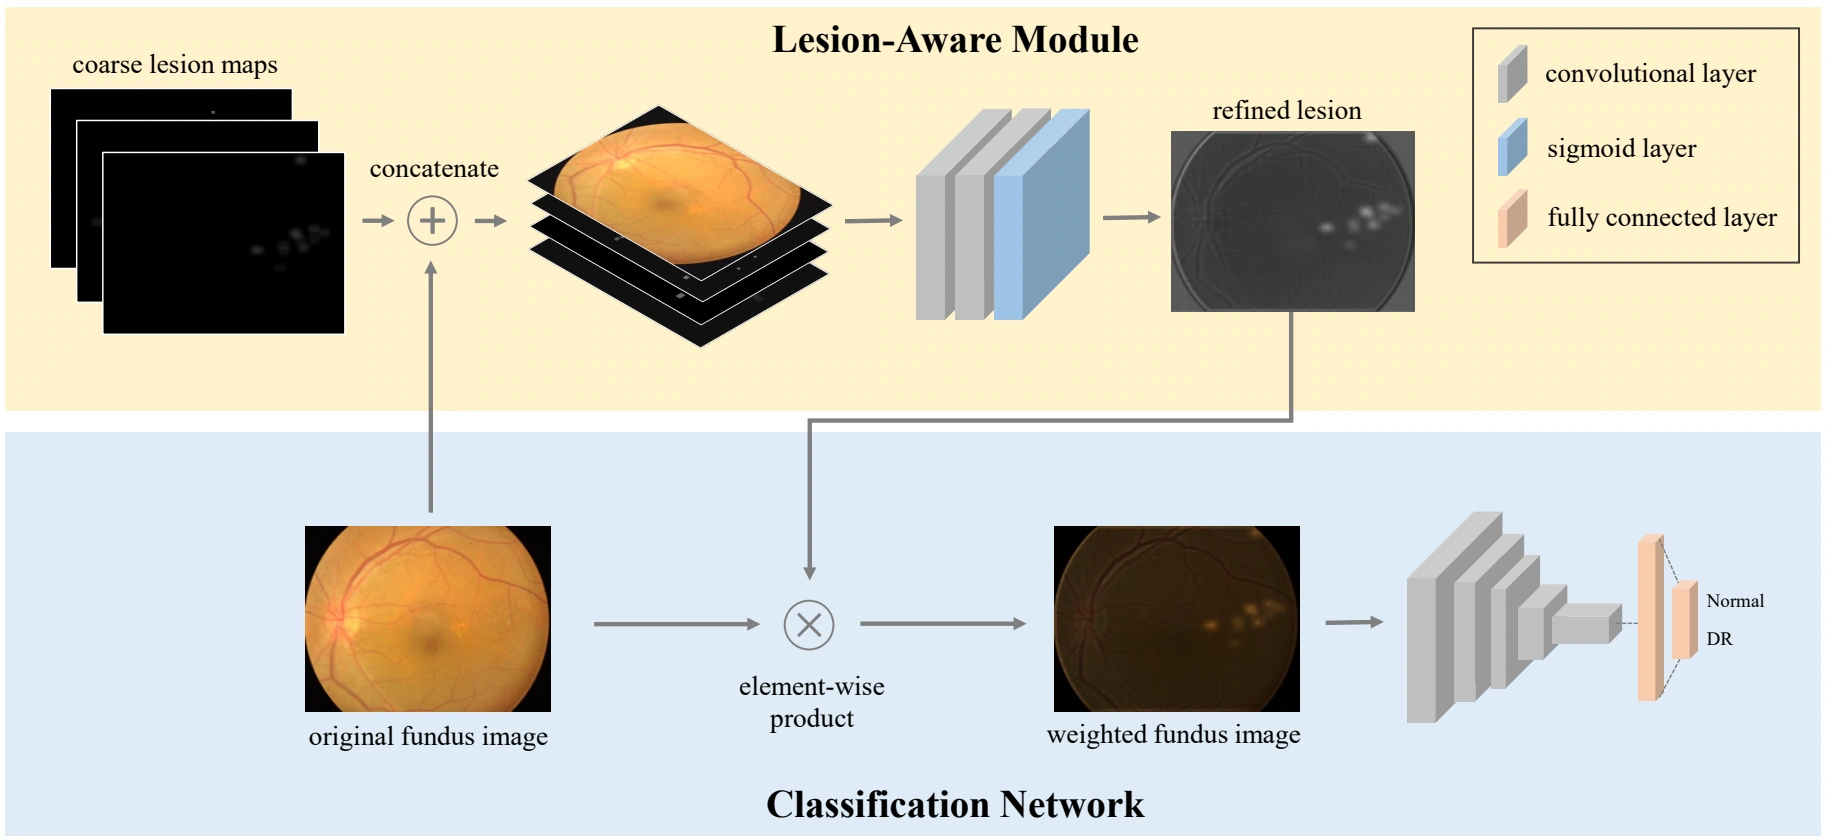
  • I-SECRET learns fundus image enhancement from synthetic degradations and unpaired clinical images. Another paper studies lesion-centered contrastive learning for retinopathy grading. Both appeared at MICCAI. Lesion-aware learning paper

  • Corneal nerve segmentation combines contrastive image synthesis with quality enhancement to address uneven illumination and imperfect labels in confocal microscopy. Published at IEEE ISBI.

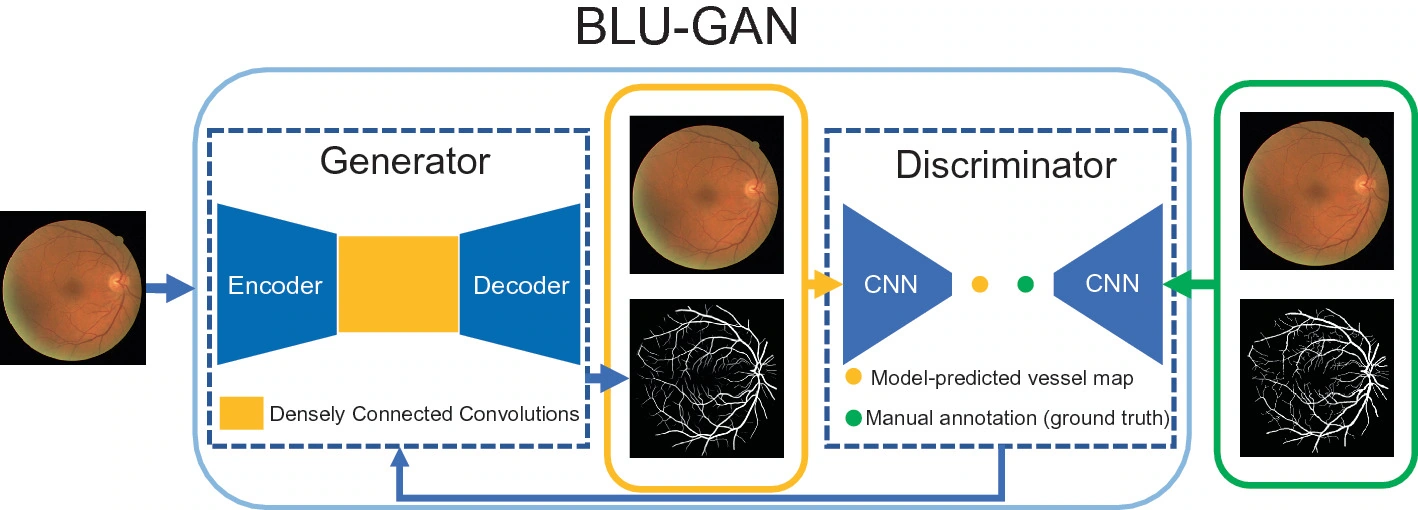
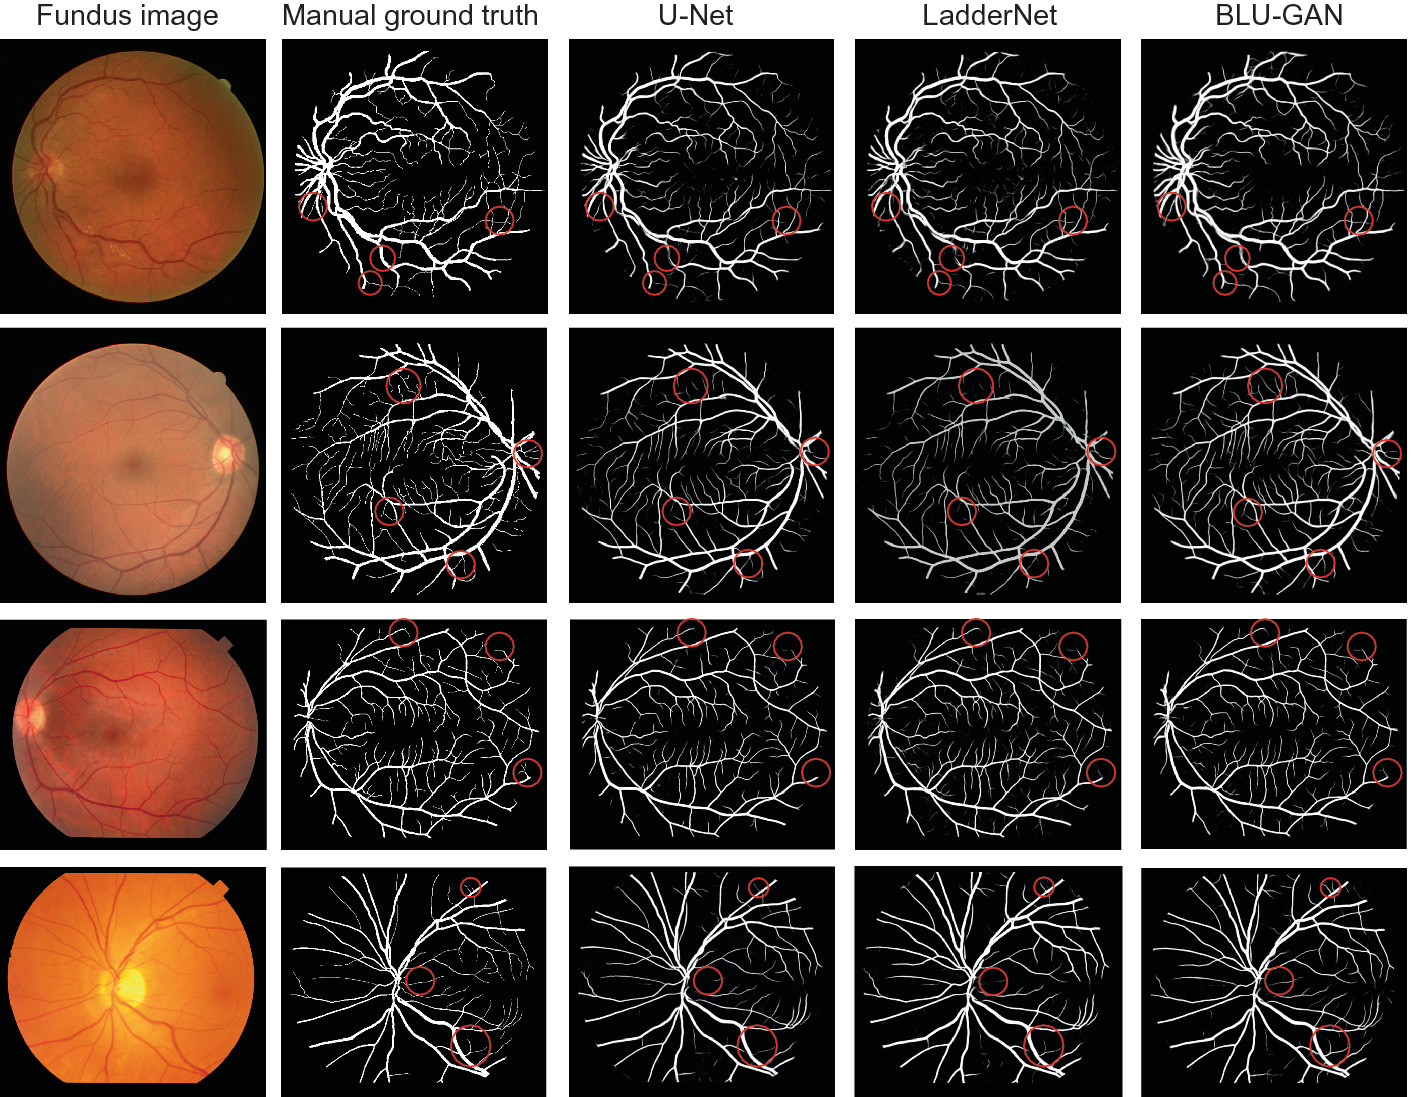
  • BLU-GAN uses bidirectional ConvLSTM units to combine features across scales for retinal vessel segmentation. The paper received the Best Paper Award at BenchCouncil FICC 2020 and appeared in the 2021 proceedings.

2020

  • SUSTech–SYSU released 1,219 fundus photographs with lesion and anatomical landmark annotations and diabetic retinopathy grades from three protocols. Published in Scientific Data. Download dataset

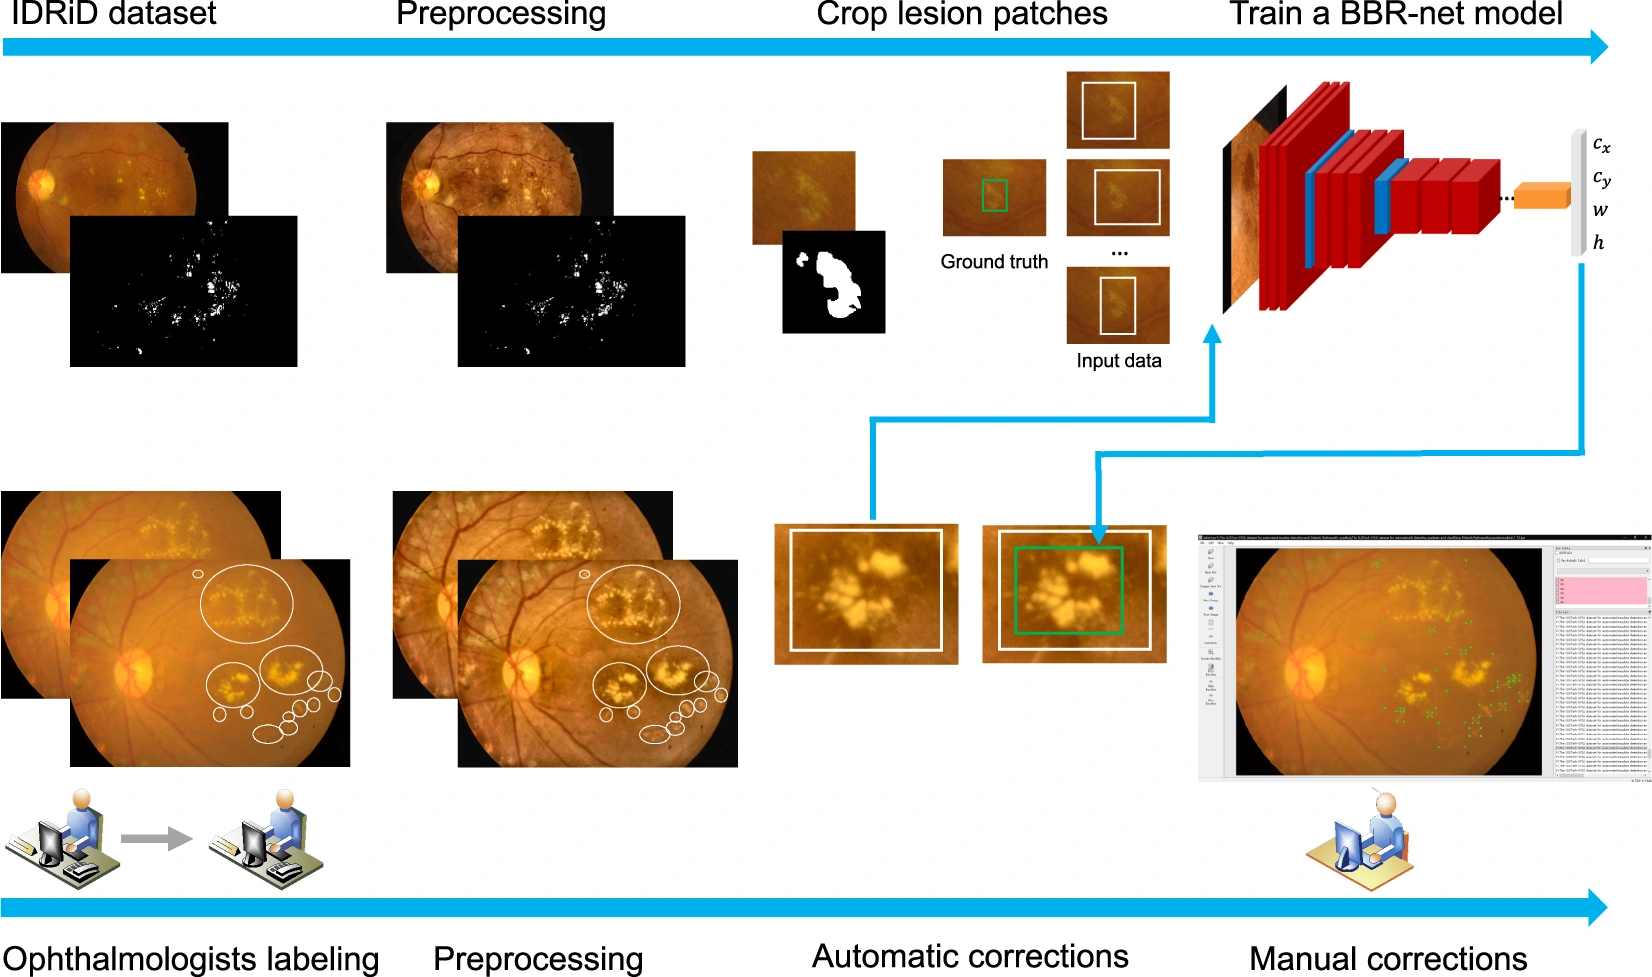
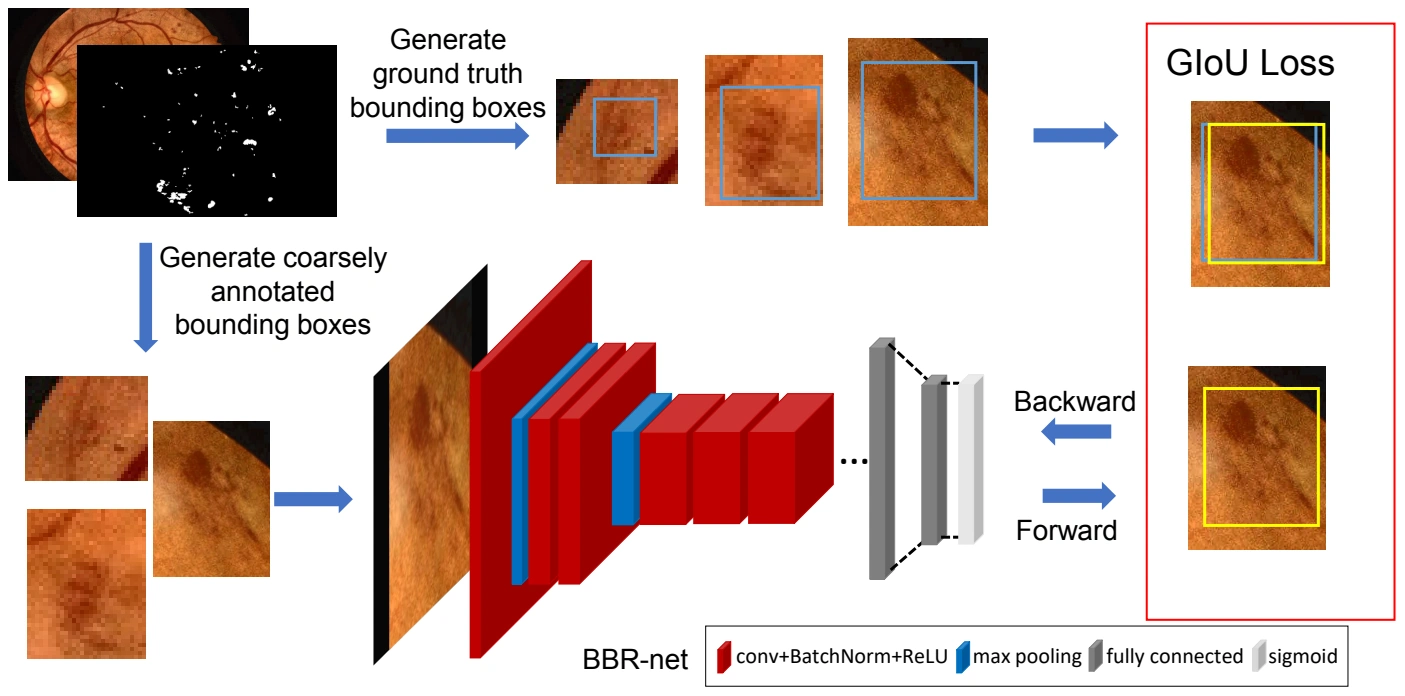
  • Retinal hemorrhage detection refines coarse bounding-box annotations before training a label-smoothed detector for retinal hemorrhages. Published at IEEE ISBI.

Experience

Academic CV →

Publications

Search publications

2026

Fig. 3 · Source · IEEE copyright

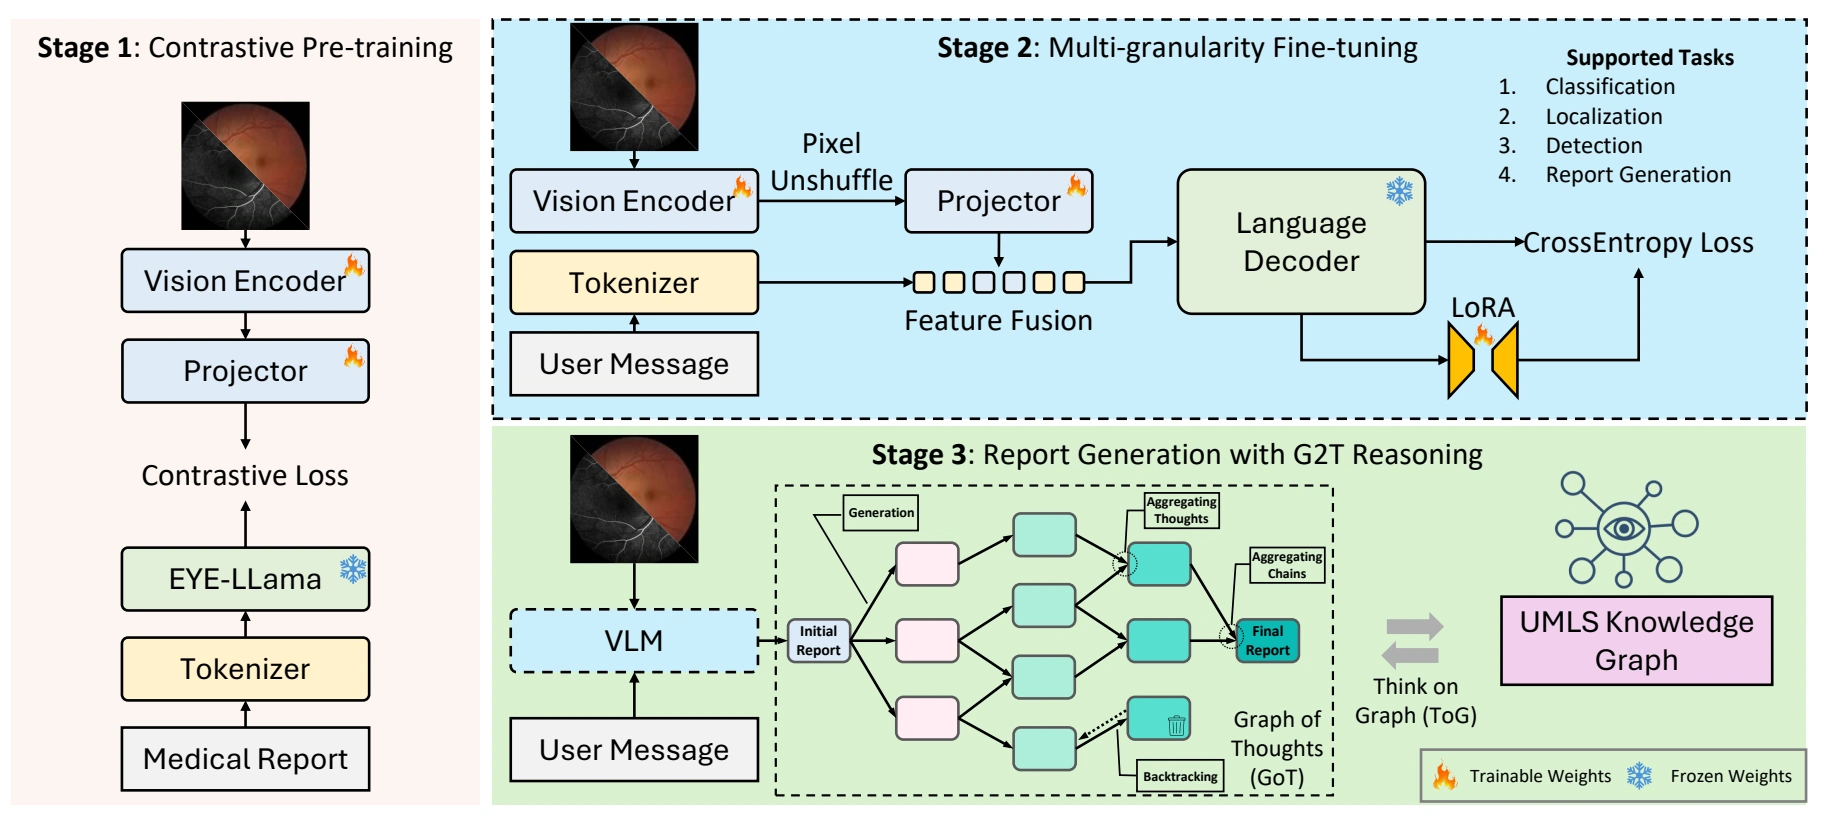
Vision–Language Foundation Models · Knowledge Graph Reasoning · Ophthalmic Image Interpretation

EyeGraph: A Multi-granularity Medical Vision-Language Foundation Model with Knowledge Graph Reasoning for Ophthalmic Interpretation

Zhiyuan Cai*, Yiwei Ren*, Yixiang Liu, Jialin Li, Yijin Huang, Pujin Cheng, Li Lin, Danli Shi, Mingguang He, Hao Chen, Xiaoying Tang

EyeGraph trains one vision–language model for image-level diagnosis, anatomical localization, and report generation using the IT-Retinal instruction dataset. At inference, G2T retrieves relationships from the UMLS knowledge graph and uses them to improve factual consistency in generated reports.
IEEE Transactions on Medical Imaging 2026 (JIF 12.4)PaperCode
Fig. 1 · Source

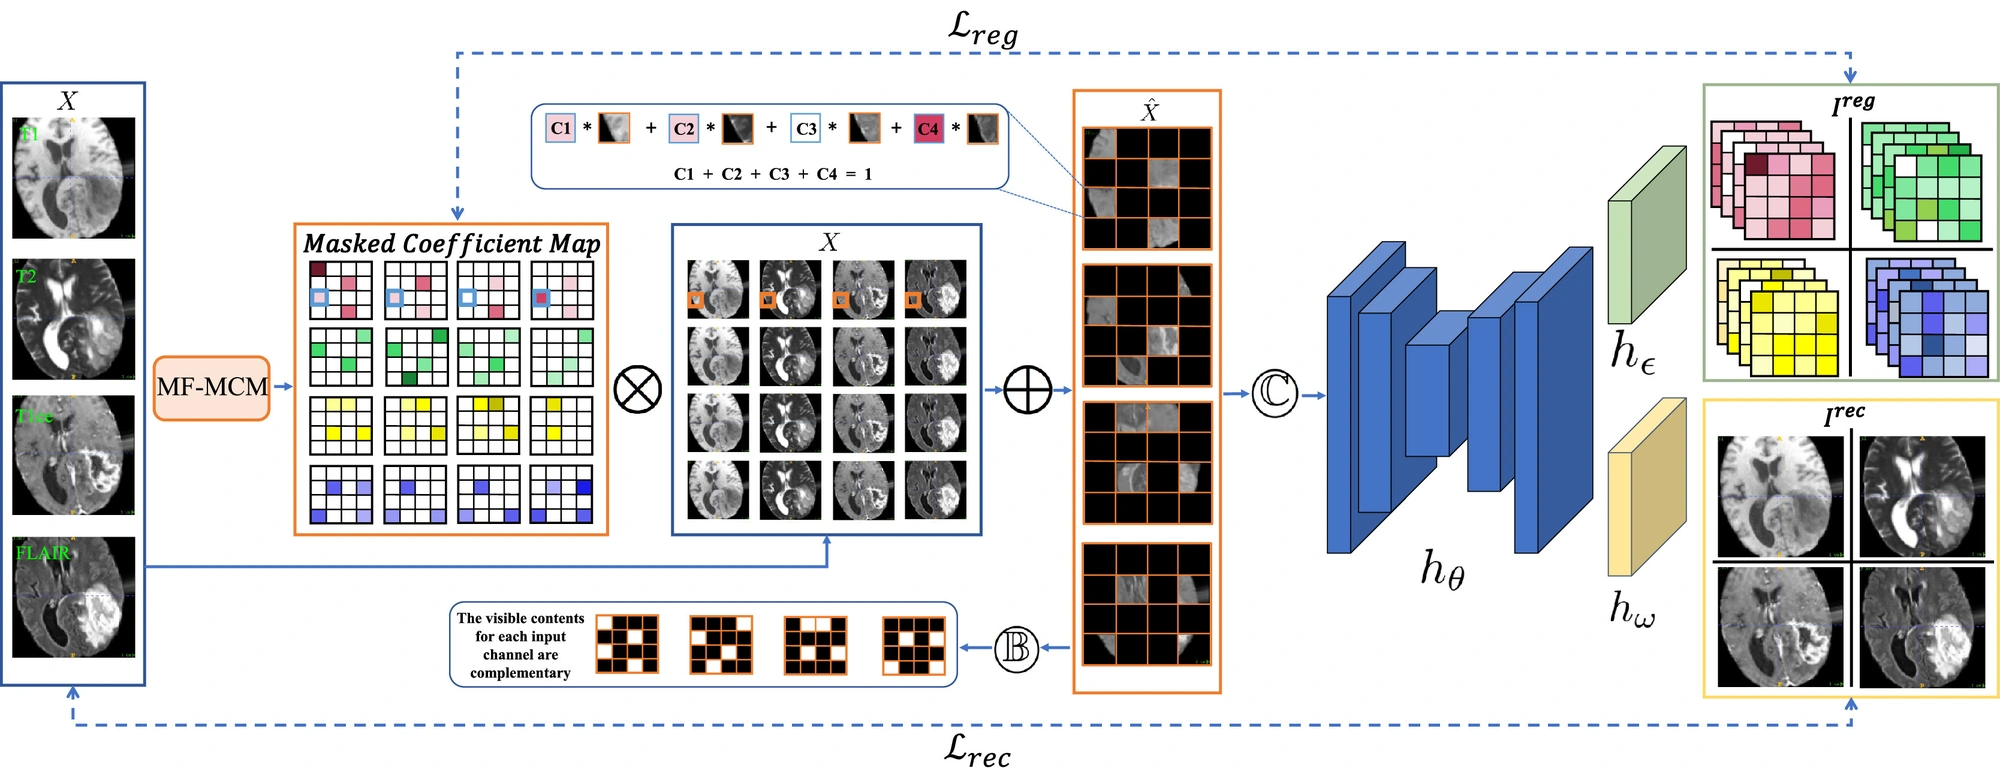
Self-Supervised Pretraining · Masked Complementary Modeling · Multimodal MRI Segmentation

Modality fusion and masked complementary modeling based pre-training for brain tumor segmentation

Jianwen Liang*, Li Lin*, Junyan Lyu, Pujin Cheng, Xiaoying Tang Co-first author

MF-MCM mixes brain MRI sequences and masks complementary regions across the resulting channels. Reconstructing the original sequences and regressing their mixing coefficients trains the encoder to exploit cross-modal information. Transfer is evaluated across five datasets, including experiments with limited labels or missing sequences.

Information Fusion 2026 (JIF 17.4)PaperCode
Fig. 2 · Source · IEEE copyright

Hierarchical Prompting · Bidirectional Consistency Learning · Multi-Granularity Segmentation

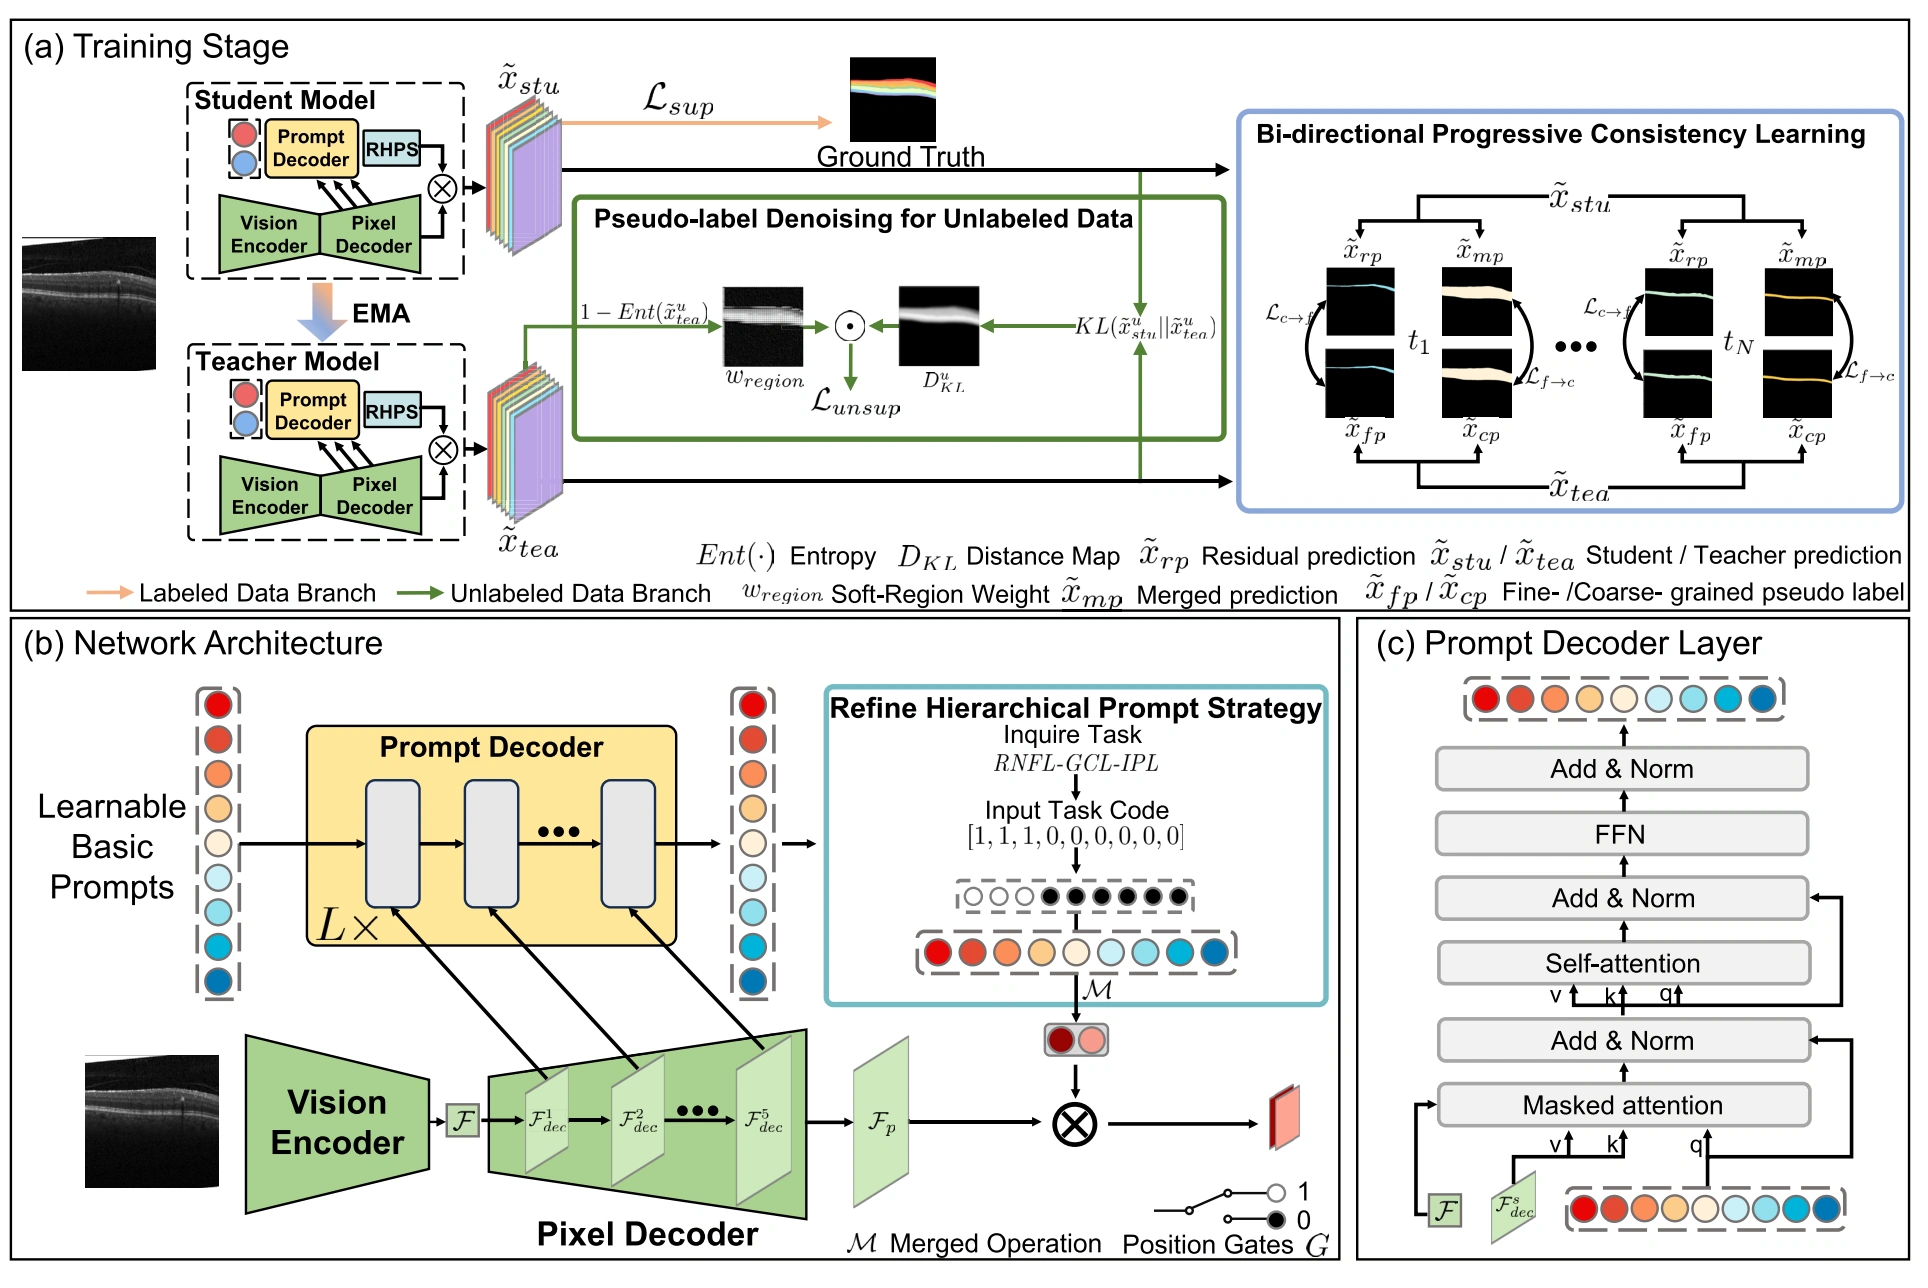
UniOCTSeg++: Refined Hierarchical Prompt Strategy and Bi-Directional Progressive Consistency Learning for Universal Retinal Layer Segmentation in OCT

Jian Zhong*, Li Lin*, Kenneth K. Y. Wong, Xiaoying Tang† Co-first author

UniOCTSeg++ addresses variation in retinal layer definitions by encoding anatomical hierarchies in paired foreground and background prompts and enforcing bidirectional consistency between fine and coarse predictions. On HROCT-Bench, the model approaches fully supervised performance using 30% of the labeled data alongside unlabeled scans.

IEEE Transactions on Medical Imaging 2026 (JIF 12.4)PaperCode
Fig. 6 · Source · CC BY-NC-ND 4.0

Vision Foundation Models · Volumetric OCT · Patient-Level Diagnostic Workflows

Full end-to-end diagnostic workflow automation of 3D OCT via foundation model-driven AI for retinal diseases

Jinze Zhang*, Jian Zhong*, Li Lin*, Jiaxiong Li*, Ke Ma, Naiyang Li, Meng Li, Yuan Pan, Zeyu Meng, Mengyun Zhou, Shang Huang, Shilong Yu, Zhengyu Duan, Sutong Li, Honghui Xia, Juping Liu, Dan Liang, Yantao Wei, Xiaoying Tang†, Jin Yuan†, Peng Xiao† Co-first author

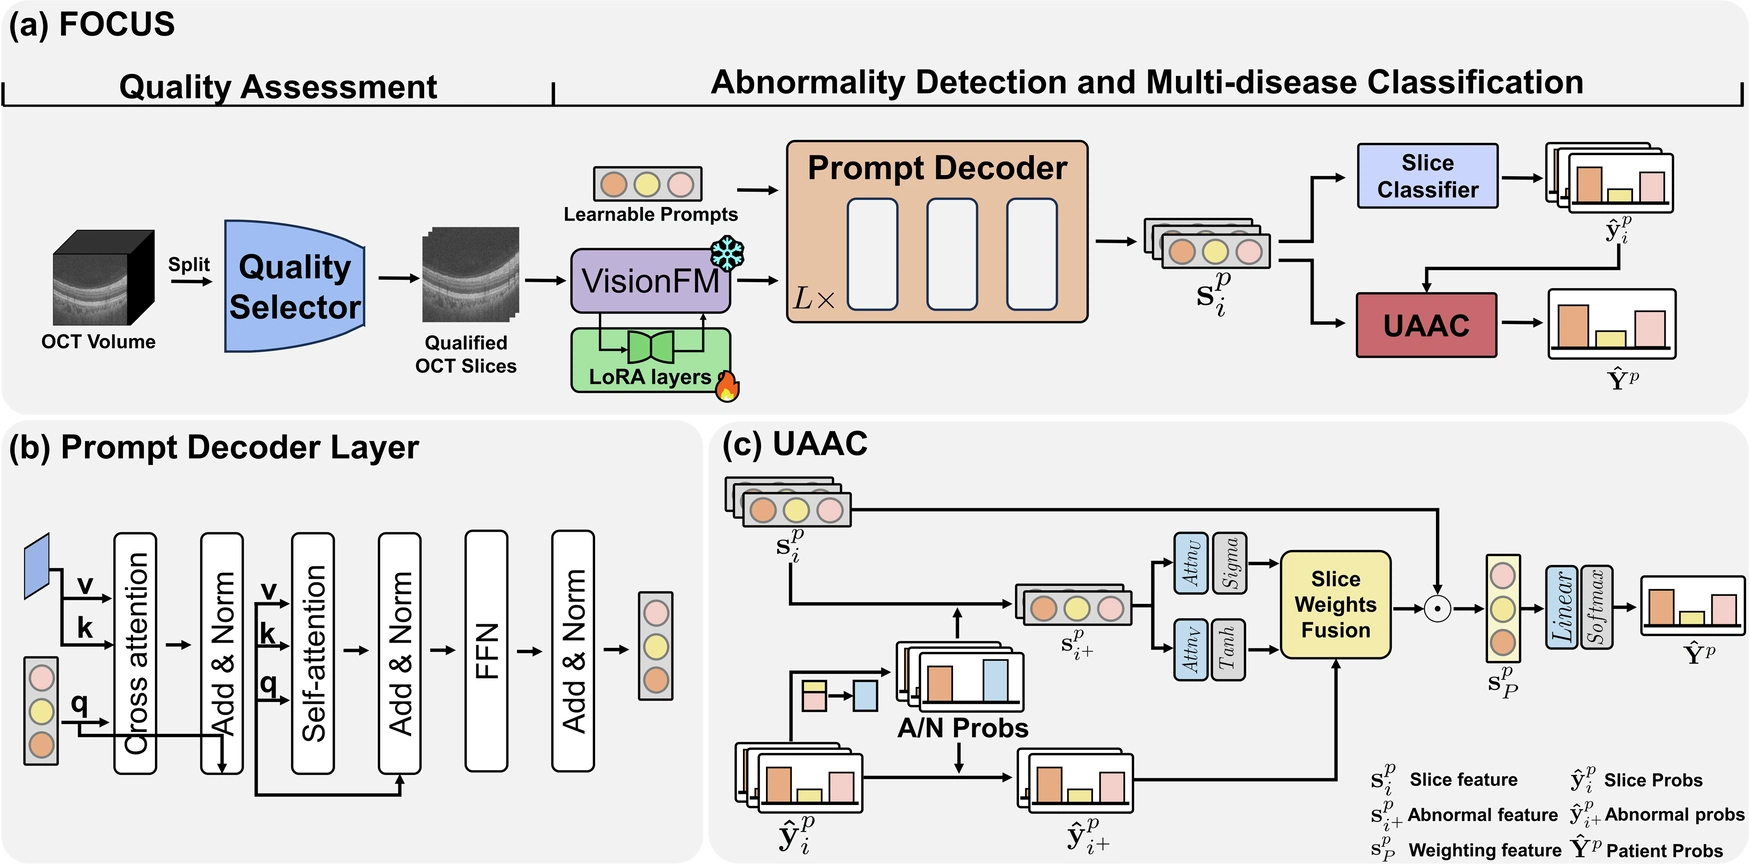
FOCUS integrates slice quality assessment with a fine-tuned VisionFM backbone for abnormality detection and disease classification. Attention-weighted aggregation of abnormal slices yields patient-level diagnoses. In external validation on 1,345 patients across four centers, the pooled patient-level F1 was 94.05%.

npj Digital Medicine 2026 (JIF 18.0)PaperarXiv
Fig. 2 · Source · IEEE copyright

Phase-Conditioned Diffusion · Context-Aware Fusion · Multiphase CT Segmentation

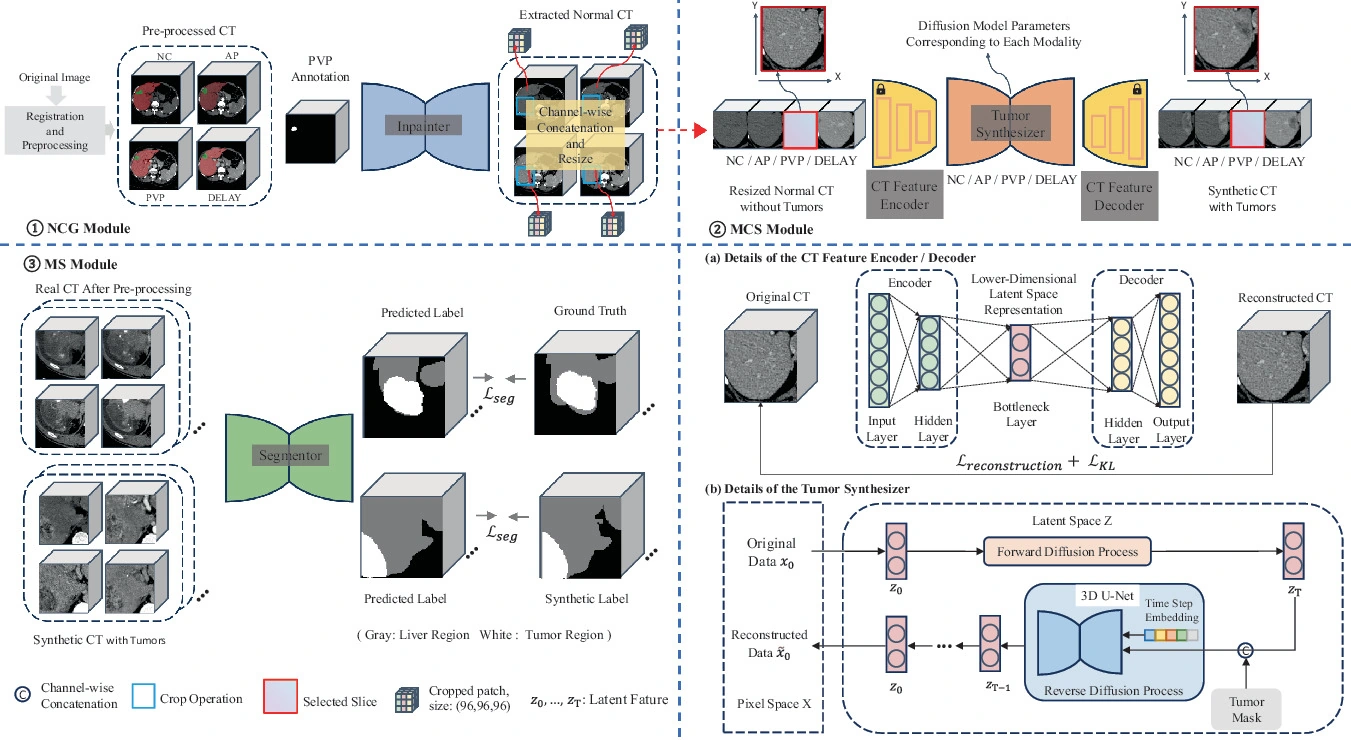
SynLiTS: Phase Prompting-Driven Diffusion Synthesis and Context-Aware Fusion for Unaligned Liver Tumor Segmentation

Shiyun Chen*, Li Lin*, Zhicheng Jin*, Pujin Cheng, Jianjian Chen, Haidong Zhu, Kenneth K. Y. Wong, Xiaoying Tang† Co-first author

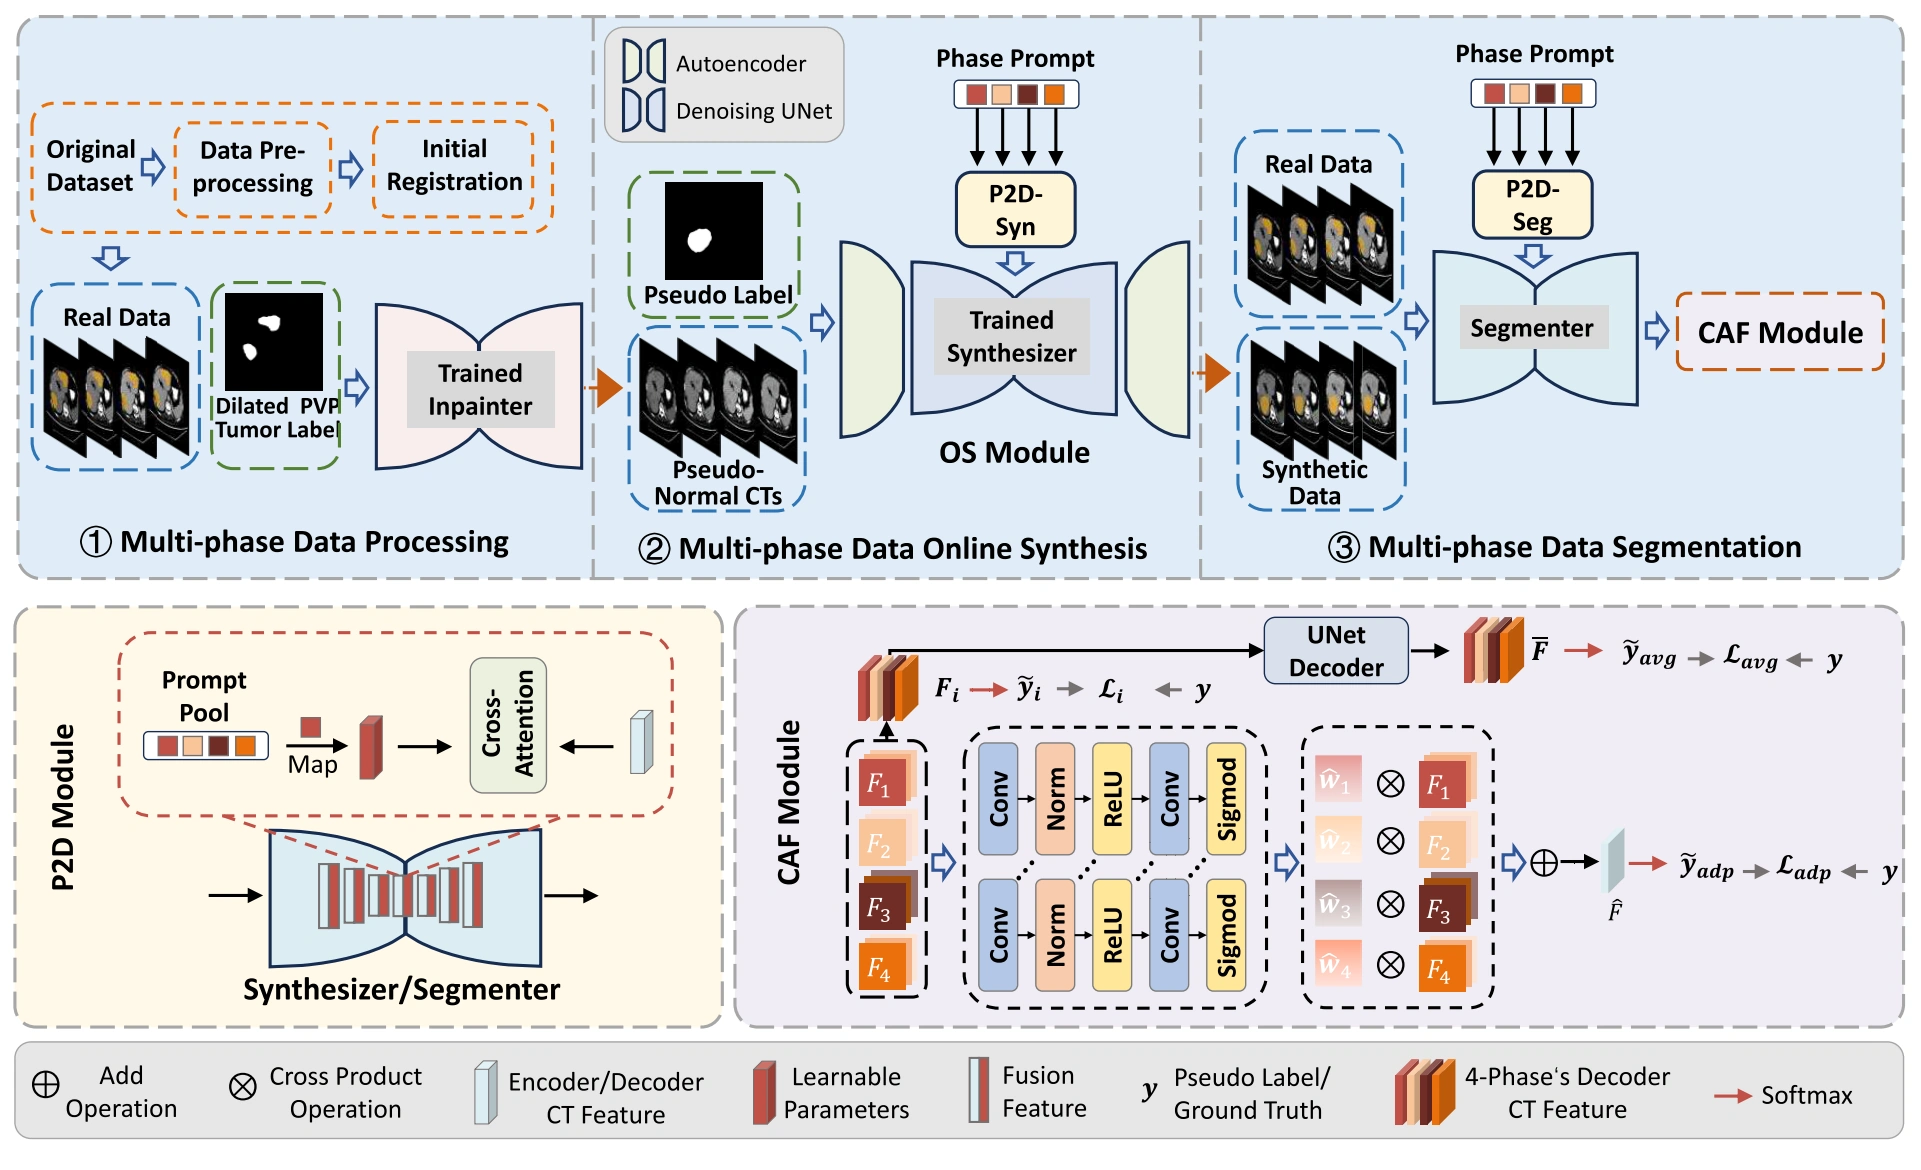
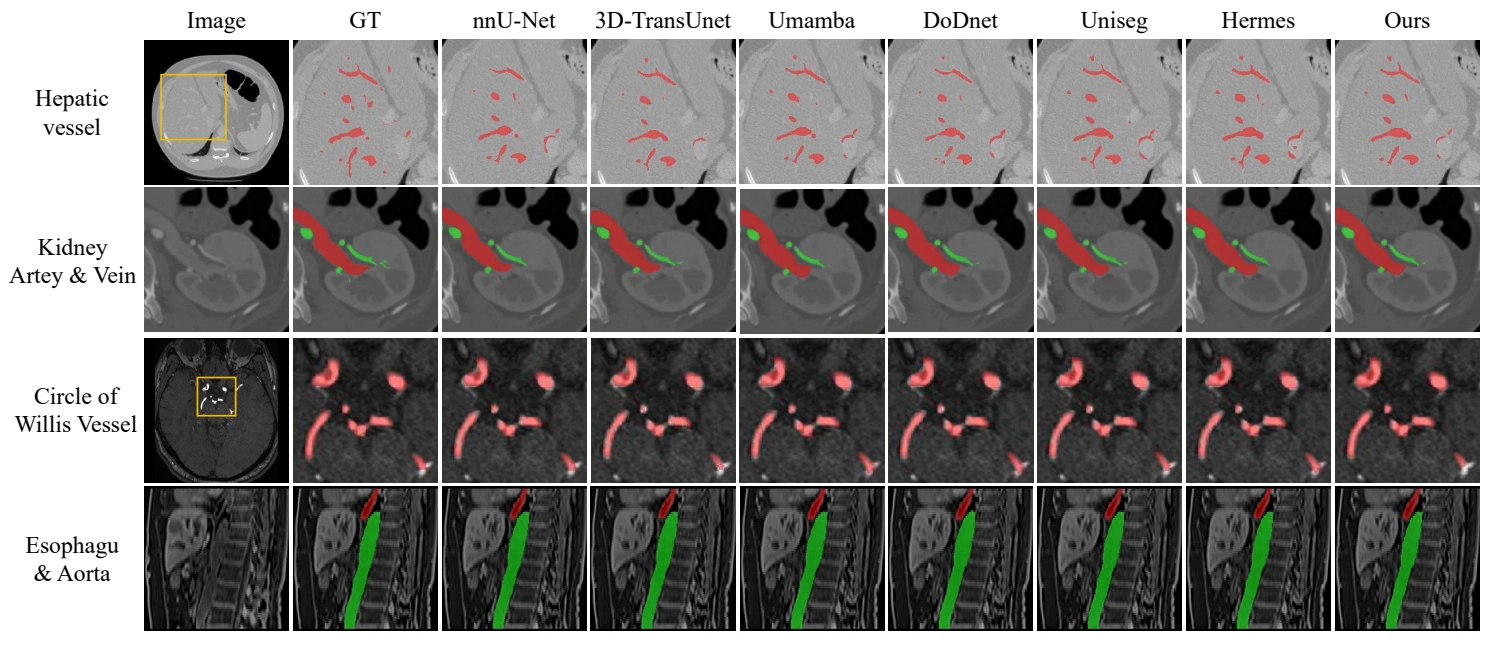
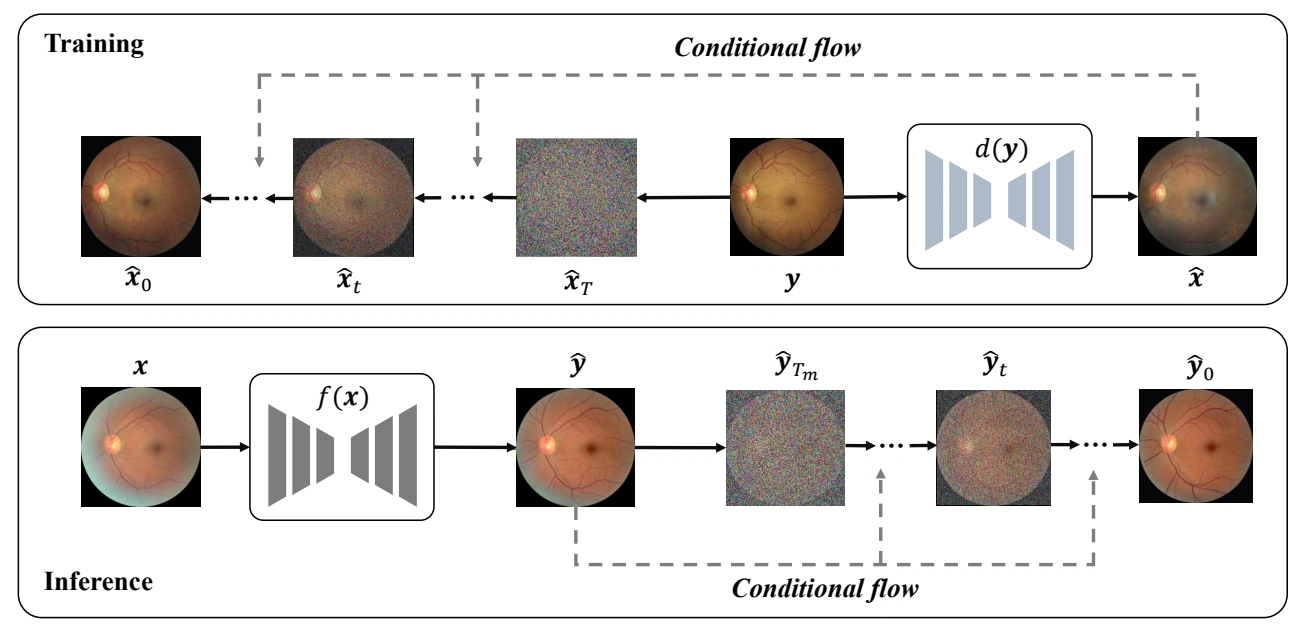
SynLiTS synthesizes liver tumors at matched locations across CT phases using phase-conditioned diffusion. A context-aware segmentation model learns from both the aligned synthetic data and real scans with residual misalignment. The study also introduces MPLiTS, a real multiphase liver tumor dataset.

IEEE Transactions on Medical Imaging 2026 (JIF 12.4)Paper
Fig. 2 · Source · IEEE copyright

Multi-Species 3D Reconstruction · Taxon-Aware Modeling · Diffusion-Based Data Synthesis

AniMer+: Unified Pose and Shape Estimation Across Mammalia and Aves via Family-Aware Transformer

Liang An*, Jin Lyu*, Li Lin, Pujin Cheng, Yebin Liu, Xiaoying Tang

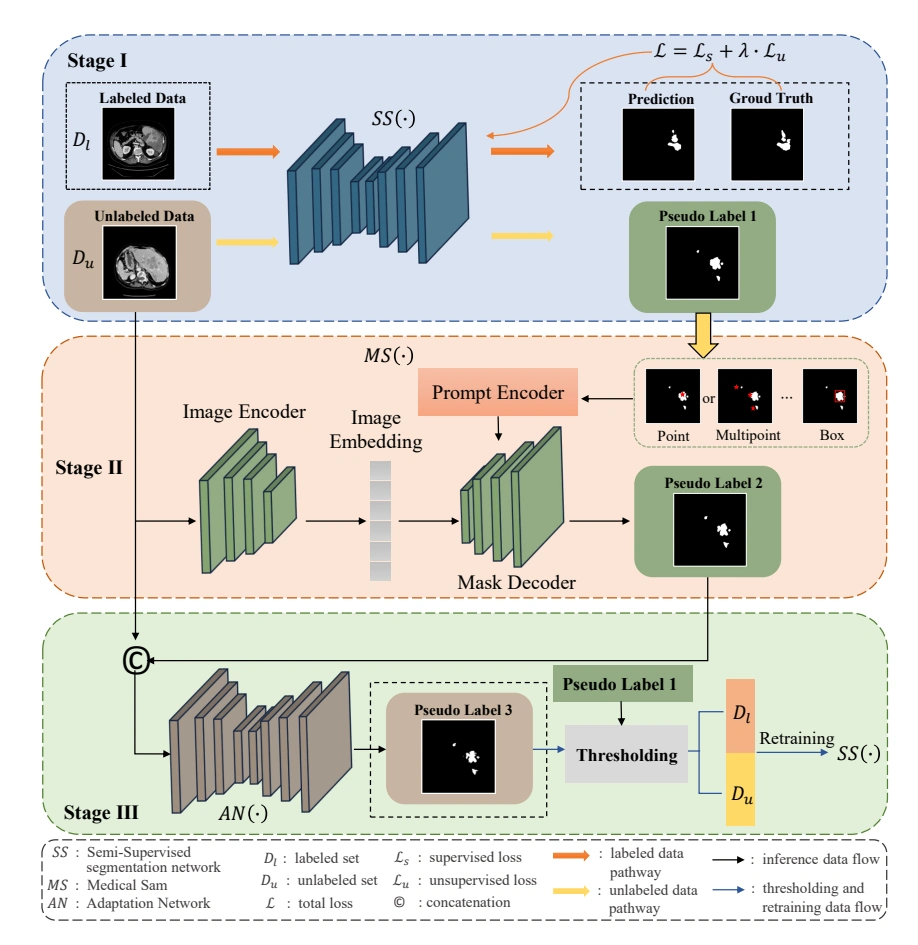
AniMer+ learns one model for 3D pose and shape reconstruction across quadrupedal mammals and birds by combining shared Transformer layers with taxon-specific experts. Diffusion-generated training sets add pixel-aligned 3D annotations, and evaluation includes the out-of-domain Animal Kingdom benchmark.
IEEE Transactions on Pattern Analysis and Machine Intelligence 2026 (JIF 20.4)PaperarXiv Code
Fig. 3 · Fig. 4

Medical Vision–Language Pretraining · Optimal Transport · Robust Contrastive Learning

MIRAGE: Medical image-text pre-training for robustness against noisy environments

Pujin Cheng, Yijin Huang, Li Lin, Junyan Lyu, Kenneth K. Y. Wong, Xiaoying Tang

MIRAGE addresses mismatched image–report pairs and clinically related samples treated as negatives in contrastive pretraining. Optimal transport estimates pairwise correspondence using cross-modal neighbors, and adaptive gradient balancing limits the effect of noisy supervision. Transfer is evaluated on six tasks across 14 datasets.
Medical Image Analysis 2026 (JIF 14.0)PaperCode

2025

Fig. 2 · Source

Hierarchical Prompting · Teacher–Student Consistency · Multi-Granularity Segmentation

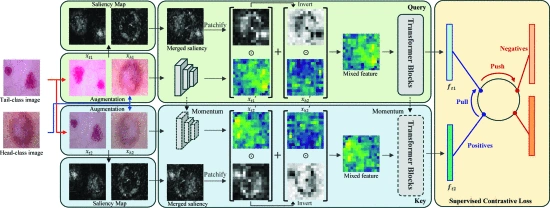
UniOCTSeg: Towards Universal OCT Retinal Layer Segmentation via Hierarchical Prompting and Progressive Consistency Learning

Jian Zhong*, Li Lin*, Chaoran Miao, Kenneth K. Y. Wong, Xiaoying Tang Co-first author

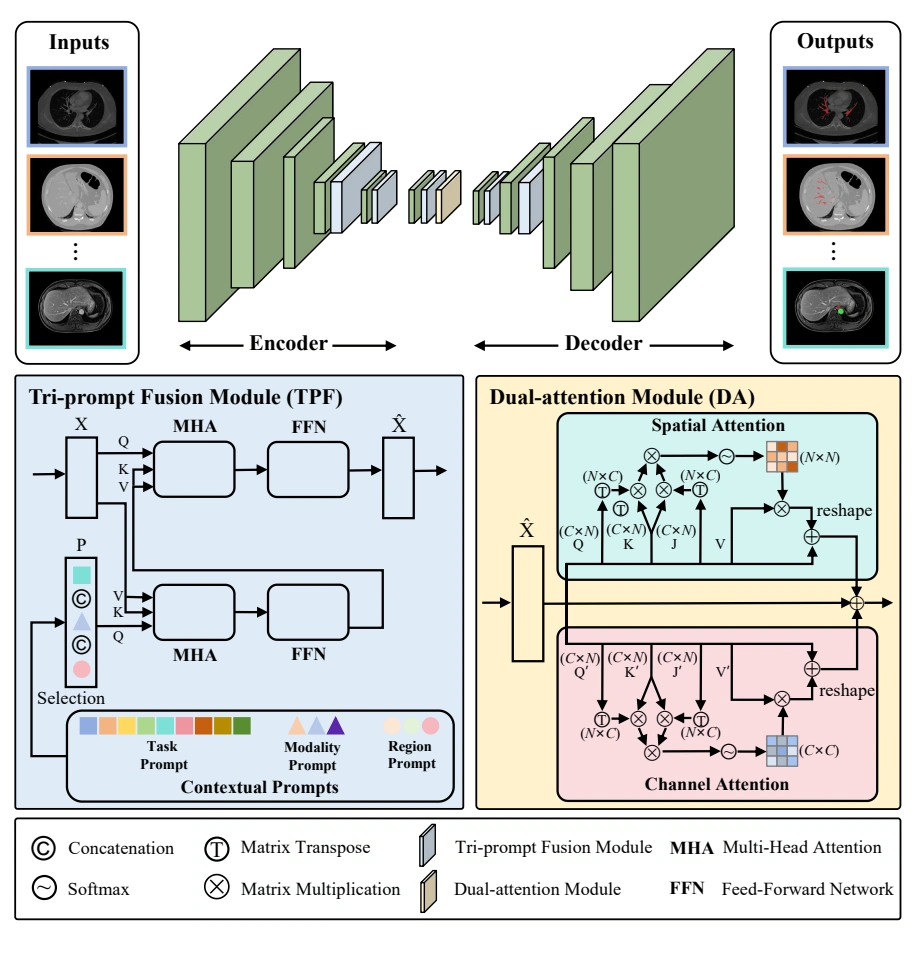
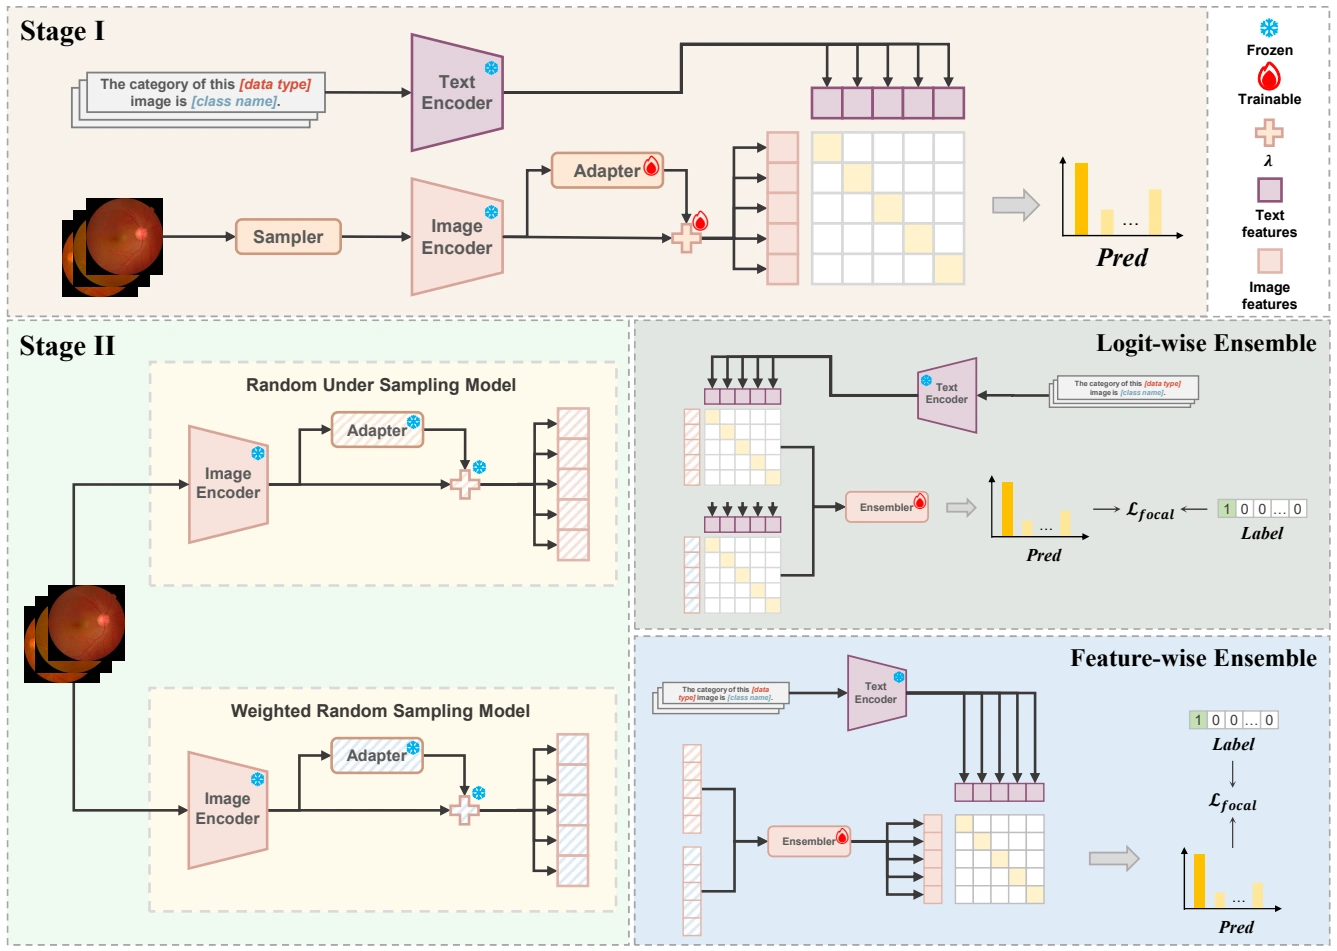
UniOCTSeg composes coarse retinal layer prompts from fine-grained labels, giving a single OCT model an explicit representation of alternative annotation schemes. An exponential-moving-average teacher progressively transfers supervision across the hierarchy, with evaluation on eight datasets spanning six annotation granularities.
MICCAI 2025 (CCF B)PaperCode
Fig. 1 · Source

Evidential Learning · Uncertainty Estimation · PET/CT Fusion

Multi-modal evidential fusion network for trustworthy PET/CT tumor segmentation

Yuxuan Qi*, Li Lin*†, Bin Zhang, Jingya Zhang, Jiajun Wang Co-first author Co-corresponding author

MEFN aligns PET and CT representations, calibrates uncertainty separately for each modality, and combines voxel-level evidence using Dempster–Shafer theory. Evaluation on AutoPET and HECKTOR assesses both delineation accuracy and the uncertainty accompanying a segmentation.

Knowledge-Based Systems 2025 (JIF 8.0)PaperarXiv Code
Fig. 2 · Fig. 4

Single-Image 3D Reconstruction · Family-Supervised Contrastive Learning · Animal Pose and Shape

AniMer: Animal Pose and Shape Estimation Using Family Aware Transformer

Jin Lyu, Tianyi Zhu, Yi Gu, Li Lin, Pujin Cheng, Yebin Liu, Xiaoying Tang, Liang An

AniMer learns a single-image 3D reconstruction model across quadruped families. Family-supervised contrastive learning structures the Transformer’s representation, and CtrlAni3D adds diffusion-generated images with pixel-aligned mesh labels. The study tests reconstruction on both annotated 3D benchmarks and out-of-domain images.

Fig. 2 · Source · IEEE copyright

Weakly Supervised Segmentation · Prototype Calibration · Pseudo-Label Noise Suppression

ProCNS: Progressive Prototype Calibration and Noise Suppression for Weakly-Supervised Medical Image Segmentation

Yixiang Liu*, Li Lin*, Kenneth K. Y. Wong, Xiaoying Tang† Co-first author

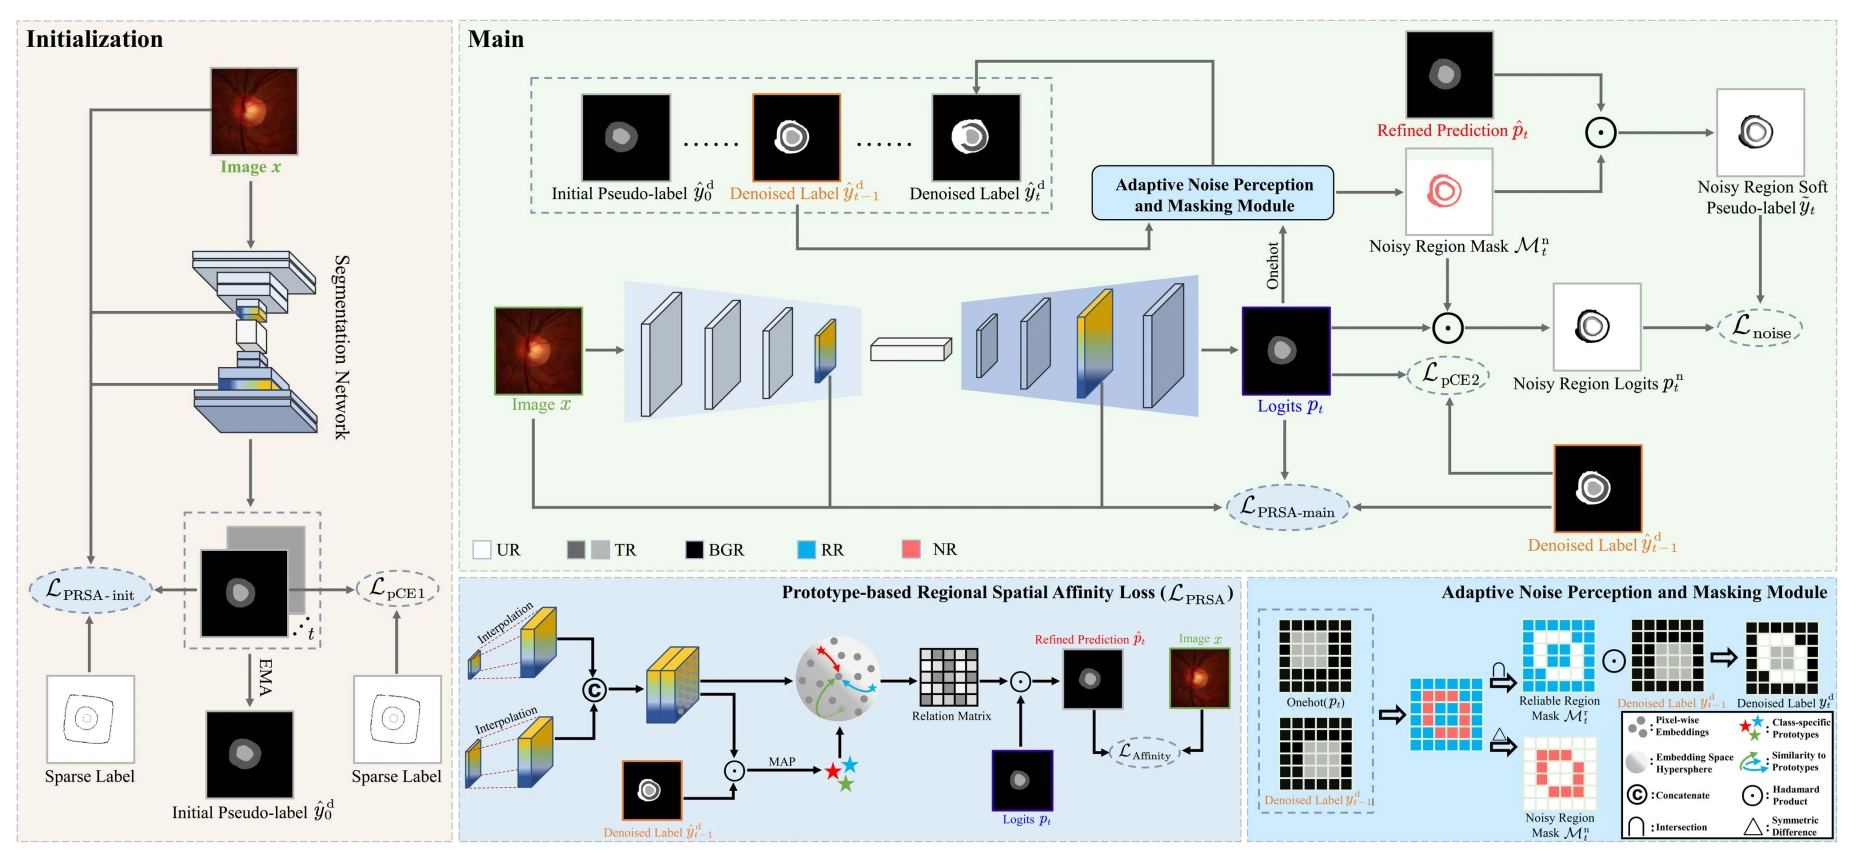
ProCNS addresses error accumulation when sparse marks are expanded into dense supervision. It encodes region-level spatial and semantic affinities from refined prototypes, excludes unreliable pixels from prototype updates, and uses targeted soft labels to retain supervision in those regions.

IEEE Journal of Biomedical and Health Informatics 2025 (JIF 7.7)PaperarXiv Code
Fig. 2 · Fig. 5 · IEEE copyright

Personalized Federated Learning · Prompt Learning · Heterogeneous Weak Supervision

FedLPPA: Learning Personalized Prompt and Aggregation for Federated Weakly-Supervised Medical Image Segmentation

Li Lin*, Yixiang Liu*, Jiewei Wu*, Pujin Cheng, Zhiyuan Cai, Kenneth K. Y. Wong, Xiaoying Tang First author

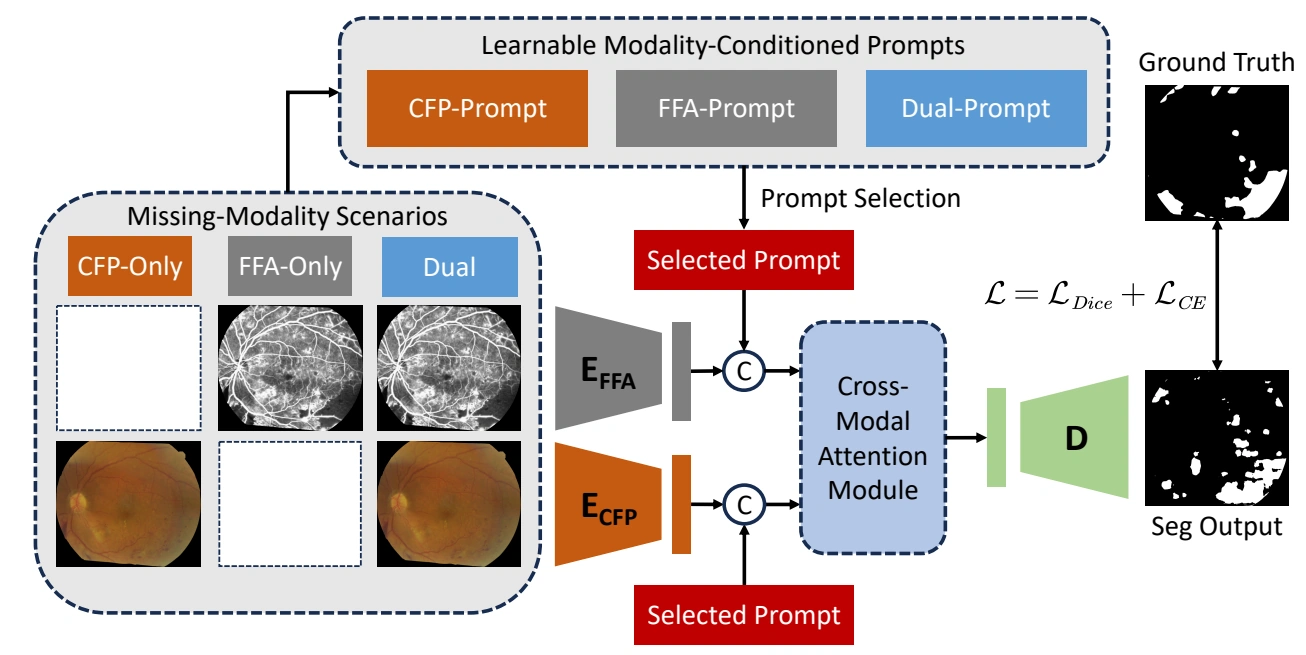
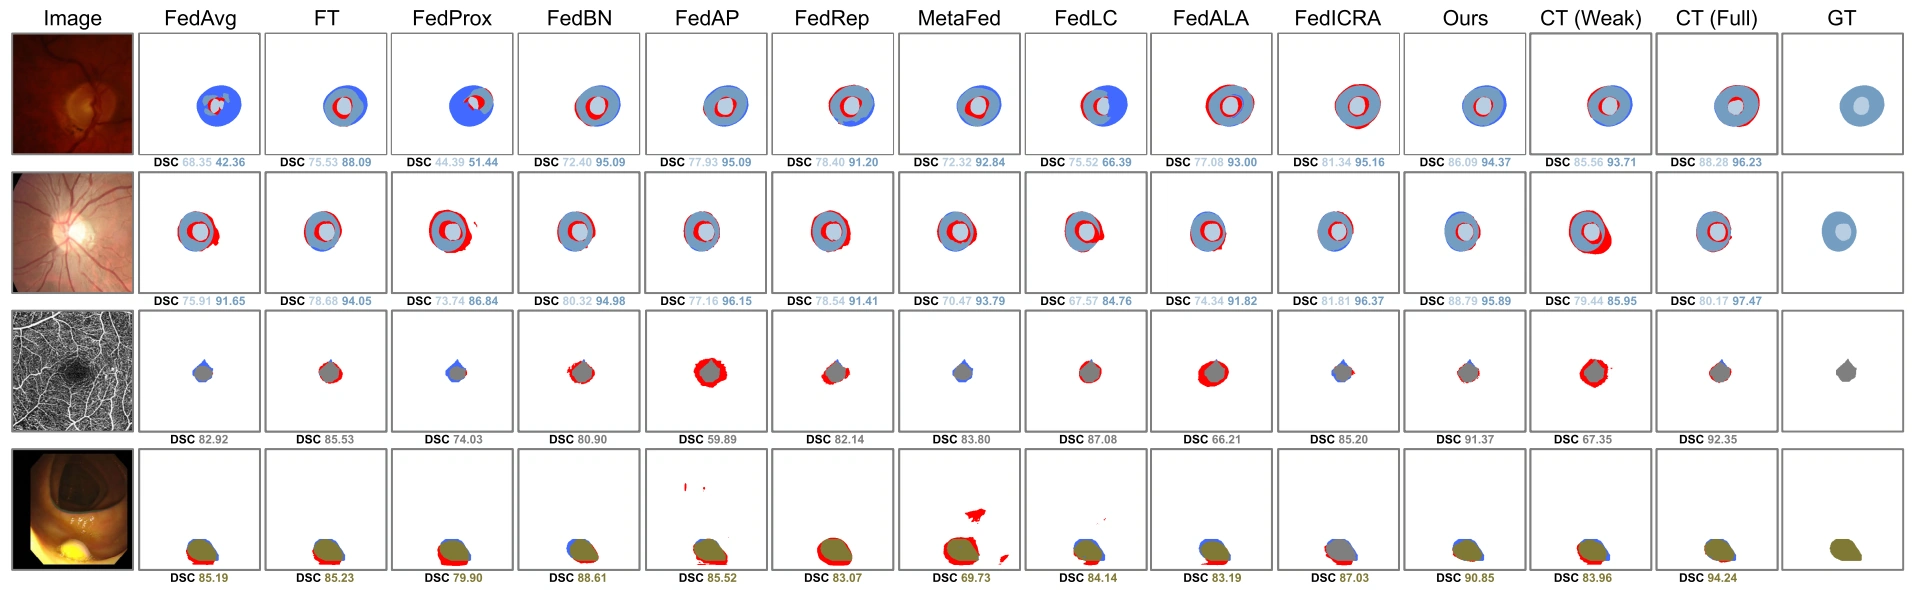
FedLPPA uses distinct prompts to encode shared knowledge, site-specific imaging distributions, and annotation sparsity. Prompt similarity guides pseudo-labeling in a dual-decoder design, while parameter-wise aggregation personalizes each local decoder. Evaluation spans four segmentation tasks with heterogeneous weak supervision.

IEEE Transactions on Medical Imaging 2025 (JIF 12.4)PaperarXiv Code

2024

Fig. 2 · Source · IEEE copyright

Arbitrary-Scale Super-Resolution · Cross-Contrast Translation · Isotropic MRI Reconstruction

Joint super-resolution and modality translation network for multi-contrast arbitrary-scale isotropic MRI reconstruction

Kai Pan, Li Lin, Pujin Cheng, Junyan Lyu, Xiaoying Tang

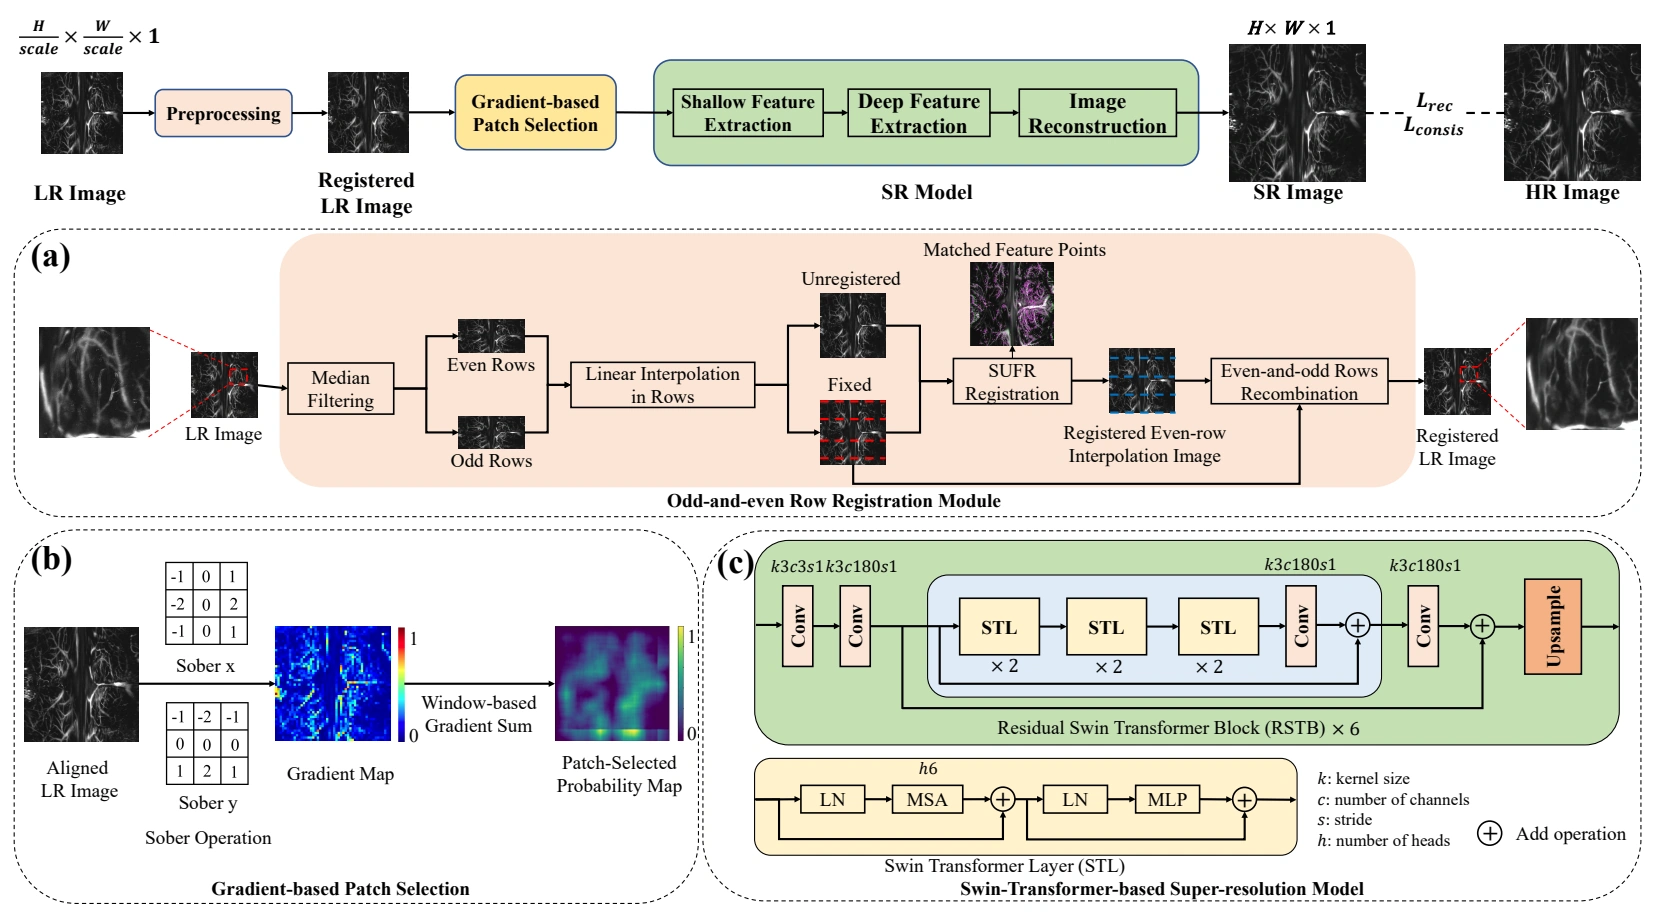
SMNet reconstructs isotropic MRI at variable upsampling scales from anisotropic scans and a high-resolution reference contrast. Separate branches handle cross-contrast alignment and spatial restoration, with reliability-weighted fusion controlling how reference features contribute to the reconstruction.

IEEE BIBM 2024 (CCF B)Paper
Fig. 2 · Source · IEEE copyright

Masked Modeling · Self-Supervised Pretraining · Multimodal MRI Segmentation

Masked Modality Complementary Modeling for Brain Tumor Segmentation

Jianwen Liang*, Li Lin*, Junyan Lyu*, Xiaoying Tang† Co-first author

MMCM gives different MRI sequences complementary masks, so recovering a missing region requires features from other sequences. The resulting self-supervised encoder was tested on BraTS 2021, including limited training data and single-sequence inputs.

IEEE BIBM 2024 (CCF B)Paper
Fig. 1 · Source · IEEE copyright

Multimodal Self-Supervised Pretraining · Entropy-Guided Masking · 2D and 3D Ophthalmic Imaging

Uni4Eye++: A General Masked Image Modeling Multi-Modal Pre-Training Framework for Ophthalmic Image Classification and Segmentation

Zhiyuan Cai, Li Lin, Huaqing He, Pujin Cheng, Xiaoying Tang†

Uni4Eye++ pools unlabeled 2D ophthalmic images and 3D volumes for masked pretraining. Entropy-guided masking targets informative regions, and dynamic reconstruction heads account for modality-specific image characteristics. The shared encoder is then transferred to classification and segmentation.

IEEE Transactions on Medical Imaging 2024 (JIF 12.4)PaperCode
Fig. 2 · Source

Anatomical Priors · Coarse-to-Fine Refinement · Multi-Task Learning

JOINEDTrans: Prior guided multi-task transformer for joint optic disc/cup segmentation and fovea detection

Huaqing He*, Jiaming Qiu*, Li Lin*, Zhiyuan Cai, Pujin Cheng, Xiaoying Tang† Co-first author

JOINEDTrans learns a spatial prior from retinal vessel segmentation and transfers it to optic disc and cup delineation and fovea localization. Its coarse-to-fine Transformer uses initial predictions to guide localized refinement, with evaluation on GAMMA, REFUGE, and PALM.

Computers in Biology and Medicine 2024 (JIF 6.3)Paper
Fig. 2 · Source

Personalized Federated Learning · Similarity-Aware Distillation · Heterogeneous Weak Annotations

pFedWSD: unified weakly supervised personalized federated image segmentation via similarity-aware distillation

Jianshan Pan, Li Lin, Jiewei Wu, Yixiang Liu, Xiaohua Chen, Qiyou Lin, Jianye Huang, Xiaoying Tang† First student author

pFedWSD uses cyclic distillation to consolidate knowledge across sites, then estimates site similarity from batch-normalization statistics to construct personalized teachers. The framework supports federated segmentation across institutions with both different data distributions and different forms of sparse annotation.

Journal of Image and Graphics 2024 (CCF B / T2)Paper

2023

Fig. 2 · Source

Single-Skeleton Supervision · Contrastive Image Synthesis · Curvilinear Structure Segmentation

YoloCurvSeg: You only label one noisy skeleton for vessel-style curvilinear structure segmentation

Li Lin, Linkai Peng, Huaqing He, Pujin Cheng, Jiewei Wu, Kenneth K. Y. Wong, Xiaoying Tang First author

YoloCurvSeg uses one noisy skeleton annotation to build dense supervision for vessels and other curvilinear structures. A patchwise contrastive synthesizer combines simulated curves with inpainted image backgrounds. With this annotation budget, it retains over 97% of fully supervised performance on each of four public datasets.

Medical Image Analysis 2023 (JIF 14.0)PaperarXiv Code
Fig. 2 · Source

Personalized Federated Learning · Site-Contrastive Representation Learning · Adaptive Aggregation

Unifying and Personalizing Weakly-Supervised Federated Medical Image Segmentation via Adaptive Representation and Aggregation

Li Lin, Jiewei Wu, Yixiang Liu, Kenneth K. Y. Wong, Xiaoying Tang First author

FedICRA personalizes segmentation across institutions with different sparse labels and image distributions. Site-contrastive learning organizes selected feature channels around institution-specific structure, and element-wise aggregation blends local parameters with shared knowledge.

MLMI at MICCAI 2023PaperCode
Fig. 2 · Fig. 4

Medical Vision–Language Pretraining · Prototype Learning · Local and Global Alignment

PRIOR: Prototype Representation Joint Learning from Medical Images and Reports

Pujin Cheng, Li Lin, Junyan Lyu, Yijin Huang, Wenhan Luo, Xiaoying Tang

PRIOR aligns medical images and reports at image and region scales. Cross-modal reconstruction and a bank of sentence prototypes help the shared representation retain localized imaging cues and clinical language. Evaluation spans five transfer tasks, including zero-shot classification, image–text retrieval, and dense prediction.

2022

Fig. 1 · Source · CC BY 4.0

Anatomical Priors · Landmark Localization · Multi-Task Segmentation

JOINED: Prior Guided Multi-task Learning for Joint Optic Disc/Cup Segmentation and Fovea Detection

Huaqing He*, Li Lin*, Zhiyuan Cai, Xiaoying Tang Co-first author

JOINED uses pixel-to-landmark distances as auxiliary supervision for joint optic disc and cup segmentation and fovea localization. Initial masks and heatmaps locate regions of interest, which a second stage refines at higher spatial detail.

MIDL 2022Paper
Fig. 2 · Fig. 3 · IEEE copyright

Domain Generalization · Augmentation Policy Search · Optimal Transport

AADG: Automatic Augmentation for Domain Generalization on Retinal Image Segmentation

Junyan Lyu, Yiqi Zhang, Yijin Huang, Li Lin, Pujin Cheng, Xiaoying Tang†

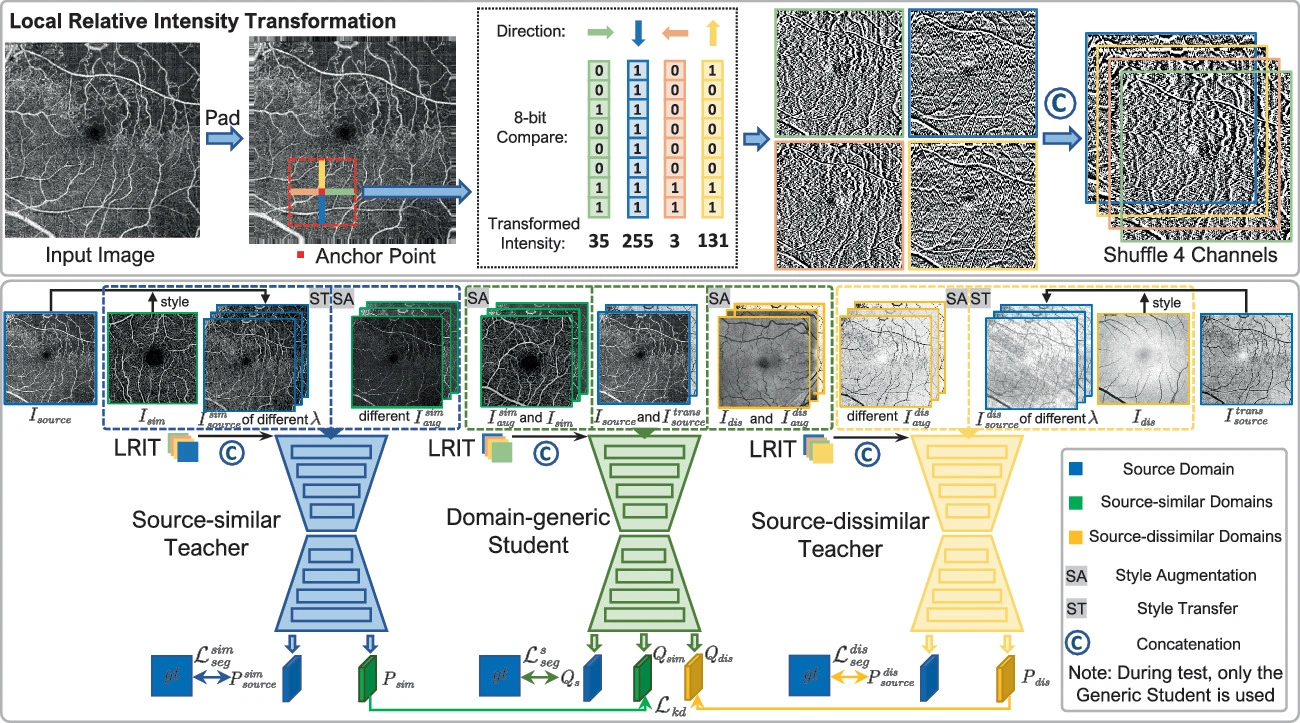
AADG learns data augmentation policies by maximizing Sinkhorn distances between augmented training domains in feature space. The learned policies are evaluated on 11 fundus datasets and two OCT angiography datasets, testing generalization to unseen datasets and a different imaging modality.

IEEE Transactions on Medical Imaging 2022 (JIF 12.4)PaperarXiv Code
Fig. 1 · Source

Difficulty-Aware Learning · Semi-Supervised Synthesis · Contrast-Enhanced MRI

DS³-Net: Difficulty-Perceived Common-to-T1ce Semi-supervised Multimodal MRI Synthesis Network

Ziqi Huang, Li Lin, Pujin Cheng, Kai Pan, Xiaoying Tang

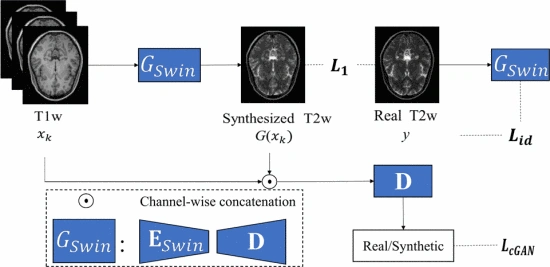
DS³-Net synthesizes contrast-enhanced T1 MRI by learning from paired and unpaired scans. A predicted difficulty map guides pixelwise and patchwise objectives toward hard-to-reconstruct regions. On BraTS 2020, the method remains competitive with fully paired translation methods using 5% paired data.

MICCAI 2022 (CCF B)Paper
Fig. 1 · Source

Multimodal Self-Supervised Pretraining · Masked Image Modeling · Ophthalmic Classification

Uni4Eye: Unified 2D and 3D Self-supervised Pre-training via Masked Image Modeling Transformer for Ophthalmic Image Classification

Zhiyuan Cai*, Li Lin*, Huaqing He, Xiaoying Tang Co-first author

Uni4Eye uses a common patch embedding to pretrain a vision Transformer jointly on 2D ophthalmic images and 3D volumes. Reconstructing both masked image intensities and gradients supplies complementary supervision, with transfer evaluated on six classification tasks.

MICCAI 2022 (CCF B)PaperarXiv

2021

Fig. 1 · Source

Geometry-Aware Learning · Joint Segmentation and Classification · OCT Angiography

BSDA-Net: A Boundary Shape and Distance Aware Joint Learning Framework for Segmenting and Classifying OCTA Images

Li Lin, Zhonghua Wang, Jiewei Wu, Yijin Huang, Junyan Lyu, Pujin Cheng, Jiong Wu, Xiaoying Tang First author

BSDA-Net learns the geometry of the foveal avascular zone by regressing boundary heatmaps and reconstructing signed distance maps alongside segmentation. A hierarchical fusion module passes the resulting structural features to a diagnostic classifier, linking geometric delineation with classification.

Fig. 1 · Source

Semi-Supervised Learning · Importance-Guided Contrastive Learning · Fundus Image Enhancement

I-secret: Importance-guided fundus image enhancement via semi-supervised contrastive constraining

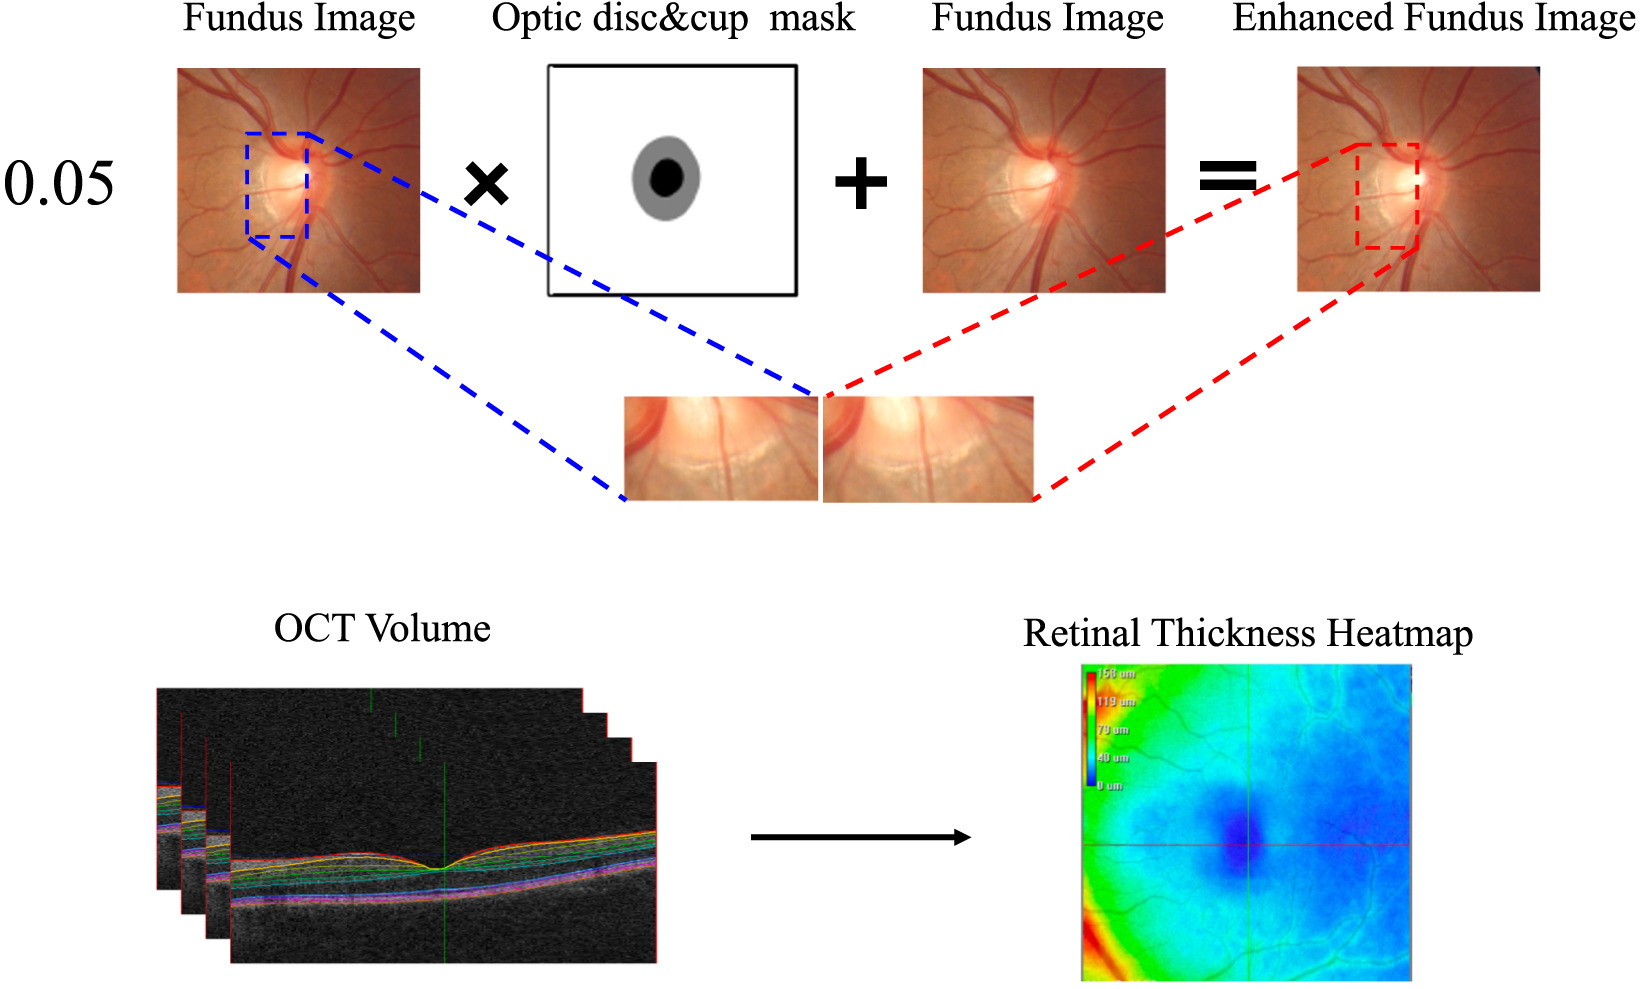
Pujin Cheng, Li Lin, Yijin Huang, Junyan Lyu, Xiaoying Tang

I-SECRET learns fundus image enhancement by combining paired synthetic degradations with unpaired clinical images. A pixelwise importance estimator guides supervised reconstruction and contrastive learning in the two branches.

MICCAI 2021 (CCF B)Paper
Fig. 2 · Source

Self-Supervised Contrastive Learning · Lesion-Aware Representations · Diabetic Retinopathy Grading

Lesion-based contrastive learning for diabetic retinopathy grading from fundus images

Yijin Huang, Li Lin, Pujin Cheng, Junyan Lyu, Xiaoying Tang

This study uses lesion-centered patches as inputs to self-supervised contrastive learning, encouraging representations sensitive to small pathological features for diabetic retinopathy grading. Linear probing and transfer experiments on EyePACS assess the learned features.

MICCAI 2021 (CCF B)Paper
Fig. 2 · Source · IEEE copyright

Contrastive Image Synthesis · Confocal Microscopy · Corneal Nerve Segmentation

Automated segmentation of corneal nerves in confocal microscopy via contrastive learning based synthesis and quality enhancement

Li Lin, Pujin Cheng, Zhonghua Wang, Meng Li, Kai Wang, Xiaoying Tang First author

This pipeline pairs image synthesis with enhancement to address unreliable labels and uneven illumination in corneal confocal microscopy. Multilayer patch contrastive learning supplies anatomically consistent training examples for corneal nerve segmentation, evaluated on two public datasets.

IEEE ISBI 2021Paper
Fig. 1 · Fig. 4

Bidirectional ConvLSTM · Adversarial Learning · Retinal Vessel Segmentation

BLU-GAN: Bi-directional ConvLSTM U-Net with Generative Adversarial Training for Retinal Vessel Segmentation

Li Lin, Jiewei Wu, Pujin Cheng, Kai Wang†, Xiaoying Tang† First author

BLU-GAN replaces U-Net's direct skip connections with bidirectional convolutional LSTM units that integrate features across scales. Adversarial training and dense feature reuse complement the recurrent design for fundus vessel delineation.

BenchCouncil FICC 2020Best Paper AwardPaper

2020

Fig. 5 · Source · CC BY 4.0

Dataset Curation · Exudate Detection · Multi-Protocol Retinopathy Grading

The SUSTech-SYSU dataset for automated exudate detection and diabetic retinopathy grading

Li Lin*, Meng Li*, Yijin Huang*, Pujin Cheng, Honghui Xia, Kai Wang, Jin Yuan†, Xiaoying Tang† First author

This dataset provides 1,219 fundus photographs annotated for exudates, optic disc location, and the foveal center, with diabetic retinopathy grades from three protocols. The shared annotations support lesion identification, landmark localization, and comparisons across grading conventions.

Scientific Data 2020 (JIF 7.2)PaperCode Data
Fig. 2 · Source · IEEE copyright

Weak Annotations · Bounding-Box Refinement · Hemorrhage Detection

Automated hemorrhage detection from coarsely annotated fundus images in diabetic retinopathy

Yijin Huang*, Li Lin*, Meng Li, Jiewei Wu, Pujin Cheng, Kai Wang, Jin Yuan, Xiaoying Tang† Co-first author

This weakly supervised detector addresses localization noise in manually drawn hemorrhage boxes. A bounding-box regressor first refines the annotations, and a label-smoothed RetinaNet then learns lesion detection from the revised supervision.

IEEE ISBI 2020Paper

Academic Service

Journal Reviewer
Conference Reviewer
  • IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) (CCF A)
  • IEEE/CVF International Conference on Computer Vision (ICCV) (CCF A)
  • AAAI Conference on Artificial Intelligence (AAAI) (CCF A)
  • Annual Meeting of the Association for Computational Linguistics (ACL) (CCF A)
  • International Conference on Medical Image Computing and Computer-Assisted Intervention (MICCAI) (CCF B)
  • IEEE International Symposium on Biomedical Imaging (ISBI)

WeChat

WeChat contact QR code

Scan in WeChat and include a brief introduction and the reason for reaching out in your friend request.

Open figure source ↗